
Notizen
week10
Inhalt der Notizen (6)
Seite 1
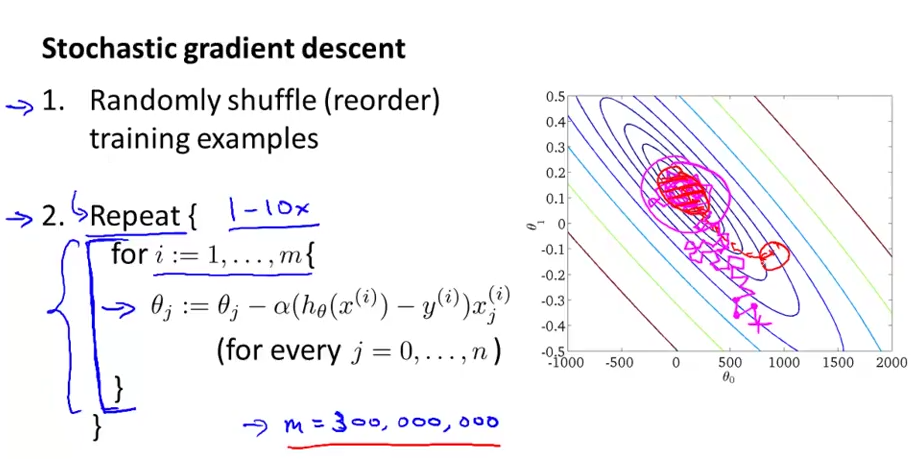
stochastic gradient descent : for dealing with large datasets - where batch gradient descent will be slower; because batch uses all 'm' examples in each iteration;
randomly shuffle dataset
then use below algorithm : use 1 data set for each iteration
Seite 2
mini-batch gradient descent:
for m = 300,000,000 (say US population data)
use : b =10 and perform batch gradient
Seite 3
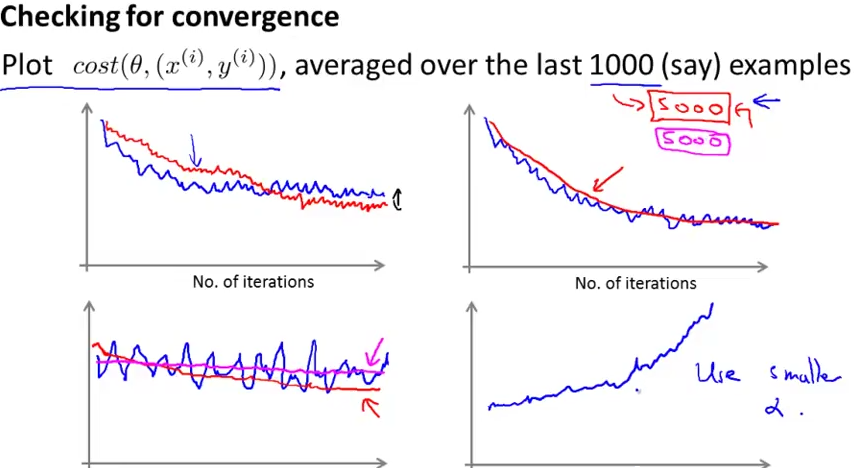
how to monitor stochastic gradient?
plot cost (thetai , xi) averaged over last 1000 examples
Seite 4
online learning: learning based on user data through online
find p(y=1 |x) ;
repeat forever {
given x, y corresponding to user;
update theta;
}
Seite 5
application:
predicted click thru rate:
for customer search say a phone :
show 10 best guesses that user may like :
find p(y=1|x ; theta) : how many links user clicked that was shown
Seite 6
Map reduce:
divide training set data into equal proportions
send each data set to a computer for computing the cost
then combine all the cost in a single server
use this approach to speed up the computation
can be used within a single computer with mulitple cores
Informationen
- Beschreibung
- Machine Learning Notiz am week10, erstellt von Mukundhan Srinivasan am 23/06/2018.
- Erstellt von
- Mukundhan Srinivasan
- Aufrufe
- 1
- Bewertung