
Test
SDP10 Final - Part I
Preguntas del test (200)
1In given two C modules which rule will Unix linker use to resolve multiple symbol definition?
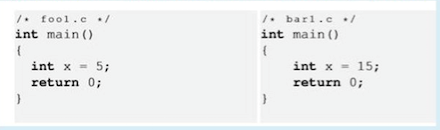
- AMultiple strong symbols are not allowed
- BNone of these
- CGiven multiple weak symbols, chose any of the weak symbols
- DGiven a strong symbol and multiple weak symbols, choose the strong symbol.
2Suppose we attempt to compile and link the following two C modules. Linker will generate an error?
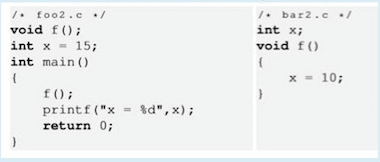
- Atrue
- Bfalse
3Suppose we attempt to compile and link the following two C modules. Linker will generate an error?
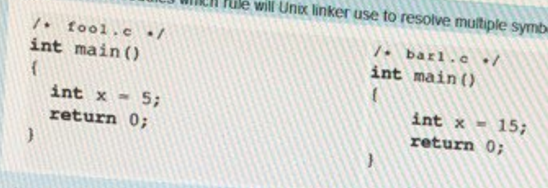
- Atrue
- Bfalse
4A branch instruction
- ASets the program counter to one of two possible values
- BIncreases the program counter by a fixed amount
- CSets the program counter to one of many possible values
- DUnconditionally sets the program counter to its operand
5In binary, the number 1/3 is 0.01010101 . . .. In the following, assume that x is an int and y is a short. (short)((0x5555 * (int)y)>>16) and y/3 could differ even when neither computation overflows
- ATrue
- BFalse
6A callee-saved register should be saved before it is written to in a procedure
- ATrue
- BFalse
7In binary, the number 1/3 is 0.01010101 . . .. In the following, assume that x is an int and y is a short. For each x there exists some integer w (which may be different for different xs) such that abs(x/3 - q) < 10, where q = (((0x55555555>>w)*x)>>(32-w)).
- Afalse
- Btrue
8In the FDEMW five-stage pipeline we analyzed in class, if we want to stall memory how many pipeline registers should be given the "stall" signal?
- A4
- B0
- C5
- D3
9A CPU register file is a small storage device that
- AConsists of a collection of word size registers
- BHouses a critical variable for the duration of the execution of a program
- CRecords the results of periodic CPU diagnostics
- DIs automatically loaded when CPU instruction refers to a word of normal memory
10In the FDEMW five-stage pipeline we analyzed in class, if we want to stall decode how many pipeline registers should be given the “normal operation” signal?
- A3
- B0
- C4
- D5
- E2
- F1
11Using a base address [Eb] %edx= 0x1000, and index register [Ei] %ecx=0x02, compute the effective address for:
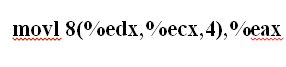
- A0x1064
- B0x1032
- C0x1016
- D0x1010
12A memory leak is caused by a
- AFailure to free allocated memory
- BFunction that allocates a large amount of memory from the heap
- CNone of these
- DBug in the memory allocator that fails to free memory
13In the two's complement number representation, a negative number with more leading ones is larger (i.e. less negative) than a negative number with fewer leading ones.
- Atrue
- Bfalse
14When shifting a two’s complement number to the left, an overflow can only occur if the number is negative, since positive numbers have a zero in the leftmost bit
- Afalse
- Btrue
15A program cannot accidentally use another program's memory space and "crash" a computer that uses (see the img)
1- virtual memory address
2- program relocation
3- separate instruction and data caches- A1 only
- B1 and 2
- C2
- D1,2,3
16In x86 assembly, the eax register can be used to hold integers but not addresses.
- Afalse
- Btrue
17A program written directly in machine language (binary) would run faster than the same program written in assembly code and then assembled.
- AFalse
- BTrue
18Initially byte i of memory is i + 0x20 (mod 256), %eax contains the number 3, and %ebx contains the number 5. What is in %ebx after running x86 movl (%eax), %ebx?
- Anone of the above
- B3
- C0x25
- D0x23
19Adding local variables is usually used to reduce what source of inefficiency?
- Aunnecessary memory references
- Bcondition checking overhead
- Cdata dependencies
- Dpoor branch prediction
20Asserting a word line and asserting (to "high" voltage) a bit line writes a 1 to a DRAM cell)
- AFalse
- BTrue
21Inline substitution (also called inlining) is usually used to reduce what source of inefficiency?
- Aprocedure call overhead
- Bpoor branch prediction
- Cpoor cache locality
- Dunnecessary memory references
22Using a base address [Eb] %edx=0x1000, and index register [Ei] %ecx=0x03, compute the effective address for:
- A0x1032
- B0x1014
- C0x1064
- D0x1016
23Jump in the following Y86-64 program. How many times does the addq instruction execute?
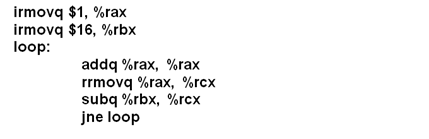
- A4
- B3
- C5
- D10
24Jump tables, such as are used for switch statements, require that the new PC be determined by a memory read. Suppose we added an assembly instruction memjump accepting a single memory address as its parameter, like memjump (%eax). In the five-stage example pipeline (F D E M W), for how many cycles will we need to bubble and/or stall stage F after executing a memjump?
- A3
- B4
- C5
- D6
25Let f32 be the number of distinct numbers that can be represented in 4-byte IEEE-style floating point and u32 be the number of distinct numbers that can be represented as unsigned 4-byte integers. Which of the following is true?
- Af32 < u32−1
- Bf32 > u32 +1
- Cf32 = u32
- Df32 = u32+1
26Let s8 be the number of distinct numbers that can be represented as signed (two's complement) 1-byte integers and u8 be the number of distinct numbers that can be represented as unsigned 1-byte integers. Which of the following is true?
- As8 = u8
- Bs8 > u8+1
- Cs8 = u8 - 1
- Ds8 < u8-1
27Assume a set-associative and a direct-mapped cache both have the same address size, same data capacity, and same number of index bits. This means
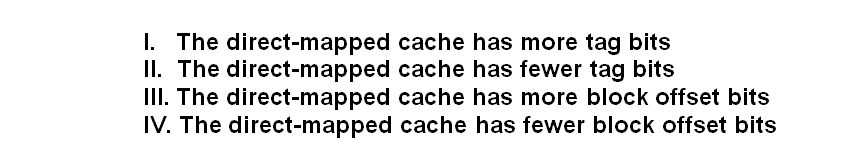
- AII and III
- B.
28Assume x is the most positive signed integer. What is x + 1?
- Anone of the above
- B+∞
- C-1
- D-x
29Logical address is calculated by: segment.base + eff_addr
- ASelector: eff_addr
- BSegment base + lin_addr
- CSelector: offset
- DSegment base + eff_addr
30Assuming the standard IEEE-style bias, what is the smallest number of bits a float point number could have and represent the number −29/4 exactly?
- A8
- B4
- C6
- D12
31Buses are typically designed to transfer fixed-sized chunks of bytes known as
- Awords
- Bframes
- Crecords
- Dpages
32Capacity misses are typically discussed in connection with?
- Afully-associative cache
- Bdirect-mapped caches
- Cset-associative caches
- Dall of the above
33Check the following (listed in alphabetical order) in order of importance when optimizing code that operates on very large arrays: B = Body of loop optimization (function inlining, efficient math), C = Cache locality, O = big-O of algorithm used
- ABCO
- BOBC
- CBOC
- DCOB
34Compare the size of int and int*
- Aeach one of the above depends on the compute
- Bint has fewer bits
- Cint* has fewer bits
- Dthey have the same number of bit
35Loop blocking is usually used to reduce what source of inefficiency?
- Apoor cache locality
- Bdata dependencies
- Cpoor branch prediction
- Dprocedure call overhead
36Loop unrolling is usually used to remove what source of inefficiency?
- Apoor cache locality
- Bdata dependencies
- Cpoor branch prediction
- Dprocedure call overhead
37Programs with good ______ ______, tend to access a referenced memory location multiple times in the near future.
- ATemporal locality
- BSpatial locality
- CRepetitive locality
- DAssociative locality
38Putting \#include "foo.h" in your C file is the equivalent of typing the contents of foo.h into your file
- Atrue
- Bfalse
39Consider the following code fragment
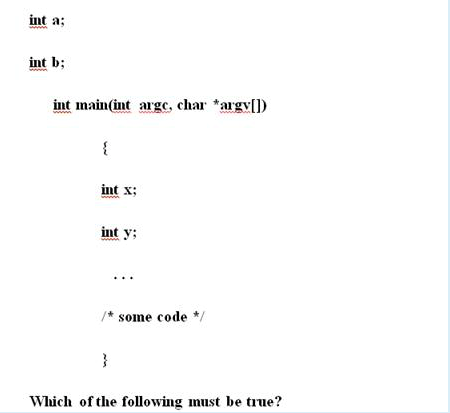
- AThe value of &y is closer to the value of &x than to the value &a
- BThe value of *y is closer to the value of *x than to the value *a
- CThe value of *a and *b are closer to each other than the values of *x and *y
- DThe value of &a and &b are closer to each other than the values of &x and &y
40Compared to dynamic RAM (SRAM), dynamic RAM (DRAM) is
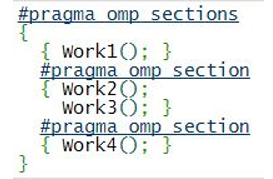
- Aa) DRAM is cheaper than SRAM
- Bb) DRAM is faster than SRAM
- Cc) DRAM is more likely to be used for main memory than for on-chip caches
- Dd) SRAM is more likely to be used for main memory than for on-chip cache
- Ea) DRAM uses more transistors per bit than SRAM
- Fb) DRAM uses a capacitor to store a value
- Gc) Typically a computer has more DRAM than SRA
41Compiling C into x86 assembly comprises translating each C statement into a single assembly instruction.
- AFalse
- BTrue
42Conflict misses are typically discussed in connection with?
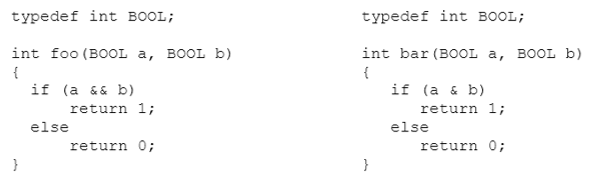
- Adirect-mapped caches
- Bset-associative caches
- Cfully-associative caches
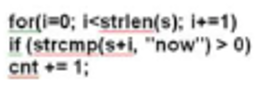
- Dall of the above
43Rank the following in order of significance when writing code that deals with large arrays:
- Algorithmic efficiency (i.e., big-O),
- Computational efficiency (e.g., loop unrolling, inlining, etc),
- L cache Locality.
- AACL
- BALC
- CLCA
- DCAL
44CPE (cycles per element, also called cycles per execution or cycles per instruction in other sources). If we have code with 20 CPE and run it on a problem where my algorithm executes on 100 elements; I should expect the runtime to be
- A50-220 cycles
- B0-50 cycles
- C220-1100 cycles
- D1100-2200 cycles
45Reassociation of operators is usually used to reduce what source of inefficiency?
- Adata dependencies
- Bcondition checking overhead
- Cpoor branch prediction
- Dpoor cache locality
46Register %edx is one of the "callee-save" registers. This means that if procedure baz calls procedure xyxxy
- Abaz may assume xyxxy did not change %edx
- Bxyxxy may communicate with baz through register %edx
- Cbaz must assume xyxxy could have changed %edx
- Dbaz may communicate with xyxxy through register %edx
47Register %esi is one of the "caller-save" registers. This means that if procedure baz calls procedure xyxxy
- Abaz must assume xyxxy could have changed %esi
- Bxyxxy may communicate with baz through register %esi
- Cbaz may assume xyxxy did not change %esi
- Dbaz may communicate with xyxxy through register %esi
48Dirty bits are associated with (pick the best answer)
- Awrite-back caches
- Bwrite-through caches
- Cset-associative caches
- Ddirect-mapped caches
49Edsger Dijkstra wrote "Go To Statement Considered Harmful" in 1968 in which he argued (translated into current language) that code that uses goto becomes needlessly hard to read and maintain compared to only using if and while. In assembly, we use the goto-like jump instructions extensively; the main reason for this is?
- Agoto is only bad when mixed with higher-level constructs
- BDijkstra was wrong
- Cno one is reading assembly anyway
- Dthere is no other alternative in assembly
50Every procedure in an x86 assembly program must be declared using .globl
- AFalse
- BTrue
51Which of the following is a good reason (are good reasons) to equip the CPU with small amounts of fast memory?
I. To make the design of the compiler simpler
II. To make some CPU instructions smaller
III. To make some CPU instructions faster- AIII only
- BII and III only
- CI, II, and III
- DII only
52Given 6-bit numbers where 010001 + 001010 = 010110, which of the following describes the number representation used?
- Afloating-point with 2 exponent bits
- Bfloating-point with 3 exponent bits
- Cinteger
- Dfloating-point with 4 exponent bits
53Given 6-bit numbers where 010101 + 000001 = 010110, which of the following describes the number representation used?
- Ainteger
- Bfloating-point with 3 exponent bits
- Cfloating-point with 1 exponent bits
- Dfloating-point with 2 exponent bits
54Good software design includes writing procedures for code you might otherwise repeat in-line. Pulling code into procedures can help some branch predictors; how else can it improve your program’s performance and/or your compiler’s ability to optimize your code?
- Amore opportunities for loop unrolling
- Bless chance of compiler having to worry about aliasing and side effects
- Cmore opportunities for pipeline-level parallelism
- Dbetter instruction cache hit rate
55Return from function issues a bubble in pipeline.
- Atrue
- Bfalse
56Good software design includes writing procedures for code you might otherwise repeat in-line. Pulling code into procedures involves call/return overhead; how else can it hurt your program's performance and/or your compiler's ability to optimize your code?
- Amore chance of compiler having to worry about aliasing and side effects
- Bfewer opportunities for pipeline-level parallelism
- Cworse instruction cache hit rate
- Dfewer opportunities for loop unrolling
57SRAM is "static" in the sense that if the power is turned off, SRAM will continue to store data (e.g. as in flash memory in MP3 players or USB thumb drives).
- Afalse
- Btrue
58Suppose addresses A and B have different tags but the same index (for those caches that have tags and indexes, that is). Assume the cache is empty prior to the accesses listed in the questions. In the access pattern "read A, then read B, then read A, then read B" the second read of A will be a miss for?
- Aa direct-mapped cache
- Ba set-associative cache
- Ca fully-associative cache
- Dall of the above
59How does knowing you have a pipelined processor change the code you write?
- Ait suggests optimizations like multiple accumulators
- Bit suggests optimizations like adding local variables
- Cit suggests optimizations like loop unrolling
- Dit suggests optimizations like loop reordering
60Suppose addresses A and B have different tags but the same index (for those caches that have tags and indexes, that is). Assume the cache is empty prior to the accesses listed in the questions. In the access pattern "read A, then read B" the read of B will be a miss for
- Aall of the above
- Ba fully-associative cache
- Ca direct-mapped cache
- Da set-associative cache
61How is "-1" (decimal) represented in an 8-bit 2's complement binary format?
- A11111111
- B.
62Suppose page table entries are 8 bytes long and virtual addresses are 32 bytes long. If each page table is to fit on a single page, what is the smallest pages can be if we have a 2-level page table hierarchy?
- Abigger than any of the above options
- B2 KB
- C512 B
- Dsmaller than any of the above options
63How is 46 (decimal) represented in an 8-bit 2's complement binary format?
- A00101100
- B00101110
- C00011110
- D01000110
64How is -10 (decimal) represented in an 8-bit 2's complement binary format?
- A11110110
- B10001010
- C11110101
- D11111010
65Which of the following move operations is the following instruction an example of movl (%edx), (%eax)?
- Aerror, can’t move memory to memory
- Bmemory to immediate
- Cregister to memory
- Dmemory to register
66In the access pattern “write A, then write B, then write A”, to minimize
writes to the higher-level cache we should pick which of the following?- Aa write-through fully-associative cache
- Ba write-back fully-associative cache
- Ca write-through direct-mapped cache
- Da write-back direct-mapped cache
- Etwo or more of the above are equivalently the best option
67How many hex digits are needed to represent the decimal number 67?
- A2
- B6
- C4
- D7
68How many ints fit inside x if x is declared as int *x = malloc(8); ? Word size is 4.
- A2
- B1
- C8
- D0
69Which of the following move operations is the following instruction an example of movl (%edx), %eax?
- Aerror, can’t move memory to memory
- Bmemory to register
- Cregister to memory
- Dmemory to immediate
70How many rules do Unix linkers use for dealing with multiply defined symbol
- A3
- B4
- C5
- D2
71Suppose an array of char (8-bit values) {0x12, 0x34, 0x56, 0x78} is stored at address 0x24 of a little-endian computer. What byte is stored at address 0x26?
- A0x56
- B0x00
- C0x65
- DA known value not listed here
72If a computer has 8GB memory, a single 1MB cache, and 4KB of registers, the total amount of data it can store is?
- Amore than 8GB but less than 8GB + 1MB
- Bmore than 8GB + 1MB but less than 8GB + 1MB + 1KB
- Cmore than 8GB + 1MB + 4KB
- D8GB + 1MB + 4KB
73Suppose the 32-bit value 0x12345678 is stored at address 0x24 of a big-endian computer. What byte is stored at address 0x23?
- A0x65
- B0x34
- C0x43
- DA known value not listed here
- EAn unknown value because the number does not overlap address
0x25
74When the following code fragment is executed on a computer with 32-bit integers and a fully-associative cache with 16-byte cache lines, how many bytes of the array A[] will be fetched into the cache from main memory
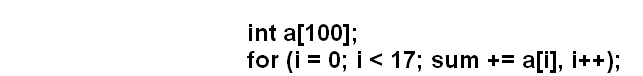
- AAt most 96
- BExactly 17
- CExactly 32
- DAt most 80
75If a wire carries a logical value of 0, its voltage level will be 0 Volts.
- AFalse
- BTrue
76If we fail to find data in a cache because we have never accessed the data before, we call that a
- Acold miss
- Bcapacity miss
- Cconflict miss
- Dforced miss
77If we fail to find data in a cache because we've read too much data since we last accessed that same data, we call that a
- Acapacity miss
- Bcold miss
- Cconflict miss
- Dforced miss
78Suppose the 32-bit value 0x12345678 is stored at address 0x24 of a big-endian computer. What byte is stored at address 0x25?
- A0x56
- BA known value not listed here
- C0x65
- D0x43
- EAn unknown value because the number does not overlap address
0x25 - FF 0x34
79If we were running a non-pipelined processor (like SEQ) with a real memory system, which of the following optimization strategies would no longer provide a speed benefit?
- Ausing multiple accumulators
- Badding local variables
- Cfunction call inlining
- Dnone of the above would provide a speed benefit
80The .data section of an x86 assembly program is used to specify the parameters for each procedure.
- Afalse
- Btrue
81In C, a pointer variable is used for storing an address
- ATrue
- BFalse
82If x is the most negative signed integer, what is -x?
- Athe most negative signed number
- Bone
- Cthe most positive signed number
- Dnegative one
83In a DRAM, all cells have to be periodically refreshed, not just the ones that have been read.
- ATrue
- BFalse
84In a program with good ____________, if a memory location is referenced once, then the program is likely to access nearby memory locations in the near future
- ASpatial locality
- BTemporal locality
- CRepetitive locality
- DAssociative locality
85The ASCII code for the character 'B' is 0x42. What is the ASCII hex code for the character 'D'?
- A0x4B
- B0x5A
- C0x48
- D0x44
86If we were running a non-pipelined processor (like SEQ) with a real memory system, which of the following optimization strategies would not longer provide a speed benefit?
- Anone of the above would provide a speed benefit
- Badding local variables
- Cusing multiple accumulators
- Dfunction call inlining
87In C, local variables allocated inside functions are allocated:
- AOn the stack
- BIn static storage
- CIn virtual memory
- DIn the heap
88In C, using default floating point settings, a special value of "infinity" is computed when
- AA floating-point computation results in an overflow
- BProgram execution is halted
- CAn erroneous value is computed and execution continues
- DAn exception is raised
89The ASCII code for the character 'B' is 0x42. What is the ASCII hex code for the character ‘E’?
- A0x45
- B0x48
- C0x56
90In given two C modules which rule will Unix linker use to resolve multiple symbol definition?
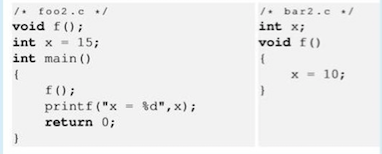
- AGiven a strong symbol and multiple weak symbols, choose the strong symbol.
- BGiven multiple weak symbols, chose any of the weak symbols
- CMultiple strong symbols are not allowed.
- DNone of these
91The assembly instruction int x used to make system calls only accepts a 1-byte (256-value) argument x, but Linux uses it to support over 300 system calls. How does it do that?
- ASRAM would lose its data, DRAM would keep its data
- BSRAM would keep its data, DRAM would keep its data
- CSRAM would keep its data, DRAM would lose its data
- DSRAM would lose its data, DRAM would lose its data
92The contents of how many program registers are modified by an assembly push operation?
- A1
- B2
- C3 or more
- Dit depends on that argument of the push
93The difference between the SAR (arithmetic shift right) and SHR (logical shift right) operations is that SAR puts a one into the leftmost bit after a shift and SHR puts a zero.
- Afalse
- Btrue
94The EBP is a callee-saved register.
- Atrue
- Bfalse
95The EFLAGS register contains the zero flag and the sign flag?
- Atrue
- Bfalse
96What is the value of the following C expression? x=0x1234 and y=0x3 ((x >> y) << y)
- A0x1230
- B0x1234
- C0x0246
- D0x1200
97The hardware is aware of the program stack
- Atrue
- Bfalse
98The instruction addq %rax, %rbx changes what?
- AThe contents of the rbx register
- BThe contents of memory at an address found in the rax register
- CThe contents of memory at an address found in the rbx register
- DThe contents of the rax register
99What is the value of the following C expression? x=0x00 and y=0xA5 x && ~y
- A0xFF50
- B0x0000
- C0x0001
- D0x11A5
100The instruction cmp eax,ebx (or cmp %ebx,%eax in AT&T syntax) computes the value of EAX - EBX.
- Atrue
- Bfalse
101_______ - program transformation that reduces the number of iterations for a loop by increasing the number of elements computed on each iteration
- ALoop unrolling
- BMemory aliasing
- CSide effect
- DCode motion
102The valid bit is associated with
- Afully-associative caches
- Bwrite-through caches
- Cset-associative caches
- Ddirect-mapped caches
103It is possible to explicitly specify the number of threads to be created in the team, using the _____ attribute:
- Apragma omp
- Bparallel
- Cprivate
- DNum_threads
104CPU optimized for throughput
- ATrue
- BFalse
105The working set of a program is formed by
- AThe pages that the program is actively using
- BThe libraries required by the program
- CThe memory of the program that is currently in physical memory
- DAll the files the program needs to execute
106This problem occurs when a larger type is converted into a smaller type or with the signed-unsigned operations?
- Atruncation
- Boverflow
107Using multiple accumulators is usually used to reduce what source of inefficiency?
- Aunnecessary memory references
- Bcondition checking overhead
- Cdata dependencies
- Dpoor branch prediction
108169. In C a single statement that performs the equivalent of y=x*100; but without using the multiply operator (*);
- Ay = (x>>6)+(x<<5)+(x<<2)
- By = (x<<6)+(x<<3)+(x>>2)
- Cy = (x<<5)+(x<<5)+(x<<7)
- Dy = (x<<6)+(x<<5)+(x<<2)
109We can encode the C command a ? b : c, where all three variables are of type int,
- A((-!!a) & b) | ((-!a) & c)
- B((!!a) & b) | ((!a) & c)
- CAny of the above
- D(a & b) | ((!a) & c)
110We say that pipelining generally increases latency. That statement means (select all that are part of the definition of "increases latency")
- Aeach instruction takes more time to complete
- Beach instruction takes less time to complete
- Centire programs take more time to complete
- Dentire programs take less time to complete
111Two computers A and B with a cache in the CPU chip differ only in that A has an L2 cache and B does not. Which of the following are possible?
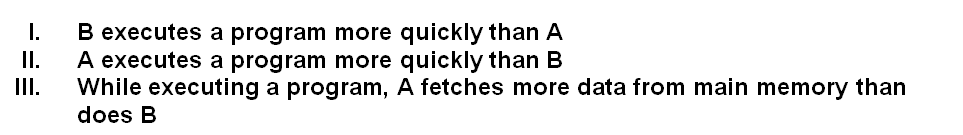
- A1 & 2 only
- B2 & 3 only
- C1 only
- D2
112At which of the following times is a stack frame created?
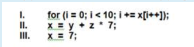
- AII and III only
- BII only
- CIII only
- DI and II only
113The bitwise and operation (& in C) can be used to flip the bits of a word
- Atrue
- Bfalse
114Linking can be performed at
- Arun time
- Bcompile time
- Call of the above
- Dload time
115Parallel processing mechanisms to achieve parallelism in uniprocessor system are:
- AAll of the above
- BMultiple function units
- CParallelism and pipelining within CPU
- DMultiprogramming and time sharing
116This is an example of?
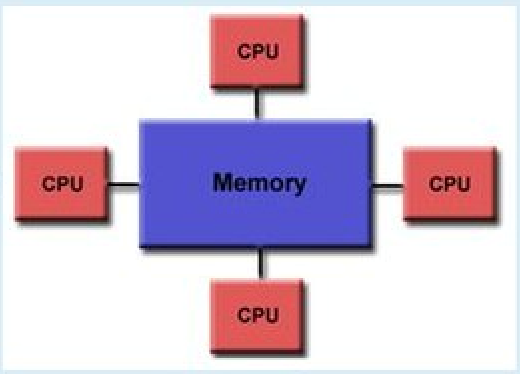
- AHybrid system
- Bshared memory UMA
- CDistributed memory architecture
- DShared memory NUMA
117This is an example of?
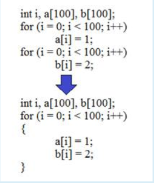
- ANone
- BLoop unrolling
- CLoop fusion
- DLoop fission
118This is an example of?
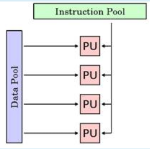
- AMIMD
- BMISD
- CSIMD
- DSISD
119This is an example of?
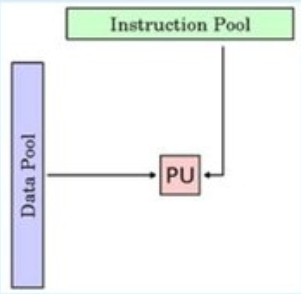
- AMIMD
- BMISD
- CSIMD
- DSISD
120This is an example of?
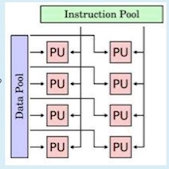
- AMIMD
- BMISD
- CSIMD
- DSISD
121This is an example of?
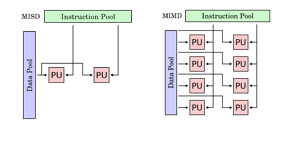
- AMIMD
- BMISD
- CSIMD
- DSISD
122The _______ directive causes threads encountering the barrier to wait until all the other threads in the same team have encountered the barrier.
- Asingle
- Bbarrier
- Cnowait
- Dprivate
123How is 148 (decimal) represented in a 16-bit 2’s complement binary format?
- A0000 0000 1101 0111
- B0000 0000 0010 1001
- C1111 1111 0010 1000
- D1111 1111 0110 1100
124In a Compare the runtime of y = x * 5 and y = (x<<2) + x, measured by the time it takes for the resulting value of y to be available somewhere in the pipeline.
- Ay = x * 5 is faster
- By = (x<<2) + 5 is faster
- Cnot given
- Dthey take the same number of cycles
125What is the difference between 15 and $15?
- A15 is an address, $15 is a value
- B15 is a value, $15 is an address
- C15 is legal in assembly, $15 is not
- D$15 is legal in assembly, 15 is not
126What is the result of the following assembly code instruction?
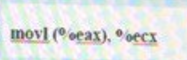
- AFetch the data from register %ecx and store in register %eax
- BFetch the data from the register %ecx and store in the memory address indicated by (%eax)
- CFetch the data from the register %eax and store in register %ecx
- DFetch the data from the memory address indicated by (%eax) and store in the register %ecx
127What is the value of the following C expression? x=0xA0 and y=0x0F ~x||~y
- A0х0001
- B0х6000
- C0xFF50
- D0xFFFF
128What value ends up in EAX afer the following code is executed?
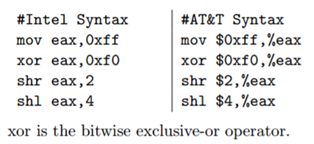
- A48 (decimal) or 00110000 (binary) or 0x30 (hex)
- B50 (decimal) or 00110010 (binary) or 0x32 (hex)
- C46 (decimal) or 00101110 (binary) or 0x2E (hex)
- D52 (decimal) or 00110100 (binary) or 0x34 (hex)
129When shifting a two's complement number to the left, an overflow can only occur if the number is negative, since positive numbers have a zero in the leftmost bit.
- AVerdadero
- BFalso
130Which of the five phases determines how many bytes long an instruction is?
- AFetch
- BDecode
- CWriteback
- DExecute
131Which of the five phases determines what the next PC is?
- AFetch
- BMemory
- CExecute
- DDecode
132Which of the five phases determines the destination register for instructions that write to registers?
- ADecode
- BWriteback
- CFetch
- DExecute
133Which of the following computations may be performed by exactly one CPU instruction? (img)
a = 5;
a = b + c * 5;
for (i = 0; i < 10; i += a[i++]);- AI, II, and III
- BII only
- CI and II only
- DI only
134Which of the following is true?
- AA direct-mapped cache is a set-associative cache with set size 1
- BA direct-mapped cache is a fully-associative cache with only one set
- CA direct-mapped cache is a fully-associative cache with set size 1
- DA direct-mapped cache is a set-associative cache with only one set
135Which of the following manages the transfer of data between the cache and main memory
- AOperating system
- BCompiler
- CHardware
- DRegistry
136Which of the following manages the transfer of data between the CPU registers and the cache
- AOperating system
- BCompiler
- CHardware
- DRegistry
137Which of the following registers is the lower order 16 bit register of register %ecx?
- A%cx
- B%cl
- C%ch
- D%cy
138Which of the following statements about alignment within C struct's is true?
- AA constant offset associated with the member is added to the address
- BThe struct consists of an array of pointers to the elements of the struct
- CThe element name is looked up in a symbol table
- DA linear search is made from the base address of the struct
139Which of the following statements about floating-point numbers in C is true?
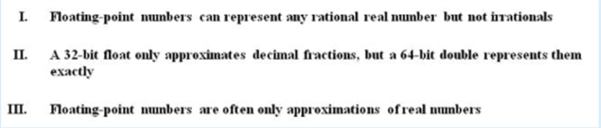
- AII only
- BIII only
- CI
- DI and II
140Which one of the following IA32 registers is typically used for stack management?
- A%esp
- B%eax
- C%ebx
- D%edi
141Which one of the following optimizations does not provide any speed benefit for a non-pipelined processor, such as SEQ?
- AStoring reused computed values in variables instead of recomputing them
- BInvocation inlining
- CUsing more efficient algorithms
- DReassociation
142Which of the following levels of a typical memory hierarchy transfers data in chunks of smallest size?
- AMain memory < ---> disk
- BCache < ---> main memory
- CThey all transfer one byte at a time
- DCPU registers < ---> cache
143In C, a pointer variable is used for storing an address
- AVerdadero
- BFalso
144If we cut power for one millisecond, which of the following is true?
- ASRAM would keep its data, DRAM would lose its data
- BSRAM would lose its data, DRAM would keep its data
- CSRAM would lose its data, DRAM would lose its data
- DSRAM would keep its data, DRAM would keep its data
145If we cut power for one minute, which of the following is true?
- ASRAM would lose its data, DRAM would lose its data
- BSRAM would lose its data, DRAM would keep its data
- CSRAM would keep its data, DRAM would keep its data
- DSRAM would keep its data, DRAM would lose its data
146Select the most correct statement from the following as applied over the last two decades:
- AProcessors get faster but memory does not
- BProcessors and memory both get faster, but memory gets faster faster that processors do
- CProcessors and memory both get faster, but processors get faster than memory does
- DMemory gets faster but processor does not
147Which one of the following optimizations does not provide any speed benefit for a
non-pipelined processor, such as SEQ?- AUsing more efficient algorithms
- BInvocation inlining
- CReassociation
- DStoring reused, computed values in variables instead of recomputing them
148Consider the following code. Assume the compiler is performing no optimization. Which of the following strategies would improve the speed of this code the most in the case where it returns true?
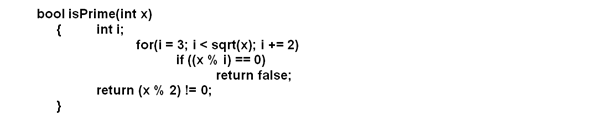
- AUnroll the loop
- BPull the (x % i)==0 into a function isDivisibleBy
- CDeclare int sx = (int)sqrt(x) and change i < sqrt(x) to i < sx
- DMove the check for (x % 2) != 0 to before the loop
149Consider the following code. This code would most likely benefit from which of the following optimization strategies
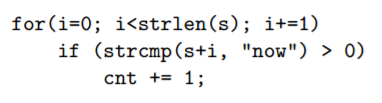
- AUsing multiple accumulators
- BImproving cache locality
- CLoop unrolling
- DAdding local variables
150What does the following C code print?
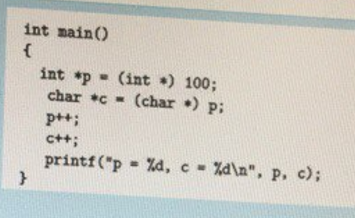
- AP = 103, c = 101
- BP = 104, c = 101
- CP = 105, c = 103
- DP = 104, c = 102
151The bitwise and operation (& in C) can be used to flip the bits of a word
- AVerdadero
- BFalso
152The bitwise xor operation (^ in C) can be used to flip the bits of a word
- AVerdadero
- BFalso
153Consider a direct-mapped cache with 256 sets and 16 byte blocks. In this cache the address 0x12345 maps to the same set as which of the following addresses?
- A0x02345
- B0x22244
- C0x12040
- D0x12354
154In C, on a 34-bit x86 machine, the expression (1 << 31) results in a negative integer
- AVerdadero
- BFalso
155Consider the following code. Which of the following changes would make the largest positive impact on its cache locality?
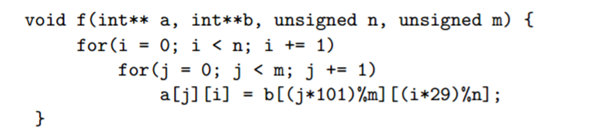
- APut the for-i loop inside of the for-j loop instead of the other way around
- BStore the result of (i*101)%n outside the inner loop
- CBlock the accesses by nesting three or four for loops instead of just two
- DChange int** to int*
156Consider the following code. Assume the compiler is performing no optimizations and that isPrime is the exact code presented in another question on this exam. Which of the following strategies would improve the speed of this code the most?
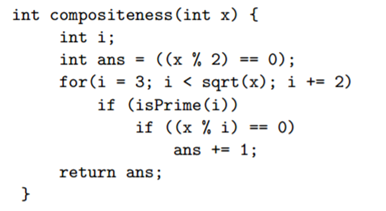
- AInline the isPrime call
- BAdd a second ans accumulator
- CSwap the order of the if statements
- DChange the nested if statements to a single if with a &&
157Consider the following two versions of a C function: (Assume len is larger than 10)
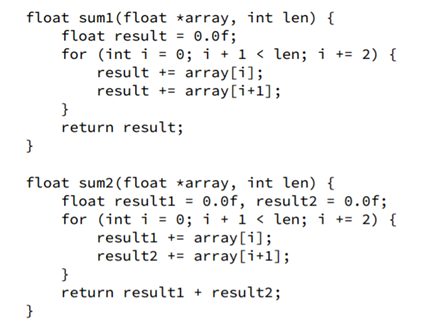
- Asum1
- BNone of them
- Csum2
- DBoth of them
158Which of the following is necessary true regarding the following code fragment?
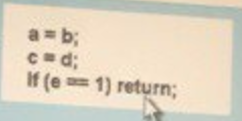
- AIt exhibits locality of reference but only when a == b
- BIt exhibits locality of reference because the variables are allocated near each other
- CIt exhibit no locality of reference
- DIt exhibits locality of reference no matter where the variables are allocated
159A & B is the bitwise version of A && B; A | B is the bitwise version of A || B; which of the following is the bitwise version of A == B?
- A~(a = b)
- Ba = b
- C~ (a ^ b)
- Da ^ b
160The unary & operator returns (in C language)
- AThe logical “and” of two integer operands
- BThe logical “or” of two integer operands
- CThe value of a data object
- DThe address of a data object
161In C a single statement that performs the equivalent of y = x *100, but without using the multiply operator (*)
- Ay = (x<<6) + (x<<5) + (x<<2)
- By = (x>>6) + (x<<5) + (x<<2)
- Cy = (x<<6) + (x<<3) + (x>>2)
- Dy = (x<<5) + (x<<5) + (x<<7)
162Adding local variable is usually used to reduce what source inefficiency?
- ACondition checking overhead
- BPoor branch prediction
- CUnnecessary memory references
- DData dependencies
163If, in C, an array is declared by “int a[10];”, then accessing a[11] during execution will generate an error message.
- AVerdadero
- BFalso
164In C, if x is an integer variable, the expression “x << 3” computes x * 8 but does not change the value of x.
- AVerdadero
- BFalso
165Which of the following code snippets is fastest? Assume n is very large (more than ten thousand).
- Afor(i=0;i<n;i+=1) for(j=0;j<n;j+=1) a[i][j] = b[j][i];
- Bfor(j=0;j<n;j+=1) for(i=0;i<n;i+=1) a[i][j] = b[j][i];
- C
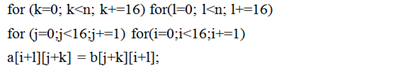
- Dtwo or more of the above are equivalently the fastest
166Which of the following code snippets is fastest? Assume n is very large (more than ten thousand).
- Aa) for(k=0; k<n; k+=16) for(l=0; l<n; l+=16)
for(j=0;j<16;j+=1) for(i=0;i<16;i+=1)
a[i+l][j+k] = b[i+l][j+k]; - Bfor(i=0;i<n;i+=1) for(j=0;j<n;j+=1) a[i][j] = b[i][j];
- Cfor(j=0;j<n;j+=1) for(i=0;i<n;i+=1) a[i][j] = b[i][j];
- Dtwo or more of the above are equivalently the fastest
- Aa) for(k=0; k<n; k+=16) for(l=0; l<n; l+=16)
167In binary, the number 1/3 is 0.01010101 . . .. In the following, assume that x is an int and y is a short. (short)((0x5555 * (int)y)>>16) and y/3 could differ because of overflow
- AVerdadero
- BFalso
168 How is 148 (decimal) represented in a 16-bit 2’s complement binary format?
- A0000 0000 1101 0111
- B0000 0000 0010 1001
- C1111 1111 0010 1000
- D1111 1111 0110 1100
169Which of the following code snippets is fastest? Assume n is very large (more than ten thousand).
- Afor(j=0;j...
- Bfor(i=0;i...
- Ctwo or more of the above are equivalently the fastest
- Dfor(k=0;k<n;k+=16) for(l=0;l<n;l+=16)...
170In a Compare the runtime of y = x * 5 and y = (x<<2) + x, measured by the time it takes for the resulting value of y to be available somewhere in the pipeline.
- Ay = x * 5 is faster
- Bthey take the same number of cycles
- Cnot given
- Dy = (x<<2) + 5 is faster
171The program counter contains:
- AThe address of the CPU instruction that is about to be executed
- BThe number of programs currently running
- CThe number of CPU instructions a program has executed so far
- DThe number of processes currently running
172A memory leak is caused by a:
- ABug in the memory allocator that fails to free memory
- BFailure to free allocated memory
- CNone of these
- DFunction that allocates a large amount of memory from the heap
173Registers and cache memory are the same thing
- AFalse
- BTrue
174In a computer in which both addresses and integers are 32 bits wide, how many bytes of memory will the compiler allocate for the following code fragment?
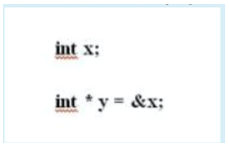
- A32
- B8
- C16
- D4
175In C, local variables allocated inside functions are allocated:
- AOn the stack
- BIn the heap
- CIn virtual memory
- DIn static storage
176What is the value of the following C expression? x=0xA0 and y=0x0F ~x || ~y
- A0x0000
- B0xFF50
- C0xFFFF
- D0x0001
177What is an example of?
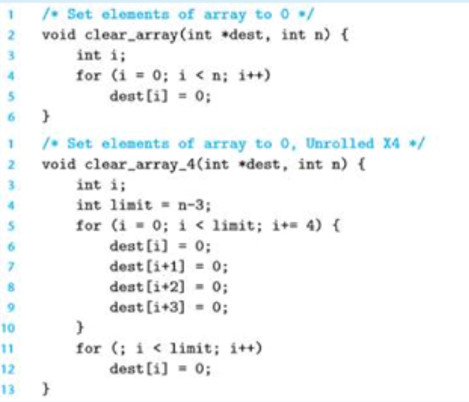
- ALoop unrolling
- BLoop fission
- Cnone
- DLoop fusion
178How is 215 (decimal) represented in a 16-bit 2's complement binary format?
- A1111 1111 0010 1001
- B0000 0000 1101 0111
- C0000 0000 0010 1001
- D1111 1111 0010 1000
179This code indicates that Work2 and Work3 must be run in _______ :
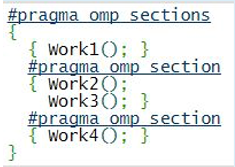
- Anone
- Bparallel
- Csequence
- Dboth
180____ involve identifying a computation that is performed multiple times (e.g., within a loop), but such that the result of the computation will not change.
- ACode motion
- BSide effect
- CLoop unrolling
- DMemory aliasing
181In C, for the expression (x | THE_MASK), where THE_MASK has at least one bit that is not zero, the result will be zero if all the bits of x are zero.
- ATrue
- BFalse
182What is the value of the following C expression? x = 0x128 and y = 0x2 ~x << y (in hex)
- A0x000004A0
- B0x000FFB5C
- C0xFFFFFB5C
- D0x00FF04A0
183In C, using default floating point settings, a special value of "infinity" is computed when:
- AA floating-point computation results in an overflow
- BProgram execution is halted
- CAn exception is raised
- DAn erroneous value is computed and execution continues
184GPU optimized for latency.
- Atrue
- Bfalse
185If you don’t explicitly specify the number of threads (OpenMP) how many thread will be executed?
- A1
- BDepends on the number of cores on computer
- C2
- D4
186CPU optimized for latency
- Atrue
- Bfalse
187Program take as input a collection of relocatable object files and command-line arguments and generate as output a fully linked executable object file that can be loaded and run:
- AStatic linker
- BDynamic linker
- CBoth
- Dnone
188If we find the data we want in a cache, we call that a
- ACache find
- BCache hit
- CCache miss
- DCache success
189The___construct forms a region that contains one or more structured blocks. Each block of a_____ directive executed once by one of the threads (any one) in the team?
- Aparallel
- Bmaster
- Csection
- Dschedule
190Pick a value for A and for B which will cause the two procedures below to return different results.
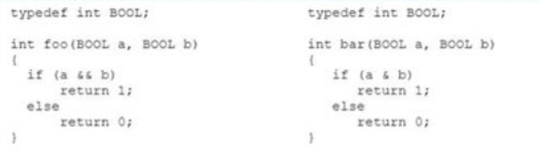
- Aa=7; b=1;
- Ba=1; b=2;
- Ca=1; b=5;
- Da=1; b=1;
191Pick a value for A and for B which will cause the two procedures below to return the same results.
- AОДИНАКОВЫЕ ВОЗВРАЩАЮТ: (7,1) (1,5) (1,1)
- Bнет других вариантов
192A is the 4-bit value 0011 and B is the 4-bit value 0110. What is A^B?
- A0011
- B1110
- C0111
- D0101
193Consider the following code. This code would most likely benefit from which of the following optimization strategies.
- Aimproving locality
- Bloop unrolling
- Cusing multiple
- Dadding local variables
194Conflict misses are typically discussed in connection with?
- Aall of the above
- Bfully-associative caches
- Cset-associative caches
- Ddirect-mapped caches
195What is -5 as a six bit two’s complement number? Answer in binary
- A101111
- B111011
- C000001
- D011011
196By default, OpenMp _____ assigns loop iterations to threads. When the parallel for block is entered, it assigns each thread the set of loop iterations it is to execute?
- Astatic
- Bruntime
- Cdynamic
- Dauto
197In general, which of the following is slowest?
- Amoving from one register to another
- Bdoing division
- Caccessing memory
- Dcomparing two numbers to decide where to jump
198How is 28 (decimal) represented in an 8-bit 2’s complement binary format?
- A0001 1100
- B1110 0100
- C1100 1011
- D1110 0011
199The ASCII code for the character ‘b’ is 98. How can the character ‘b’ be represented in binary using ASCII codes?
- A1011 1111
- B1010 1111
- C0110 0010
- D1000 0001
200This code indicates that any of the tasks Work1, Work2 + Work3 and Work4 may run in _____________:
- Aparallel
- Bsequence
- Cboth
- Dnone
Información
- Descripción
- SDP10 Test sobre SDP10 Final - Part I, creado por Csse 1502 el 12/05/2018.
- Autor
- Csse 1502
- Idioma
- English
- Visitas
- 400
- Etiquetas
- Valoración
- Aún sin valoraciones Valora este test