
Test
Review Machine Learning
Crea una cuenta gratis para terminar este test
Guarda tu progreso y consulta tu resultado final.
¿Ya tienes cuenta? Inicia sesión
Preguntas del test (19)
1What is the first effect of standardizing?
- AVariable units are removed
- BVariable variance is reduced
- CRedundancy is eliminated
- DModel complexity is reduced
2What is the effect of transforming variables by using Logarithms?
- ATo convert a non-linear function into a linear one
- BTo reduce assymetry in some variables
- CTo reduce variable range
- DAll the others
3Which one from the following statement is CORRECT regarding Segmentation?
- ADimension reduction analysis is mandatory before Segmentation
- BVariable standardization is mandatory
- CClustering variables cannot be used to calculate profiles
- DAll the others are INCORRECT
4Which of the following is NOT a valid recommendation on Segmentation Analysis?
- ASegments smaller than 5% of size must be merged
- BSelect profiling variables vs. clustering ones
- CIf analyst cannot set up labels, segmentation is not valid
- DDifferent variable units should be removed
5Which sentence, from the following, is TRUE regarding Hierarchical Segmentation methods?
- AThey do not require variable standardization
- BIt is valid for large datasets
- CDendrogram is a typical chart from these methods
- DK-means is included in this family
6According to the following image, which of the following is CORRECT?
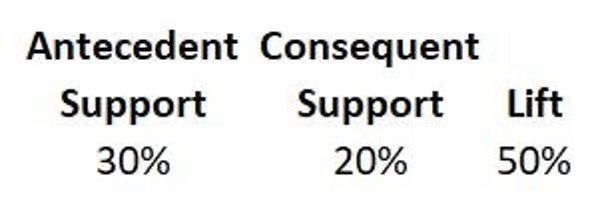
- AConfidence is 40%
- BConfidence Ratio is 40%
- CRule Support is below 10%
- DConsequent purchases increase if Antecedents are present
7Which of the following sentences is CORRECT regarding Lift and Confidence Ratio?
- ALift is normally used to find negative rules
- BConfidence Ratio is normally used to find rules for non-frequent products
- CLift is normally used to find rules for non-frequent products
- DConfidence Ratio is normally used to find negative rules
8If Confidence Difference lower bound is set to 70, which of the following is CORRECT?
- ANegative rules would require a Posterior Confidence <= 30
- BRules will be generated for all frequent products
- CYou can calculate Lift with data given
- DNegative rules can not be extracted
9If one rule's Lift = 0.9, which one of the following is CORRECT?
- AConsequent support is greater than Prior Confidence
- BConsequent was not bought by all customers
- CConsequent appears more frequently with antecedent than without them
- DConfidence Ratio is greater than 1
10What is CORRECT regarding sample size for Linear Regression?
- AWe need at least 20 observations
- BWe need at least 15 to 20 more rows/records than explanatories
- CWe need at least n*k observations (being k number of explanatories)
- DWe need at least 50-100 observations, less is not reliable
11Which of these statements regarding Linear Regression is CORRECT?
- ADependent variable cannot be categorical
- BIn a stochastic model there is NOT random perturbation
- CRandom perturbation (u) is the estimation of model error (e)
- DVariables should be standardized
12R squared measure in Linear Regression ...
- AReflects the individual significance of variables
- Bis valid to compare models with different # of variables
- CIt is related to variance of dependent variable
- Dneeds to be high according to one statistical assumption
13According to the following image from a Linear Regression, which of the following is CORRECT (with 95% CL)?
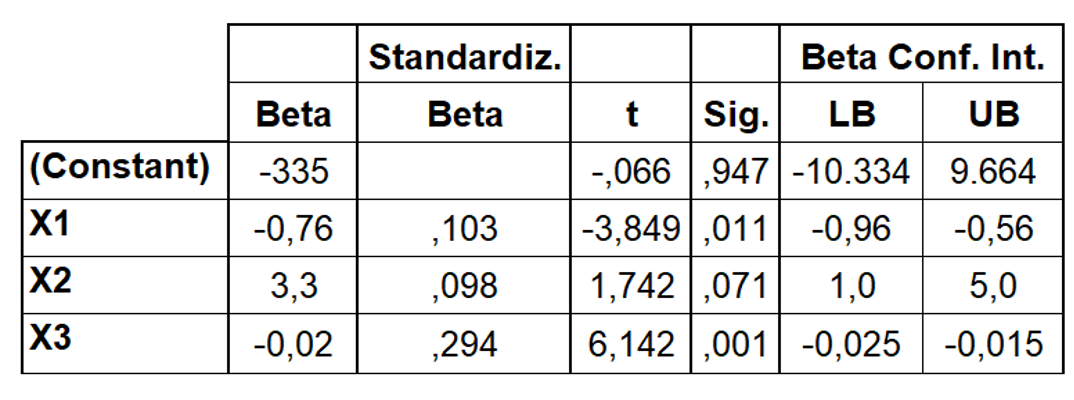
- AAll variables are relevant
- BX1 variable is significant at 99% Confidence Level
- CX2 is the most relevant variable in the equation
- DThis output is NOT valid
14If both dependent and independent variables are in Logs, and Beta of x1 = 0.5, which of the following is CORRECT?
- A1 unit increase in X1 produces 0.5 units increase in y
- B1 % increase in X1 produces 50% increase in Y
- C1 % increase in X1 produces 0,5 units increase in Y
- D1 % increase in X1 produces 0,5% increase in Y
15Which of these statements regarding assumptions in Linear Regression is CORRECT?
- AHigh correlation of explanatories is called Auto-correlation
- BAuto-correlation is more frequent in time series
- CDifferent residual variances is called Homocedasticity
- DNormality in model error variable cannot be checked
16Which one of the following is NOT be a valid example for Classification Analysis
- ADetecting spam from non-spam emails
- BPredict whether a music album will be a success or not
- CForecast which players might score a penalty and which not
- DIdentify groups of individuals depending on their purchases
17Which of the following is INCORRECT in Logit Regression?
- ADependent variable is a categorical one
- BRange of output values is (0,1)
- CEvery dot in the ROC Curve is a model
- DMost important validation criterion is Confusion Matrix
18If Exp(B) of a significant scale explanatory (X) on the event "to buy" is 2, then:
- AThis is not possible
- BEstimated Beta from X is greater than 1
- C1 more unit of X increases odds ratio of buying by 100%
- D1 more unit of X increases odds ratio of buying by 200%
19According to this image, which of the following is CORRECT? (60 seconds)
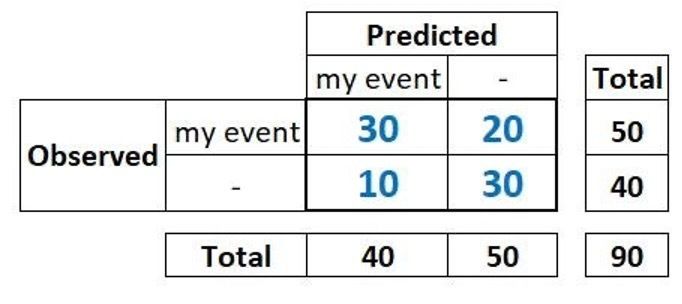
- ATrue Positive rate = 30/40
- B1 - Specificity = 10/40
- CPrecision = 60/90
- DAccuracy = 60
Información
- Descripción
- Informática Test sobre Review Machine Learning, creado por Angel Intriago el 12/12/2021.
- Autor
- Angel Intriago
- Idioma
- English
- Visitas
- 8
- Etiquetas
- Valoración
- Aún sin valoraciones Valora este test