
Fichas
DAtaAnalyticsAIMachineLearningAMIA22
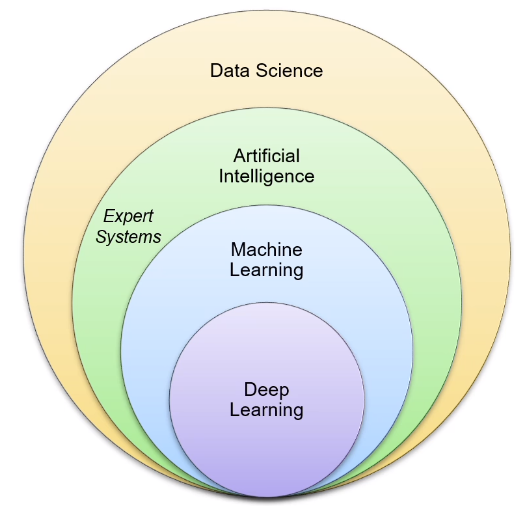
Fichas del conjunto (200)
- 1define data science?science of organizing /analyzing massive amounts of data
- 2define Artificial Intelligenceability of a computer / computer controlled robot to perform tasks commonly associated with intelligent beings
- 3what is an expert system?a system in which human knowledge is encoded in a knowledgebase
- 4define machine learning?Algorithms which allow computers to "learn" without explicit programming
- 5What is Deep Learningspecific set of ML tools designed to handle big data
- 6describe from broad to specific data science continuum?
- 7What is "Narrow AI"?machine performs a single specific task better than a human
- 8What is General AImachine can perform any intellectual task with same accuracy as a human
- 9What is Strong AI?a machine outperforms humans in many tasks
- 10What is AI effect/Tesler's theoremAI is whatever has not been done yet
- 11WHat is Autonomous intelligence?AI is making decisions (no human in the loop)
- 12What is Augmented Intelligence?AI used to augment or assist humans in their work - maintains human in the loop ultimately in making decisions
- 13What are expert systems?contain rules, relationships, ontologies explicitly encoded or programmed into a knowledgebase --> rules engines
i.e. MYCIN, Internest-I, CADUCEUS
limited amount of data handling compared to machine learning - 14How does Machine learning work?not based on human knowledgebases or specified rules. uses algorithms to learn repetitive data patterns and discover new patterns to make predictions. usually can handle large amount of data in complex settings
- 15describe differences btw statistics and machine learning
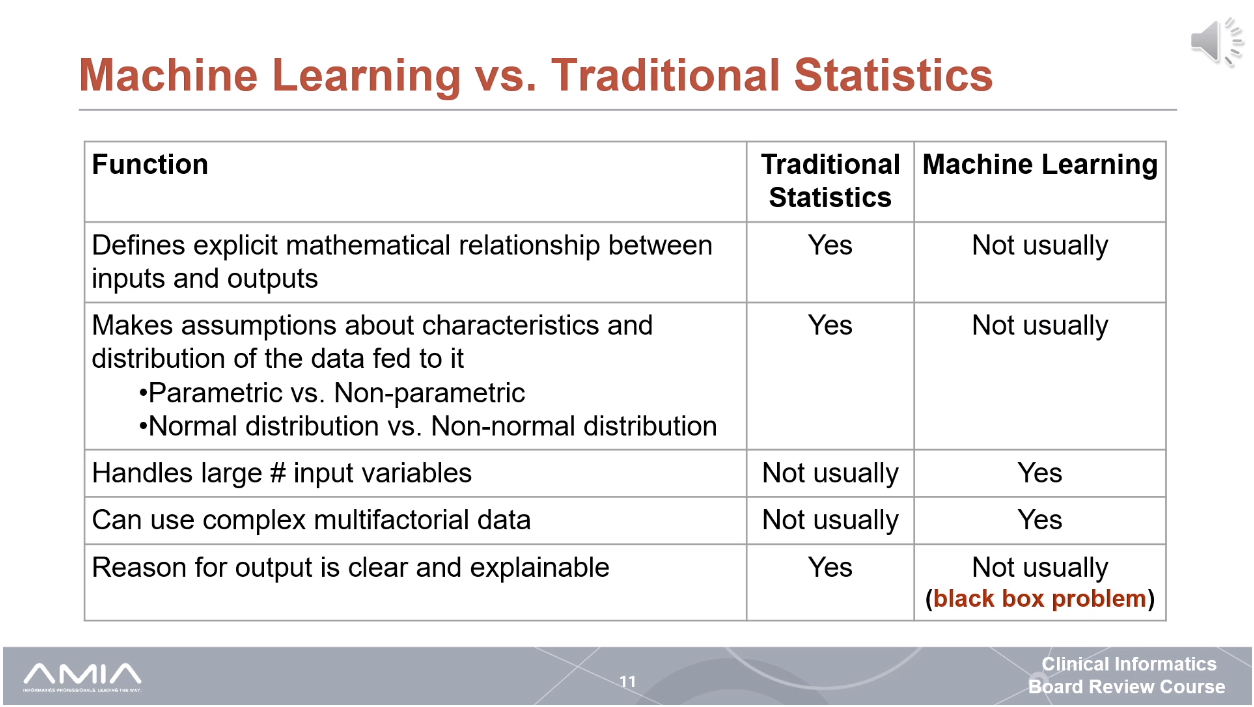
- 16what is the difference btw machine learning and traditional programtrad program - input --> human specified rules -->analyze data --> output data
ML == input/output data --> computer algorithm--> computer specified rules for analysis - 17what are uses of AI in HealthcarePredictions (dx, staffing, malware attacks)
Classification (pattern detection)
Decision support (prior auth)
Signal conversion (NLP)
Problem-solving
Anomaly detection
Assistance with time consuming tasks (mitoses counting, documentation, prior authorizations) - 18what is automation bias?assumption that the computer is right, even when it doesn't make sense
- 19Why is data quality so important for AI?BAd data == Bad Model
- 20Name challenges around data for AI Model developmentBad Data
Insufficient quantity or variability
DAta Labels with human bias/false beliefs
incomplete, inaccurate or variable labels
critical input data may be missing - 21what is Polanyi's paradox?human knowledge of how the world functions and decision making and of our own capability are, to a large extent, beyond our explicit understanding.
- 22What is a Brittle AI Model?it is unstable, i.e. do not produce consistent results when given similar inputs
- 23what are humans better at than AI Algorithms?they are better able to factor in general features/ and/or situational awareness
- 24How can a hacker make an AI model brittle?by introducing small changes to data ( called adversarial data) to make the algorithm produced incorrect outputs
- 25define Transparency from a model developer standpoint?reasons for model's performance are known and understood
- 26Define transparency from an end-user of a models perspective?sufficient information is published such that the model's performance can be audited
- 27What is the black box problem?when AI algorythm is trained, the rules developed are indecipherable by the model developer or users , making it impossible to know how or why the model's output is what it is
- 28What are the 3 main categories of AI Ethics?Beneficence, Intelligibility, and Accountability
- 29define Beneficence?maximize benefit with minimal risk and harms
- 30What are recommendations of ACR and RSNA regarding human Autonomous AI?Do not allow Autonomous AI until sufficien Augmented AI (supervised AI with human in the loop decision making) has significant experience in healthcare
- 31What makes up Intelligibility of AI ?Combination of Transparency and Explainability (XAI)
- 32what are conditions of transparency for AI?sufficient information published about design before implementation- how designed, intended use, data used, etc and also means that a person is aware that AI is being used on them
- 33What is Explainability?provides the user with explanation of how the AI Tool works?
- 34list the 4 general principles of explanability?1) Explanation - evidence/reason for outputs
2) Meaningful - understandable explanations
3) Explanation Accuracy - correctly reflects the system process to produce output
4) Knowledge Limits - only operates for conditions designed for and when there is sufficient confidence of outpu - 35What is AI Auditability?monitor tool for performance and ensure ethics maintained, formal oversight, responsibility for monitoring in place and Responsiveness to fixing issues when AI is not working appropriately
- 36What is AI Accountabilityperson/entity accountable when something goes wrong with AI - person, organizationa, or regulatory
there may be medicolegal liability too as it is not Standard of Care - 37What does CLIA mandate of AI algorithms if used for production use in the laboratoryAlgorithms would have to be STATIC, and unchanging prior to validation and use in the lab
- 38list financial, technical, personal and organizational issues with implementing AI in healthcare
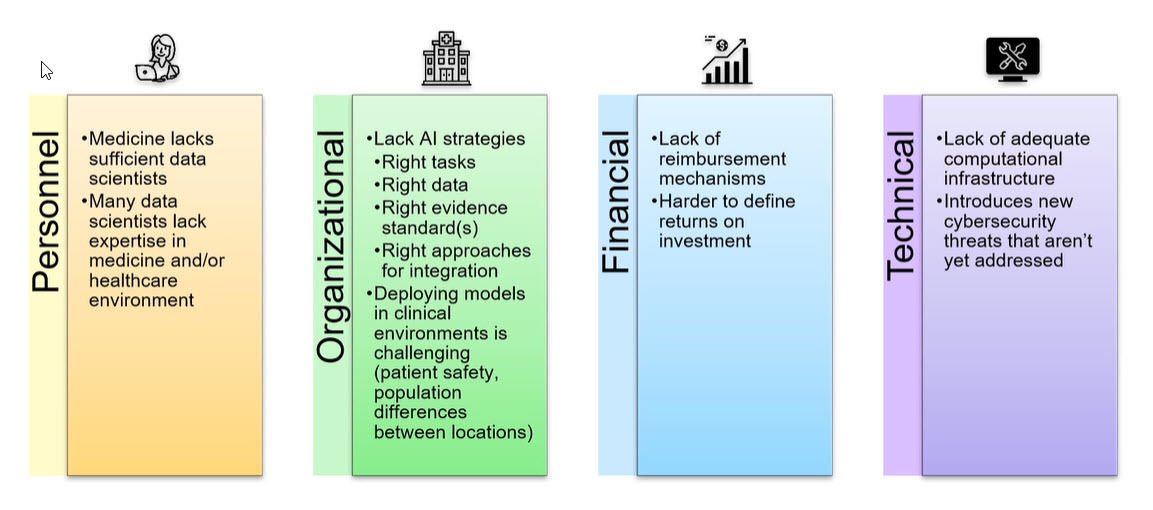
- 39Define Supervised Learning?trains on data that has been classified or labeled with the goal of training model to generate KNOWN answers , patterns or relationships
- 40what is fully supervised learning?All the data is labeled to the same extent ( same degree of detail)
- 41What is semi-supervised learningn?some data labeled, some not - unlabeled data may be auto-labled to match labeled data
- 42what is weakly supervised learning?small amount of data have detailed labels, the rest has fewer data
- 43What is unsupervised learning?Data which is NOT classified or labeled with goal of model discovering NEW and previously unknown patters or relationships
- 44What is Reinforcement Learning?used to learn how to reach a complex goal Environment status - perceived by Agent--> action executes --> reward/penalty--> New environment state--> next interation
- 45give 2 examples of reinforcement learningGameplaying - i.e. Watson/Jeopardy
Speech to text , financial trading - 46What is the goal of Reinforcement learning?To Learn a policy ( value function) through trial and error to optimize a long term reward
- 47what is a reinforcement learning Policy?function which outputs optimal action to maximize the expected average reward
- 48What is a value in reinforcement learning?Future reward received by taking an action in a particular state.
- 49How is reinforcement learning different from Supervised and Unsupervised learningUses unlabeled data like unsupervised learning but also uses known Outcomes to affect model training like supervised learning
- 50What is a Markov Decision Process?use with a KNOWN model where all states, actions, probabilities of actions generating states, rewards, and penalties are all EVIDENT
- 51What is Q-learning?finds optimal action-selection Policy (function) for any given finite Markov decision process
- 52What is a Monte Carlo Method?one or more of the elements in the model of reinforcement learning is UNKNOWN and so it runs the process many times, and each state is reached many times (s1-sN) and the average outcomes from all previous experiences is made so that the probability o the action --> that state can be calculated
- 53What is Transfer Learning?Data used for training a model are "transferred" from a different related domain (imagenet data for medical images)
First do course training on the data , then use domain related data set (which is smaller) to fine tune the training - 54When is needed to use Transfer Learning ?When data is EXPENSIVE or rare and there is higher quality, and quantity of data available that is cheaper to use in another domain
- 55What is an "instance" of data?single event in a data set
- 56What is an "outlier"instance of data which is significantly different from the remaining instances in the population -
- 57why is outlier data bad for ML?can skew the model results
- 58What is a labelUsually an observed value for the individual instance
- 59What is a feature ?Variable (aspect ) of the training data
- 60what are 3 other terms in ML for a Feature?A Vector
An Attribute
Dimension (in clustering and instance based methods) - 61what is a geocoder?feature that maps the instance onto a map so that you know the location
- 62define an algorithm?a repeatable process used to train a model from a given set of training data
- 63What is a model Parameter?Internal values inside a machine learning that the model derives based on training data - examples include "weights" and "bias" values
- 64What is a ML Model made up of?The Algorithm + parameters
- 65What is a ml model that is used for classification called?Classifier
- 66What is a weak Learner Model?a model whose performance is only slightly better than random chance
- 67What defines a good model?A model that generalizes to new data and performs as well as it did on training data and test data
- 68What is an epoch?When the model uses the training data 1 x
i.e. 1 pass through training data - 69What is a Hyperparameter ?A Parameter that is manually set PRIOR to running the algorithm i.e. the model does not set this parameter, it is set manually!
i.e. limits, changes in weights that loss function can make per training step - 70What is called when you adjust the hyperparameters of a model during model optimization ?Tuning
- 71Give two examples of HyperparametersLimit on Total # of epochs
K in the K-means clustering algorithm - 72What is the algorithm/model Loss Function?measure of the deviation from the correct output i.e. the error of the model
Other names = objective fn, cost fn - 73What is Stochastic Gradient Descent Method for minimizing the loss function?mathematically descend the curve f the loss function to a minimum value to approach the minimum amount of error - common and effective training method
- 74which types of models do most Model Evaluation Methods work to evaluate for?SUPERVISED MODELS
- 75what is the difference between signal and noise in a ML Model?signal = true underlying patter you are trying to learn from the data
Noise = irrelevant information/randomness in a data set - 76What must a good ML Model due with respect to signal vs noiseSeparate signal from the noise
- 77What is Irreducible error?noise that can't be reduced by optimizing the model algorithm
- 78What can sometimes help with reducing irreducible error?cleaning of the data better
- 79What is the causes of Irreducible error?Inherent randomness, misframed problems, incomplete feature sets
- 80What is the definition of Bias?measure of inaccuracy of the model
- 81Wat is Model Variance measure?measure of imprecision (i.e. lack of reproducibility )
- 82What does HIGH Bias and Low Variance mean?consistently inaccurate results
- 83What does High Variance and Low Bias meanInconsistently accurate results
- 84describe all 4 combinations of bias vs Variance
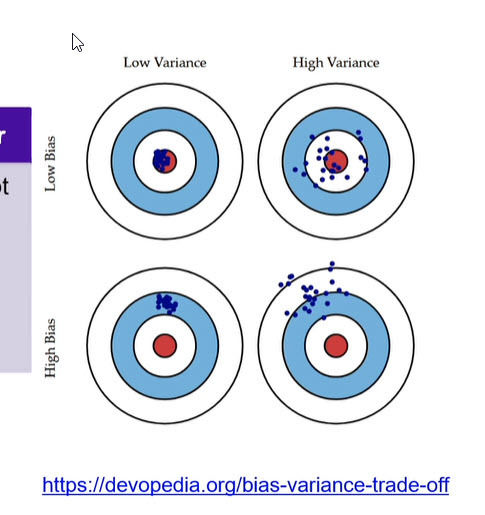
- 85What does a model that has high bias mean?The model is inaccurate = UNDERFIT
- 86What does a model with LOW bias mean?The mode is accurate (but may be OVERFIT)
- 87what is equivalent to Imprecision of a model ?Square of the standard deviation of error -usually due to small fluctuations in the training set
- 88what does a high variance of the model mean?model is imprecise ( and likely OVERFIT)
- 89What does a low variance mean of the model mean?Model is precise ( but may not be accurate and be underfit)
- 90what is the BIAS -VARIANCE trade off?Things that reduce bias, increase variance
Things that reduce variance, increase BIAS - 91What is total Error equal to?TE = Bias Squared (B^2) + Variance+ Irreducible error
- 92What is goodness of fit?How closely the model's output values match the true values
- 93What is underfitting for a model?the model does not accurately predict output for the data fed into it.= usually due to high bias, and low or high variance
- 94What are the causes for underfitting?too simple or rigid a model for the data, training is stopped to early, hyperparameters are suboptimal, not enough features selected, or suboptimal features are used , or training data is more simple than real-world data (i.e. underrepresented populations)
- 95When is a model OVER FIT?Occurs when the model EXACTLY fits the Training data but doesn't fit new data well (either test or production data)
if the training set has low error rate but test data has high error rate = HIGH VARIANCE - 96What causes Overfitting?too many features selected for # of instances in the data set (most common) , model selected is designed for data more complex than data examined, model is trained too long (too many epochs), or training data is more complex than real world data
- 97what is a good rule of thumb for # of features to use for your ML Model?Don't use more than 1 Feature / 10 instances for your model.
- 98If your Overfiiting is due to too many features, how can you correct?remove irrelevant features in model, reduce the number of features ( dimension reduction) or increase total number of instances in the training data.
- 99If your overfitting is due to more complex than real world data, how can you fix it?add instances to avoid sampling error and reduce complexity
- 100If your overfitting error is due to the model being too complex for the data,choose a simpler model --> REgularizaiton
- 101What is the evaluation model called a confusion matrix that is used for supervised learning models?technique to assess the model confusion -(i.e assigning the instance to the wrong class or outcome) --> evaluate for each outcome/class the model produces i.e. binary outcome has 2 x 2 confusion matrix
# columns , # rows = # of output classes - 102What is confusion matrix metrics formulas
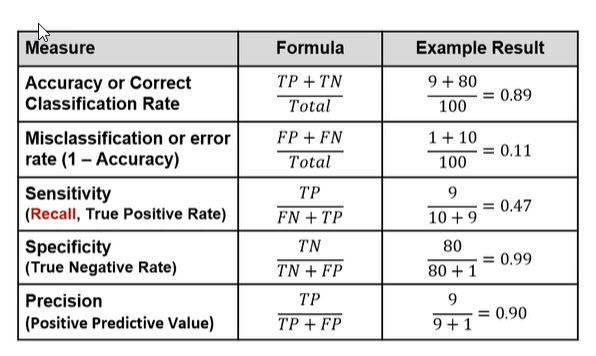
- 103What is the null error rate?For classification methods, rate of being wrong if you always pick the majority class
Null Error Rate = (Total instances - Major Instance Class ) / total Instances - 104What is a Model Accuracy Paradox?A classifier may have a higher error rate than the null error rate - occurs when the condition /outcome is very low percentage of the overall data set (i.e. 1%)
- 105What do you need to do if you are trying to predict a very low incidence disease?either use huge population of data, or use different statistical methods i.e. F0 score, Matthews correlation coefficient, and stratified K-fold cross-validation
- 106What is Cohen's kappa evaluation method for a classification model?Measures how well the classifier performs compared to random chance
- 107What are "calibration" methods for evaluation classification models?you plot the observed vs. expected probability of class membership to produce a "reliability" diagram to determine how reliable the model is for predicting the correct class
- 108What are three methods for evaluating regression models?Root means Squared Error
correlation coefficient
Coefficient of Determination (r^2) - 109What is the root mean squared error?N= # of measurements
xi= observed measurement
xtrue = actual measurement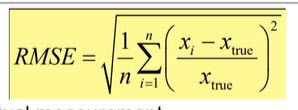
- 110What does a low Root mean squared error mean for the model?The model is a good fit --> more observed values match expected value
- 111What does a higher Root mean square error mean for test data than for training data?Model has overfit problem with training data
- 112What does a correlation coefficient tell you?The strength of relationship btw X and Y on a scatter plot
Perfectly correlated r= 1
No Correlation r=
Perfectly negatively correlated r= -1
Correlation Does not equal causation - 113What does a Coefficient of Determination equal?square of correlation coefficient = goodness of fit i.e. represents the percent variation in Y that is NOT explained by variation in X
values = 0-1 and expressed as percent
100% = perfectly fit model - 114What is "Discrimination capability " evaluation for a either supervised or unsupervised models ?measures the models ability to discriminate between groups , classes or clusters
Uses ROC curves - 115what is the other name for Area under the curve ?Concordance C statistic
AUC of 1 = perfect discrimination btw groups - 116What should the model that is doing diagnostic classification have for an AUC?as high as possible ( near 1)
- 117What should the AUC be for a model that will "augment" human decision making ?btw 0.7 and 0.9
- 118IN model development, what is te most expensive and time consuming part of building the model?gathering the appropriate data
- 119why do you want features to have similar/same scales of measure or labels with similar /same names?Helps the model learn the data more easily
- 120What are the challenges with using manual labeling of a data set?May introduce bias, error prone, May not be standardized
- 121What are the types of automated labeling techniques ?1) use human labeled data as a template, and the algorithm labels the rest
2) No human labeled data as a template - 122What is multiple-instance learning ?Auatomtically learns important details of instances grouped under broad labels
- 123What does it mean to "clean " data?normalize data to normal distribution around 2 standard deviations
correct missing/erronous data
remove outliers if possible without introducing bias - 124when you partition your data, what are the three groups you could create?Training data 60-80%
Validation Data (tuning set) 10-15%
Testing data ( 10-30%) - 125How should your partitioning occur for your model development data?Randomly split with no overlap btw data sets
- 126What are the Features of a model?Independent variables - <1 feature/ 10 instances
Selected based on likely association / or ability to explaine the dependent variable which is teh outcome /condition - 127What is the concern if Features are Human Selected?worry about human bias--> constrains model and features may not be relevant or optimal
- 128What kind of model has its features automatically selected by the algorithm?Deep Learning Models
- 129What is Forward Selection of Features?Automatic feature select method where iterative inclusion of new features are added as long as it makes a contribution that explains the variation in the dependent variable - stops when no more found
- 130What is Backward Selection of FeaturesFor Regression models only, you remove features if it worsens the strength of association , iteratively remove features until the removal worsens the strength of association
- 131What is Stepwise Feature Selection ?combine Forward and Backward feature selection --> 1) add forward feature, then all included variables are evaluated for backward selection to validate that addition of the forward feature
- 132What is forced inclusion of features ?features selected based on known association from prior studies.
- 133If your data set has a known output label, what type of model should you use?A supervised Learning Model
- 134If your data set doesn't have a known output Label ,what type of model should you use?an unsupervised model
- 135If your supervised model data set has categorical outcome labels, what type of model should you use?A Classifier model
- 136If your supervisde model data set has a numerical outcome labels, what type of model should you use?A regression model
- 137If your using unsupervised learning and your output is categories/clusters what kind of model should you use?A clustering method
- 138If you using unsupervised learning model and your expected output is association btw independent variables, then what kind of model should you use?Association Rules Model
- 139If your using an unsupervised learning model and your expected outcome is reducing # of selected features?Dimension reduction methods
- 140what is the model validation method of choice when you have small data sets?K-fold Cross Validation
- 141What is the K-fold Cross Validation method?divide data into 5-10 folds, and then run the data with 1 fold as validation and remaining as training data, repeat for each fold as a validation set and then average the quality metrics across all the k-run
- 142describe the Leave One Out Cross -Validation Method for Model Validation?extreme k-fold cross validation method where the data set is too small for folds, so you use k=n number of instances - problem is this may focus on noise so not recommended.
- 143what is bootstrappingmethod of starting with N instances and creating a new population of n instances by 1) randomly drawing a single instance out and placing in the bag 2) randomly draw another instance out of the original population as if nothing had been taken 3) continue until N number of draws completed.
- 144What are the instances in the bag in a bootstrapping method of validation called?"bootstrapped sample"
- 145T/F - becuase you are always drawing from the entire original population, it is likely that the same instance may be selected more than oneTrue
- 146In bootstrapping validation method, what are the instances that have never been drawn called?"out of bag" sample
- 147what is the outcome of bootstrapping method for validation as N number of instances increases?on average 60+ percent are selected for the bag and 30% are selected for out of bag allowing developers to use the bag instances for the training, and validate on teh out of bag instances.
- 148What are the pros and cons of bootstrapping?pro- works well for small data sets, and handles others as well, makes no assumption about the distribution of data, allows for calculation of standard errors and confidence intervals.
con= require long computation time, will have margin of error - 149what are methods for model optimization?Tune (adjust) hyperparameters
Dimensionality reduction
Regularization
Consider a different model - 150what is the main goal of model optimization? (tuning)minimize deviation from the correct output (i.e. minimize the loss function)
- 151what is regularization?methods that force an algorithm to build a less complex model ( i.e. more generalizeabel --> less likely to overfit data
- 152what happens with regularization?place constraints on model variability when noisy data, select features and adjust weights to zero which "eliminates the features, prevents parameters from getting too large --> slightly higher bias, minimize the loss function for data
- 153Name some mathematical methods for regularization ?Least Absolute Shrinkage and Selection Operator (LASSO L1 ) regularization
Ridge L2 regularization
Elastic Net Regularization (L1+L2 combo)
special regularization for Neural Networks - 154What are non-mathematical methods for regularizationEarly stopping
Pruning
Decision trees - 155What could be the cause of difference in test set data from the validation set ?Bias or Variance
- 156what are the 2 types of deployed models used?Static models
Incremental/continuous model - 157What is a static deployed model?model is used without further changes, no more training
This is the most common model in medicine - 158What is an incremental/continuous model?incrementally or continuous training even after deployment and can not be used in certain medical environments (i.e. lab testing) requires special monitoring and controlling to ensure it is performing accurately
- 159what should models undergo after deployment ?Verification - performed at local site to ensure performance is working in new site.
- 160what is model stability?The ability of a model to produce similar output over a range of similar inputs, including inputs not previously seen but which are substantially different from prior inputs = robust model
- 161T/F - Artificial neural networks are only unsupervised learning algorithms.FALSE - they can be supervised or unsupervised
- 162How do ANN's work?opererate via a flow of signals through nets of connection trained to optimize each node to node connection via adjusting weights , biases, overactivation functions
- 163What are the 2 main limitations of ANNsComputational intensive
Black Box Problem - not transparent or explainable - 164What are Nodes in a NN?Transfer Functions
- 165what are connectons in a NN?edges
- 166What is Back-propagation?proces where ANN learns whether it made a mistake or not based on output ---> adjusts internal parameters of transfer functions (nods) using loss functions and stochastic gradient descent fucntions in waves of propogating backwards from teh output nodes to the input modes
- 167In a ANN, what is the input layer nodes equal to?# of nodes = # of features in selected data
- 168In an ANN what is the output layer # of nodes?The # of output categories of data
- 169What is the difference between an ANN and Deep ANN?ANN have at least 1 ( shallow network) hidden layer and Deep ANN has >3 hidden layers
- 170what is a feed-forward ANN?a unidirectional from input to output model - oldest type of ANN
- 171Describe a multi-layer perceptron (MLP) aka - vanilla neural networkShallow feed foward network that is fully connected with 1 or more hidden layers
- 172Define a Perceptroniterative algorithm that determines the best falues for the coefficient vector
- 173how do you train a MLP?start with input--> propogate data to output layer, calculate the output error, and backpropogate teh error to adjust the weights and biases to minimize the error. Do this over multiple epochs to identify the ideal weights and biases
- 174Define a Convolutional Neural Networkdeep learning network used for recognizing sub-patterns and motifs in unstructured data i.e. image analysis
- 175what is a convolution?Mathematical operation on two functions that produces a 3rd function that describes how shape of one function is modified by the other
- 176What is a convolution filter layer?data (pixels for images) that match the pattern of weights are amplified (hot spots)
- 177What is a pooling layer?masks data except for the amplified values (hot spots) which creates a feature activation map
- 178how does image analysis CNN work?cycles of convolutions to pooled layers repeated until defined set of criteria are reached and then data sent to the feed forward network to get an overall classification/feature selection of the data (image)
- 179what are CNN's used for?Image Analysis
time sequence data classification
Gene sequence classification - 180what is a saliency map?feature activation map directly overlaid on the original image and shows which features are more relevant but doesn't tell you why
- 181What is an advantage of CNN vs. other types of neural networks?less black box than other types, but still don't know why
- 182what is the common use case for Recurrent Neural Networks?used for text classification (NLP)
and time-series data (audio, text feeds)
and Anomaly detection in quality control data - 183how do RNN's work?output is recursively fed back to itself to inform the next prediction ( analyzes both current and past data) i.e. data from prior instances is used as input for subsequent instances and they can accumulate historical data --> context nodes - have their own weights and adjusted via back propagation during training
- 184What is a long short term memory network?an RNN with data storage units called gated nodes that can flexibly represent short-term or long-term data
- 185What is a Generative Adversarial Network ?used to generate deepfake images , pairs deep learning NN trained in tandem repeatedly with 2 networks: A descriminator network and a Generator network.
- 186What does the generator network of GAN do?with each iteration, increases ability to fool the discriminator network
- 187what does the discriminator network of GAN do ?With each iteration , increases ability to discriminate btw synthetic instances created by generator network and real instances
- 188how does GAN training work?Generator network takes real instance data, generates synthetic instance data, passes both the discriminator network which tries to determine which is real which is fake. IF discriminator wrong - penalty to discriminator, if correct --> penalty to generator.
- 189when do we use regression algorithms?When the dependent variable (output) is "continous" (i.e.numerical)
- 190which algorithm requires the least number of training instances?Regression methods
- 191what do Regression methods do?Describe, estimate, or predict the linear relationship between 2 or more numerical variables
- 192what are some usecase for regression methods?estimating life expectancy, staffing shortages, population growth, pandemic spread
- 193What is simple linear regression also known as and why?Univariate Regression - single input variable usually
- 194What is a simple linear regression used for?model to find the line of best fit which can then be used for prediction of Y based on X
* assumes linear relationship btw dependent variable y and independent variable x - 195what is the function for simple linear regression?y = Bo + B1x + e
B1 = slope = Regression coefficient
Bo = y intercept
e = error
Uses the method of least squares to find the best line through the data - 196what is multiple linear regression used for?Determine the strength of relationship between 2 or more independent variables and a dependent variable ( no colinearity between independent variables)
- 197what is the high level functionyi = Bo+B1x1 +B2x2_....Bixi+ ei
- 198What is Polynomial regression used for?model non-linear exponential data - like growth rates, pandemic progression etc
input is single independent variable and outpu t is single dependent variable- used for non-linear exponential data - 199what is polynomial regression formula?yi = Bo+B1X+ B2X^2+... +BiX^i+ ei
- 200what is polynomial regression at risk for?overfitting because very sensitive to noise
Información
- Descripción
- informaticsBoards DAtaAnalytics Fichas sobre DAtaAnalyticsAIMachineLearningAMIA22, creado por Michael Riben el 10/10/2022.
- Creado por
- Michael Riben
- Visitas
- 1
- Valoración