
Quiz
Knowledge Check
Este quiz tem tempo limite, por isso abre no player de sempre.
Perguntas do quiz (15)
1Which of these is the last step of an iteration within the CRISP-DM process?
- AAnalysis
- BDeployment
- CModelling
- DEvaluation
2If a model predicts the number of days a customer takes to come back to a company's website, which metric is the most adequate to assess the performance of the model?
- ARecall
- BAccuracy
- CPrecision
- DMean absolute error
3Machine Learning steps generally followed
1) [blank_start]_________________________[blank_end]
2) [blank_start]_________________________[blank_end]
3) [blank_start]_________________________[blank_end]
4) [blank_start]_________________________[blank_end]
5) [blank_start]_________________________[blank_end]- AData Ingestion
- BPreparing Data
- CBuild and Train Models
- DModel Deployment
- EMonitoring Models
4A face recognition model for accessing a gym is posing issues because it denies access to too many customers. Why might this be?
- AThe model is too sensitive and a higher threshold would solve the problem.
- BThe model is too specific and a lower threshold would solve the problem.
- CThe model is too specific and a higher threshold would solve the problem.
- DThe model is too sensitive and a lower threshold would solve the problem.
5What is PII?
- APublicly Identifiable Information
- BPersonally Identifiable Information
- CPersonally Identifiable Index
- DPublically Incriminating Index
6What is used to compare the predicted and actual values of a binary classification model?
- ACorrelation coefficient
- BBLEU score
- CR-squared value
- DConfusion matrix
7A weather forecast model must update its predictions first thing in the morning, everyday. It is trained on daily historical data, available publicly, but that data is only refreshed at noon each day, so it is not available at the correct time necessary for updating the model's predictions. How could this problem be solved?
- AReplicate the dataset and run the predictions in production with that.
- BTrain the model with different data because the model must make inferences using the same type of input data it saw during training.
- CReplicate the dataset and train the model with that.
- DDo not use the dataset when running the model in production.
8An online retail company wants to improve the speed at which it analyzes how users interact with its website. What is the most pressing architectural question you would address first?
- AWhether the data ingestion processes are event-driven and real time, or nightly batch.
- BWhether the data is being put into a data lake before analysis
- CWhether processes str in place to clean and preprocess data before storage
- DWhether business rules are applied on data in transit or in-situ
9Which module would you use to evaluate the performance of a binary classifier using scikit-learn?
- Asklearn.metrics.r2_score
- Bsklearn.metrics.mean_absolute_error
- Csklearn.metrics.auc
- Dsklearn.metrics.median_absolute_error
10After sampling 10,000 values of a random variable you observe that the mode, median, and mean are the same. What is the most likely variable distribution?
- APoisson distribution
- BNormal distribution
- CUniform distribution
- DLogarithmic distribution
11Which technique can be useful to handle highly imbalanced true/false labels?
- ASystematic sampling
- BStratified sampling
- CConvenience sampling
- DSimple random sampling
12You have a dataset with Female and Male features. What will be the feature names when the code below is executed?
import pandas as pd


def azureml_main(dataframe1 = None, dataframe2 = None):
    pd.get_dummies(dataframe1)
    return dataframe1,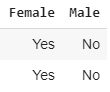
- AFemale, Male
- BFemale_No, Male_Yes
- CFemale_Yes, Male_No
- DFemale_Yes, Female_No, Male_Yes, Male_No
13You have a dataset that you want to use for your company's ML algorithm. It has 30 dimensions and you want to reduce the size to 3 dimensions to decrease memory usage and computation time. Which method should you choose?
- At-Distributed Stochastic Neighbor Embedding
- BLinear Discriminant Analysis
- CK-means model stacking
- DPrincipal Component Analysis
14What is Kubernetes?
- AA proprietary platform built by Google and Docker to run and manage your applications.
- BA container orchestrator to provision, manage, and scale applications.
- CA serverless platform to build and manage your apps.
- DAn an open-source system to deploy, manage, and run Cloud Foundry apps.
15Your team is building a data engineering and data science development environment.
The environment must support the following requirements:
✑ support Python and Scala
✑ compose data storage, movement, and processing services into automated data pipelines
✑ the same tool should be used for the orchestration of both data engineering and data science support workload isolation and interactive workloads
✑ enable scaling across a cluster of machines
You need to create the environment.
What should you do?- ABuild the environment in Apache Hive for HDInsight and use Azure Data Factory for orchestration.
- BBuild the environment in Azure Databricks and use Azure Data Factory for orchestration.
- CBuild the environment in Apache Spark for HDInsight and use Azure Container Instances for orchestration.
- DBuild the environment in Azure Databricks and use Azure Container Instances for orchestration.
Informações
- Descrição
- Quiz sobre Knowledge Check, criado por Mohammed Arif Mazumder em 25-04-2020.
- Idioma
- English
- Visualizações
- 6.072
- Etiquetas
- Avaliação
- Ainda sem avaliações Avalie este quiz