
Quiz
BIOL2022 L22 nMDS and hypothesis testing
Este quiz tem tipos de pergunta que abrem no player de sempre.
Perguntas do quiz (10)
1Label the steps appropriately (please).
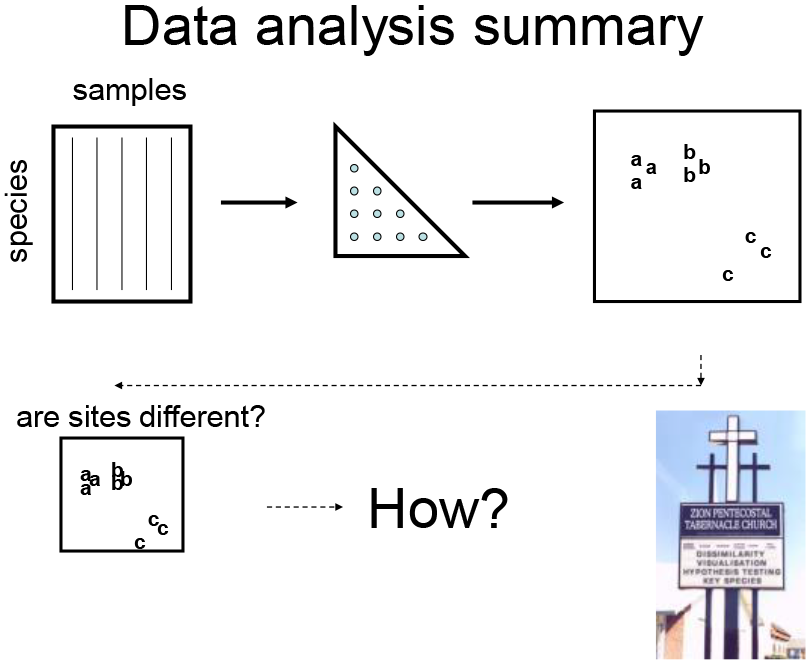
- A(dis)similarity matrix
- BnMDS
- CANOSIM
- DSIMPER
- EANOVA
- FPERMANOVA
2Species diversity indexes:
Different diversity indices emphasise different things. Two examples are the following. Which emphasises what?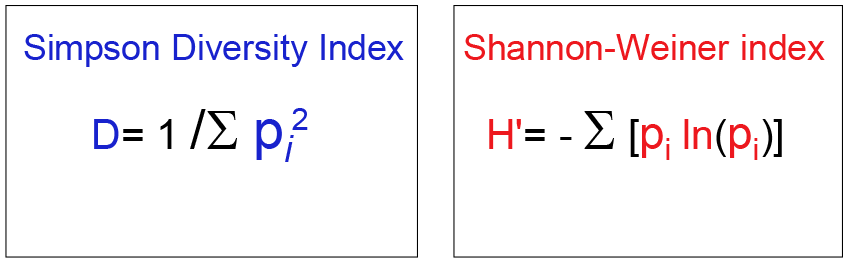
- AEmphasises common species
- BEmphasises rare species
- CEmphasises non-zero correlations
- DEmphasises zero-correlations
- EEmphasises similarities
- FEmphasises dissimilarities
3In either the Simpson’s index or the Shannon-Weiner index, despite their differences, they both have high index values if:
- AEvenness is high
- BEvenness is low
- CThere are few species
- DThere are many species
- ENone of the above
4In a(n) [blank_start]____________[blank_end], a [blank_start]________[blank_end] stress value means the model is good.
- ALow
- BHigh
- CnMDS
- DANOSIM
- EPERMANOVA
- FSIMPER
- GBray-Curtis dissimilarity matrix
5In a Bray-Curtis dissimilarity matrix, a low number means:
- AHigh dissimilarity
- BLow dissimilarity
- CHigh similarity
- DLow similarity
6ANOSIM is ANalysis Of SIMilarities.
Retains philosophy underpinning [blank_start]________[blank_end], driven by [blank_start]________[blank_end].
Hands [blank_start]________[blank_end] designs best.
[blank_start]____________[blank_end] permutation test combined with randomisation approach to generate significance levels (Monte Carlo tests)
Null – no difference in assemblage composition [blank_start]________[blank_end] sites.- AnMDS
- BANOVA
- CPERMANOVA
- DSIMPER
- EInformation theory
- FHypothesis testing
- GSimple
- HComplex
- INon-parametric
- JParametric
- KMetric
- LNon-metric
- MWithin
- NBetween
7Steps for ANOSIM:
1. Test statistic – reflects difference among sites to differences within sites. Based on rank similarities in the underlying triangular matrix, generates [blank_start]____________[blank_end].
2. Recompute [above] under permutations of sample labels. If null is true there should be little change to [above] if labels arbitrarily assigned.
3. Significance value – refer the observed value of [above] to permutation distribution. If it is unlikely (<5%) to fall in this distribution, reject null H- AGlobal R
- BStress value
- CP value
- DPearson's correlation
8Which statistical test works with any distance measure that is appropriate to the data, and uses permutations to make it distribution free?
- APERMANOVA
- BANOSIM
- CANOVA
- DSIMPER
9Which statistical test calculates % contribution of each species to the dissimilarities between all pairs of sampling units in different groups and % contribution to similarities between all pairs within groups?
- ASIMPER
- BPERMANOVA
- CANOVA
- DANOVASIM
10Which one is capable of working with more complex designs?
- APERMANOVA
- BANOSIM
Informações
- Descrição
- Module 3, Lecture 4 Headings: • Hypothesis testing • nMDS • ANOSIM • SIMPER
- Autor
- Michael Jardine
- Idioma
- English
- Visualizações
- 98
- Etiquetas
- Avaliação
- Ainda sem avaliações Avalie este quiz