
Quiz
Comparing two means
Erstelle ein kostenloses Konto, um dieses Quiz zu beenden
Speichere deinen Fortschritt und sieh dir dein Endergebnis an.
oder mit deiner E-Mail registrieren
Schon ein Konto? Anmelden
Fragen in diesem Quiz (25)
1T-test are useful for detecting what kind of effect? BEST RESPONSE
- AAn association between variables.
- BA difference between two means.
2Select ALL TRUE statements.
- AUnlike methods such as regression and correlation methods such as ANOVA and t-tests allow us to make casual inferences.
- BUnlike methods such as ANOVA and t-tests methods such as regression and correlation allow us to make casual inferences.
- CEach of these tests mentioned can be considered mathematically identical.
- DThe type of statistical test is not what is relevant to causal inference. It's the fact that in experiments we manipulate the causal variable systematically to see it's effect on an outcome.
- EIn correlational research we observe the co-occurrence of variables, we do not manipulate the causal variable then measure the effect on the outcome. Therefore we cannot compare the effect of when the causal variable is present against when it is absent. Thus we cannot say which variable causes a change in the other, we can only say that both variables co-occur in a certain way.
3An independent design (alternatively between-groups or between-subjects design) is
- Aan experimental design in which different conditions utilise different (organisms etc). (e.g in psychology this would mean using different people). As such the resulting data can be considered independent.
- Ban experimental design in which different conditions utilise the same organisms. (e.g in psychology this would mean using the same people to take part in two experimental conditions).
- Can experimental design in which all variables can be considered independent (i.e there are no dependent variables)
4A repeated measures design (alternatively, a within-subjects design) is
- Aan experimental design where different conditions utilise the same organisms (i.e. in psychology such a design would mean that the same people take part in all experimental conditions). As such the resulting data are related.
- Ban experimental design in which different conditions utilise different organisms. (e.g in psychology this would mean that different conditions conducted on different people.
- CA design that only utilises independent variables.
- DA design that only utilises dependent variables.
5Median splits, i.e dividing people into groups based on the median is generally a good idea.
- ARichtig
- BFalsch
6An experiment that compared the ratings of a film where one group of participants were subjected to small electric shocks compared to a control group who just watched the film could be considered a
- ARepeated measures design
- BWithin-subjects design
- CIndependent design
- DBetween-subjects design
7What are the problems with NHS tests for normality (Kolmogorov-Smirnov) and homogeneity of variance (Levene's)
- AWRITE OUT ANSWER AND CHECK IN THE TEXT BOOK. pp184
- BREVISE AT THE END OF THE TEST.
8A t-test can be explained in terms of linear regression.
- ARichtig
- BFalsch
9What is the difference between independent and paired samples t-test?
- AIndependent-samples t-test -- This test is used when there are two experimental conditions and different participants are assigned to each condition.
- BPaired-samples t-test -- This test is used when there are two experimental conditions and the same participants took part in each condition.
- CIndependent-samples t-test -- This test is used when there are two experimental conditions and the same participants took part in each condition.
- DPaired-samples t-test -- This test is used when there are two experimental conditions and different participants are assigned to each condition.
10Which of the following are other names for a paired-samples t-test?
- AMatched-pairs t-test
- BDependent t-test
- CIndependent measures t-test
11T-tests: If samples come from the same population, then we expect their means to be roughly equal. Although it is possible for their means to differ by chance, we would expect large differences in their means to occur very infrequently. Under null hypothesis significance testing we assume that the experimental manipulation has no effect on the participants; therefore we expect that the sample means to be very similar.
- ARichtig
- BFalsch
12T-tests: We compare the difference between the sample means that we collected to the difference between sample means that we would expect to obtain if there was no effect. We use the standard error as a gauge of the variability between sample means.
- AIf the standard error is small, then we would expect most samples to have very similar means. However if the standard error is large, then it is possible that larger differences between means might occur due to chance.
- BIf the standard error is small, then it is possible that larger differences between means might occur due to chance. However if the standard error is large, then we would expect most samples to have very similar means.
13If the difference between the samples we have collected is larger than we would have expect based on the standard error then we can assume one of two things:
There is no effect and we have, by chance, collected two samples that are atypical of the population from which they came. OR The two samples come from different populations but are typical of their respective parent population. In this scenario, the difference between samples represents a genuine difference between the samples (and so the null hypothesis is unlikely).
The larger the difference becomes between the two sample means:- AThe more confident we become that the second hypothesis is correct. If the null hypothesis is incorrect, the we gain confidence that the two sample means differ because of the different experimental manipulation imposed on each sample. (causal inference)
- BThe more confident we become that the first hypothesis is correct. If the null hypothesis is correct, and thus we have no evidence to infer that the two sample means differ because of the different experimental manipulation imposed on each sample.
14A t-statistic is equal to
- A(The observed difference between the two means minus the expected difference between the two means (if there was no effect)) divided by the estimate of the standard error of the difference between two sample means.
- B(The observed difference between the two means minus the expected difference between the two means (if there was no effect)) divided by the estimate of the standard error of the combined sample mean
- C(The estimate of the standard error of the difference between two sample means) divided by the observed difference between the two means minus the expected difference between the two means (if there was no effect).
- D(the standard error of the combined sample mean) divided by the observed difference between the two means minus the expected difference between the two means (if there was no effect).
15When different participants participate in different conditions, pairs of scores will differ not only because of the experimental manipulation, but also because of other sources of variance (such as individual differences in age, IQ etc).
This statement applies to:- AIndependent t-test
- BPaired-samples t-test
16To compute a t statistic you do not actually need any raw data, it can be computed with simply the means, standard deviations and sample sizes.
- ARichtig
- BFalsch
17The standard error of the difference refers to
- AThe variability of groups in the population
- BThe sampling error of the mean
- CThe standard deviation of the sampling distribution of the mean
- DThe standard deviation of a sampling distribution of differences between means.
- EA measure of variability of differences between sample means.
- FA measure of the unsystematic variation within the data.
- GA measure of the systematic variation within the data.
18We divide by the standard error because:
- AIt standardises the average difference between conditions so that we can compare t statistics without having to worry about the scale of measurement used to measure the outcome variable. That is two t-statistics are comparable even if they come from different experiments.
- BIt contrasts the difference between means that we have, against the difference that we could expect to find given how well the samples represent to populations from which they came.
- CIt contrasts the difference between means that we have, against the alpha level and thus provides a measure of the probability that the difference occured by chance.
19T-statistics are cool.
- AA t statistic is simply a ratio of the systematic variation in the experiment to the unsystematic variation.
- BA t statistic is simply a ratio of the systematic variation in the experiment compared to the differences between observed and expected values.
20T statistics are still cool.
- AIf the experiment creates any kind of effect, then we would expect the systematic variation to be greater than the unsystematic variation and thus (at the very least) the T statistic should be greater than 1.
- BIf the experiment creates any kind of effect, then we would expect the unsystematic variation to be greater than the systematic variation and thus (at the very least) the T statistic should be greater than 1.
- CT statistics are always less than 1.
21Which of the following is accurate?
- ASSm (Model Sum of Squares): The proportion of the variance explained by the model.
- BSSm (Model Sum of Squares): equals SSt-SSr
- CSSm (Model Sum of Squares): The difference between the mean line and the regression line for all values of x.
- DSSr (Residual Sum of Squares): The proportion of variance not accounted for by the model.
- ESSr (Residual Sum of Squares): The sum of all deviations from the regression line squared.
- FSSr (Residual Sum of Squares): The sum of all deviations from the mean squared.
- GSSt (Total Sum of Squares): The sum of all deviations from the mean squared.
- HSSt (Total Sum of Squares): The total variance in the data
- ISSt (Total Sum of Squares): SSr+SSm
- JSSm (Model Sum of Squares): The sum of all deviations from the regression line squared.
22What is OLS?
- AOrdinary Least Squares Regression
- BOrdinary Leveraged Sum of Squares Regression
- COrdinal Least Squares Regression
23OLS predicts the regression line by
- Acalculating the line that will have the lowest residual sum of squares.
- Bcalculating the line that will have the lowest model sum of squares.
- Ccalculating the line that will have the lowest total sum of squares.
24In order these values denote:
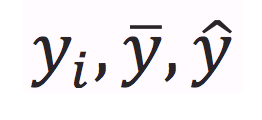
- AAn observed value of y, the mean of y, a predicted or estimated value of y
- BThe mean value of y, a predicted or estimated value of y, an observed value of y
- CThe mean value of y, an observed value of y, a predicted or estimated value of y
- DA predicted or estimated value of y, the mean value of y, and observed value of y
25In regression R squared is a measure of
- AHow well the regression line fits the observed data.
- BThe proportion of variance explained by the regression line
- CThe correlation between the x values and y values
- DThe proportion of variance explained by the co-variance as scaled by the standard deviation
Informationen
- Beschreibung
- Quiz am Comparing two means, erstellt von Dan Myles am 08/03/2015.
- Autor
- Dan Myles
- Sprache
- English
- Aufrufe
- 32
- Schlagwörter
- Bewertung
- Noch keine Bewertungen Bewerte dieses Quiz