
Mapa mental
DATA PREPROCESSING
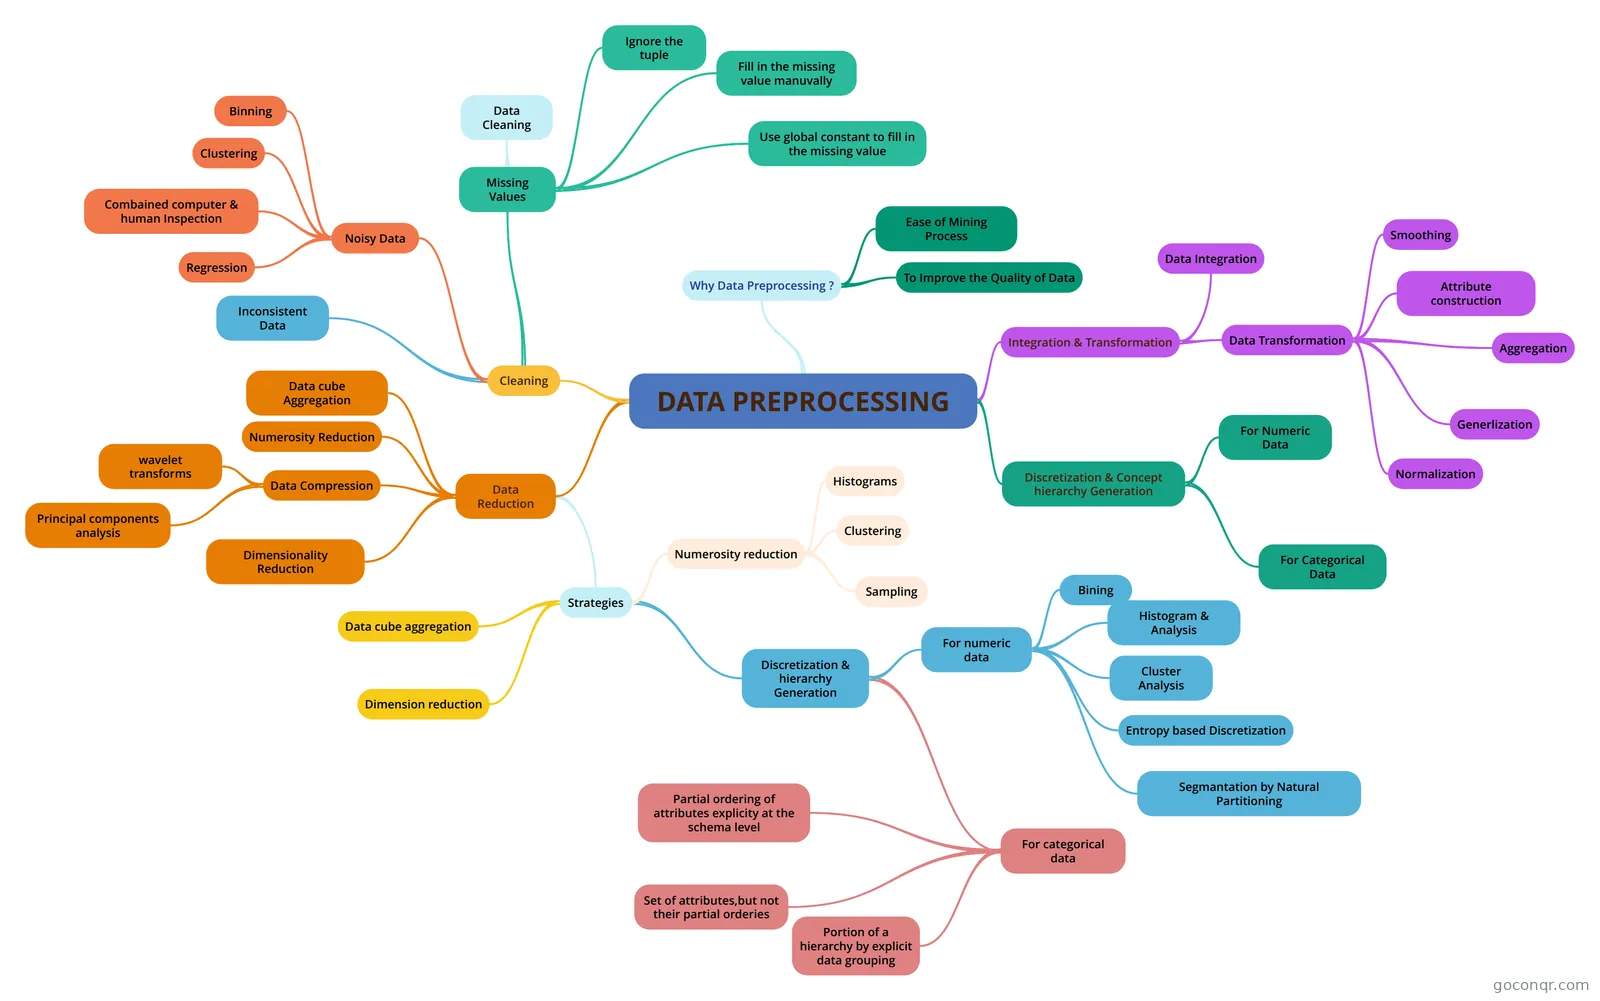
Mind map: data preprocessing
Contenido del mapa
DATA PREPROCESSING
Cleaning
- Missing Values
- Use the attributes mean to fill in the missing value
- Use the attribute mean for all sample belonging to the same class as the given tupe
- Use the most probable values to fill in the missing values
- Data Cleaning
- Fill in missing values & correct inconsistencies in the data
- Ignore the tuple
- Class label is missing & not effective
- Fill in the missing value manuvally
- time consuming & may not be feasible
- Use global constant to fill in the missing value
- replace values & same constant
- Noisy Data
- Binning
- It smooth sorted data value by consulting its neighborhood
- smoothing by bin means smoothing by bin medians smoothing by bin boundaries
- Clustering
- Similar values organized into groups & outliers may be detected by clustering
- Combained computer & human Inspection
- Outlier may be identified through a combination of computer and human inspection
- Regression
- Data can be smoothed by fitting the data to function
- Linear regression
- Multiple linear regression
- Binning
- Inconsistent Data
- Data inconsistencies may be corrected manually using external reference
- Knowledge engineering tools may also be used to detect the violation of known data constrains
- Missing Values
Data Reduction
- It can be applied to obtain a reduced representation of the data set yet closely maintains the integrity of the original data
- Dimensionality Reduction
- Data Compression
- wavelet transforms
- Principal components analysis
- Numerosity Reduction
- Data cube Aggregation
- Strategies
- Data cube aggregation
- Dimension reduction
- step wise forward selection step wise backward elimination combination of forward selection & backward elimination decision tree induction
- Numerosity reduction
- Histograms
- Clustering
- Sampling
- SRSWOR of size n SRSWR of size n Cluster sample Stratisfied sample
- Discretization & hierarchy Generation
- For numeric data
- Bining
- Histogram & Analysis
- Cluster Analysis
- Entropy based Discretization
- Segmantation by Natural Partitioning
- For categorical data
- Portion of a hierarchy by explicit data grouping
- Partial ordering of attributes explicity at the schema level
- Set of attributes,but not their partial orderies
- For numeric data
Discretization & Concept hierarchy Generation
- For Categorical Data
- For Numeric Data
Integration & Transformation
- Data Integration
- It can help improve accuracy & speed of the subsequent mining process
- Reduce and avoid Redundancies & inconsistencies
- Detection and resolution of data value conflicts
- Data Transformation
- Smoothing
- Remove the noise from data
- Attribute construction
- new attributes are constructed and added to help the mining process
- Aggregation
- Aggregation operation are applied to the data
- Generlization
- Primitive data are replaced by high-level concept through the use of concept hierarchies
- Normalization
- Attribute data are scaled with in small specified range such as -1.0 to 1.0 or 0.0 to 1.0
- Smoothing
- Data Integration
Why Data Preprocessing ?
- Ease of Mining Process
- To Improve the Quality of Data
Información
- Descripción
- Mapa Mental sobre DATA PREPROCESSING, creado por sudhibala93 el 18/02/2015.
- Creado por
- sudhibala93
- Visitas
- 269
- Valoración