
Flashcards
Sem título
Flashcards do conjunto (51)
- 1State ElementC = f(A,B,state)
- 2Combinational LogicC = f(A,B)
- 3Clocking methodologydefines when signals can be read and when they
can be written. - 4Edge-trigger Methodology Typical execution:• read contents of some state elements,
• send values through some combinational logic
• write results to one or more state elements - 5Datapath Building Blocks• Instruction memory
• Program counter
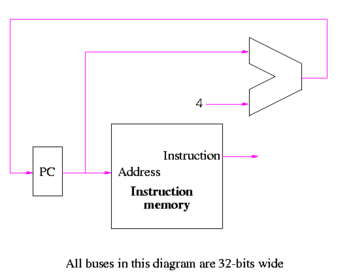
• Arithmetic & logic unit - 6Instruction Fetch
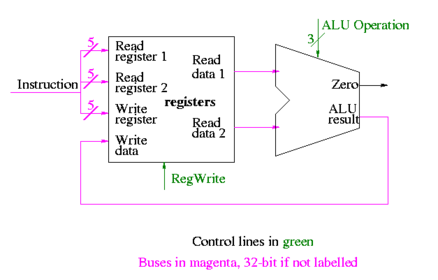
- 7R-type instructions
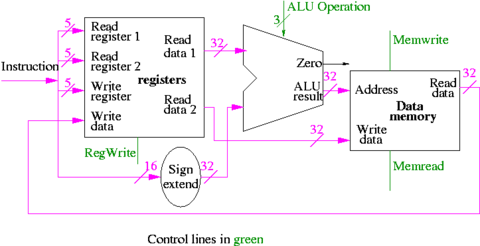
- 8Load and Sore instructions
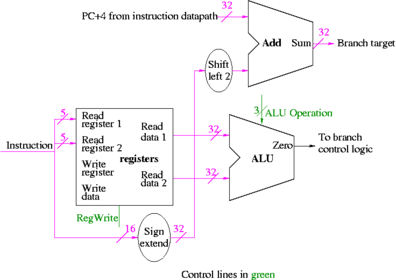
- 9beq instruction
- 10Combining R-type and lw/sw
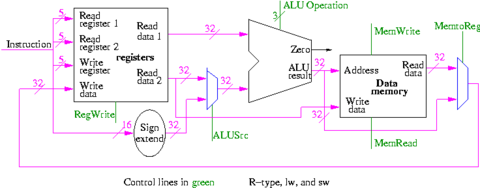
- 11Load and Store InstructionsTransfer address to the memory
• Transfer data from and to the register file
• Sign extension unit for address calculation - 12Branch Instructions• beq needs two ALUs
• One for computing the branch
target address
• The other for comparison
• The base address is PC+4
• Offset field is shift left 2 bits - 13Adding branch logic• Supports now all basic instructions
• Use multiplexers to stitch them together - 14ControlSelecting the operations to perform (ALU, read/write, etc.)
• Controlling the flow of data (multiplexer inputs)
• Information comes from the 32 bits of the instruction - 15Control signal
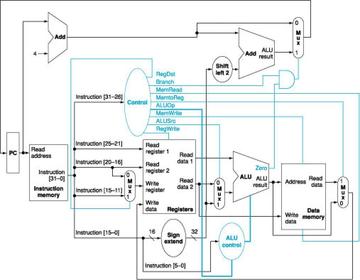
- 16ALU used for• Load/Store: add
• Branch: subtract
• R-type: It depends on funct field - 17full ALU
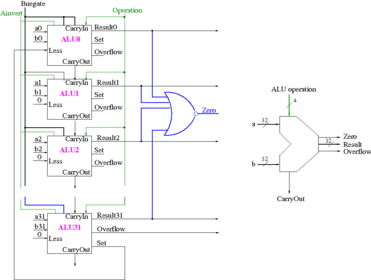
- 18ALU control input 000and
- 19ALU control input 001or
- 20ALU control input 010Add
- 21ALU control input 110Subtract
- 22ALU control input 111slt
- 23speedupn*k / (n+k-1)
- 24The Five Stages of MIPS PipelineIF: Instruction Fetch
ID: Registers Read and Instruction Decode
EXE: Execute operation or calculate address
• MEM: Read the data from the Data Memory
WR: Write the data back to the register file - 25Idea for a Pipelined Datapath
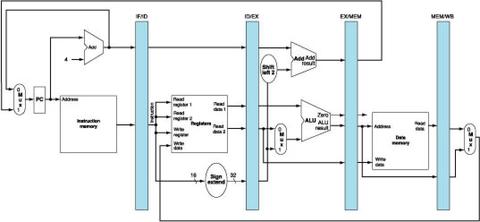
- 26CPU time=IC * CPI * CT
- 27ET =IC*CPI*CT
- 28Multiple ExceptionsPipelining overlaps multiple instructions
Simple approach: deal with exception from earliest instruction
In complex pipelines - 29Final Pipelined Datapath
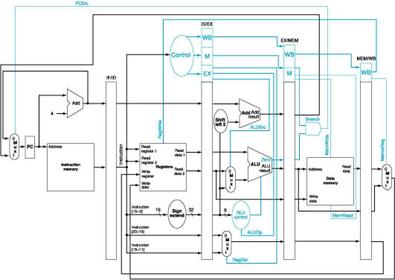
- 30To increase (Instruction-Level Parallelism) ILPDeeper pipeline
• Less work per stage -> shorter clock cycle
Multiple issue
• Replicate pipeline stages multiple pipelines
• Start multiple instructions per clock cyc - 31Scheduling Static Multiple IssueCompiler must remove some/all hazards
• Reorder instructions into issue packets
• No dependencies within a packet - 32MIPS with Static Dual Issue• Two-issue packets
• One ALU/branch instruction
• One load/store instruction - 33Hazards in the Dual-Issue MIPSMore instructions executing in parallel
EX data hazard
Load-use hazard
More aggressive scheduling required - 34Dynamic Pipeline SchedulingAllow the CPU to execute instructions out of order
to avoid stalls
• But commit result to registers in order - 35Power EfficiencyComplexity of dynamic scheduling and speculations
requires power
• Multiple simpler cores may be better - 36Memory HierarchyUser wants large and fast
memory!
By taking advantage of the
principle of locality:
• Present the user with as much
memory as is available in the
cheapest technology.
• Provide access at the speed
offered by the fastest technology - 37Principle of LocalityPrograms access a small proportion of their address space at any time
Temporal locality
Spatial locality - 38Taking Advantage of LocalityMemory hierarchy
Store everything on disk
Copy recently accessed (and nearby) items from disk
to smaller DRAM memory
Copy more recently accessed (and nearby) items
from DRAM to smaller SRAM memory - 39Cache Misses• Stall the CPU pipeline
• Fetch block from next level of hierarchy
• Instruction cache miss
• Data cache miss - 40Three Cs of cache missesCompulsory misses
Capacity misses
Conflict misses - 41Compulsory misses:caused by first access to a block
that is never in the cache - 42Capacity misses:caused when the cache cannot
contain all blocks needed during execution of a
program - 43Conflict missescaused when multiple blocks compete
for the same location in the cache, which can be very
bad in a direct-mapped cache. - 44Decreasing miss ratio with associativityDirect mapped cache
Fully associative cache - 45Direct mapped cache• Every memory block goes exactly to one block in the cache
• Easy to find
• Cache Index = (Block Addr.) % (#of cache blocks)
• Use it as the index to the referenced word - 46Fully associative cacheA memory block can go in any block of the cache
• Lower miss rate
Difficult to find
• Longer hit time
Search all tags whether the word is the requested one - 47Cache Performance CPI =BCPI + MCPI
- 48Cache Performance MCPI =accesses/instruction * miss rate * miss penalty
- 49BCPI =peak CPI + PSPI + BSPI
- 50PSPI =pipeline stalls per instruction
- 51BSPI =branch hazard stalls per instruction
Informações
- Descrição
- FlashCards sobre Sem título, criado por wward246 em 10-05-2015.
- Criado por
- wward246
- Visualizações
- 0
- Avaliação