
Quiz
Unstructured Data Analytics Quizes
Este quiz tem tipos de pergunta que abrem no player de sempre.
Perguntas do quiz (60)
1Which of these word patterns will the regular expression "^[aeiou]{2}" match?
- A"lychee" "physalis" "strawberry"
- B"bread" "wallet" "drum"
- C"apple" "physalis" "egg"
- D"eiffel" "oath" "eight"
2What is the difference between stemming and lemmatization?
- ANothing. They mean the same thing.
- BStemming is a follow-on process to lemmatization that takes part-of-speech into consideration.
- CStemming is a subset of the lemmatization process.
- DLemmatization is an advanced form of stemming that takes context into consideration.
3Which of the following text-preprocessing steps can the unnest_tokens() function do?
- Astemming
- Bremoving stop words
- Cspelling normalization
- Dsentence boundary detection
4An anti-join between table 1 and table 2 will return ___________.
- Aall records in table 1 that don't match the records in table 2
- Ball records in both table 1 and table 2
- Call records in table 1 that match the records in table 2
- Dall records in table 1 that either match or don't match the records in table 2
5The syntax for regular expressions can be grouped into four major categories. Which of these is not one of them?
- AOperators
- BEscape sequences
- CAnchors
- DMetacharacters
6JSON stands for Javascript Object [blank_start]Notation[blank_end].
- ANotation
7Data with a self-describing structure and which doesn't follow a pre-defined form can be classified as ______________ data.
- Asemi-structured
- Bpartially structured
- Cstructured
- Dunstructured
8XML (Extensible Markup Language) is a human and machine readable markup language which is similar to and uses the same set of tags as HTML.
- AVerdadeiro
- BFalso
9The special characters used in regular expressions to describe patterns in text are known as _____________.
- Aubercharacters
- Bmetacharacters
- Cregex
- DXML
10Which of these word patterns will the regular expression "^w.*t$" match?
- A"tight" "want" "west"
- B"wait" "want" "west"
- C"wait" "wail" "wand"
- D"wait" "mast" "west"
11Which of these best describes the document frequency of a term?
- AThe proportion of terms that appear in a document.
- BThe ratio of documents in which a term occurs.
- CThe number of times that a term appears in a document.
- DThe frequency of terms in a document corpus.
12The bag-of-words assumption for the vector-space model stipulates that words should be listed in the same order in which they appear in the original document.
- AVerdadeiro
- BFalso
13The process of breaking up text into individual lexical units is known as ____________.
- Aunnesting
- Btokenization
- Clexical generation
- Dn-gram generation
14In the vector space model, rows represent documents and columns represent ____________.
- Atokens
- Bspace
- Clexicons
- Dcounts
15You are presented with a regex string pattern as follows "^\\\\". Which of these best describes the pattern?
- AWords that begin with a double backslash ("\\").
- BWords that have a double backslash ("\\").
- CWords that begin with a single backslash ("\").
- DWords that end with a single backslash ("\").
16The text analytics approach that is focused on the construction of structured data, such as names, places and organizations, from unstructured data is known as _________________.
- Asearch and information retrieval
- Binformation extraction
- Cconcept extraction
- Dsyntactic parsing
17A token can either be an n-gram, sentence or paragraph.
- AVerdadeiro
- BFalso
18An n-gram is a contiguous sequence of n words within text. Which of these is another name for an n-gram with n set to 1?
- Aa single gram
- Ba solo gram
- Ca word
- Da phrase
19The text analytics approach that is focused on assigning labels to unlabeled documents using a model learned from documents with known labels is called ___________________.
- Adocument segmentation
- Bdocument clustering
- Csentiment analysis
- Ddocument classification
20Words that occur a lot within a document, and also occur in a lot of documents within the corpus, will have high tf-idf.
- AVerdadeiro
- BFalso
21The LDA() function in the R topicmodels package supports two topic modeling methods. One is "Gibbs Sampling." What is the other called?
- AVEM
- BpLSA
- CTextRank
- DLSI
22The argument syntax for the LDA() function in the topicmodels R package is is as follows: LDA(dtm, k, method, control). What does the "k" stand for?
- AThe number of topics.
- BThe number of documents.
- CThe random number seed.
- DThe alpha input vector.
23In sentence-level sentiment analysis, intensifiers, downtoners, adversative conjunctions, and negators are collectively known as valence shifters.
- AVerdadeiro
- BFalso
24Sentiment analysis is not impacted by the cultural and demographic differences between authors.
- AVerdadeiro
- BFalso
25Sentiment analysis is not only concerned with opinions about an entity, it is also concerned with opinions about the attributes of the entity. What are these attributes called?
- Aprospects
- Baspects
- Ctargets
- Dholders
26In topic modeling, there are several approaches to finding the right number of topics. Which of these is not one of them?
- AGibbs Sampling
- BTopic Coherence
- CLog-likelihood
- DPerplexity
27Given the sentence, "I don't like taking the SouthShore, but I love coming to Chicago." What type of valence shifter is the word "but"?
- ADe-amplifier
- BAmplifier
- CNegator
- DAdversative Conjunction
28Which of these is not one of the sentiment lexicons available through the "tidytext" package?
- ALoughran
- BBing
- CAFINN
- DPlutchik
29Which of these is not an assumption that the LDA model makes?
- AEvery topic is a mixture of words.
- BDocuments with similar topics will use similar groups of words.
- CEvery document is a mixture of topics.
- DEvery word is a mixture of documents.
30Dirichlet distributions are sampled over a probability simplex. A probability simplex is a set of numbers that add up to 1.
- AVerdadeiro
- BFalso
31A collection of words that occur together is called a
- Atopic
- Bdocument
- Csentiment
- Dword
32Which of these is not a common technique used for topic modeling?
- ALatent Dirichlet Allocation
- BProbabilistic Latent Semantic Analysis
- CLatent Semantic Indexing
- DLatent Syntactic Parsing
33Given the sentence: "I don't like taking the SouthShore but I love coming to Chicago." What type of valence shifter is the word "don't"?
- AAdversative Conjunction
- BAmplifier
- CNegator
- DDe-amplifier
34Topic models are mixture models. This implies that a particular document can be assigned to more than one topic. In clustering, what kind of clustering approach would this be called?
- ASoft clustering
- BMixture clustering
- CExclusive clustering
- DComplete clustering
35The tidy text word-level sentiment analysis approach takes into consideration qualifiers, such as "pretty good", "not bad", etc.
- AVerdadeiro
- BFalso
36The valence of an emotion, that is, the degree to which it is positive or negative, is also known as the _________ of the emotion.
- Alexicon
- Bamplifier
- Cpolarity
- Dframework
37The LDA() function from the topicmodels package returns two matrices. One is called gamma and the other is called beta. What does beta represent?
- AThe prevalence of topics in documents.
- BThe probability of words belonging to documents.
- CThe probability of words belonging to topics.
- DThe prevalence of words in documents.
38All four of the tidy text sentiment lexicons are based on unigrams.
- AVerdadeiro
- BFalso
39Unlike the tidytext package, the sentimentr package does not allow the use of custom sentiment lexicons.
- AVerdadeiro
- BFalso
40Dirichlet distributions are parameterized by a vector (alpha). As alpha __________ the distribution becomes more spread out and moves towards the center. As alpha ____________ the distribution moves towards the poles.
- Adecreases, increases
- Bbecomes positive, becomes negative
- Cincreases, decreases
- Dbecomes negative, becomes positive
41Because events cannot simultaneously happen and not happen, events are mutually exclusive with their complements.
- AVerdadeiro
- BFalso
42Given two independent events A and B, with P(A) = 0.5 and P(B) = 0.4. The joint probability P(A ⋂ B) =
[blank_start]0.2[blank_end].- A0.2
43For dependent events A and B, the probability of event A, given that event B occurred is described with the conditional probability P(A | B) = P(A ⋂ B) / P(B). This is known as the ______________.
- AConditional Probability Theorem
- BBayes Theorem
- CBarnes Theorem
- DTesla Theorem
44In the conditional probability formula above, P(spam | free) is known as the _________.
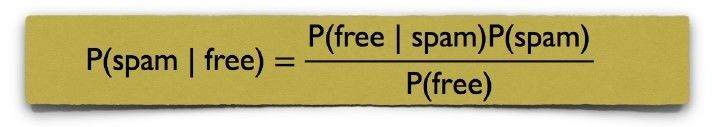
- Aposterior probability
- Bmarginal likelihood
- Clikelihood
- Dprior probability
45The Naive Bayes algorithm is premised on the “naive” assumption that all features in the dataset are ________ important and __________.
- Adependably, equal
- Bunequal, undependable
- Cequally, dependent
- Dequally, independent
46"Events are independent so long as they are conditioned on the same class value." This is known as __________________.
- Avalue independence
- Bclass-conditional independence
- Cbayesian independence
- Dcross-conditional independence
47With Naive Bayes, the method of adding a pseudo-count to the number of observed and unobserved cases in order to change the expected probability so as to avoid zero-frequency problems is known as _____________.
- APseudo-smoothing
- BLaplace smoothing
- CBayesian smoothing
- DNaive smoothing
48One of the weaknesses of the Naive Bayes algorithm is that it assumes that features are equally important and independent.
- AVerdadeiro
- BFalso
49Similar to logistic regression, Naive Bayes models are ____________ models.
- Aparametric
- Bmetric
- Cmatrix
- Dnon-parametric
50Which of these is not a strength of the Naive Bayes algorithm?
- AIt is not affected by correlated features.
- BIt is useful for both continuous and discrete features.
- CIt works well with both little or large training data.
- DIt works well with noisy and missing data.
51The hyperplane that creates the largest separation between classes is known as the ________________ hyperplane.
- Asupport vector
- Bkernel
- Cmaximum margin
- Dbest fit
52In the support vector machine approach, each class must have at least one support vector.
- AVerdadeiro
- BFalso
53Which of these is not an approach used in SVMs when dealing with non-linearly separable data?
- AUsing a technique known as soft-margin classification.
- BIntroducing a slack variable and allowing some examples to be misclassified.
- CUsing a kernel transformation.
- DNormalizing the data so it fits within the margin of the hyperplane.
54Which of these is not a commonly used kernel transformation?
- AHyperplane Kernel
- BSigmoid Kernel
- CGaussian Kernel
- DLinear Kernel
55Which of these is not a weakness of support vector machines?
- AThey can only be used for classification problems.
- BThe choice of kernel has a significant impact on the performance of the model.
- CIt's a black box approach.
- DThe results typically do not have a direct probabilistic interpretation.
56Support vector machines are not good against high-dimensional datasets.
- AVerdadeiro
- BFalso
57With support vector machines, the process of transforming data to a higher dimensional space in order to make it linearly separable is known as ______________.
- AThe kernel trick.
- BHigh-dimensional classification.
- CThe support vector transformation.
- DThe maximum margin hyperplane.
58Which of these is not a strength of support vector machines?
- AThey are not overly influenced by noisy data.
- BThey are useful for both classification and regression.
- CBecause of the kernel transformation, they are very fast to train.
- DThey are not prone to overfitting.
59When classifiying data with support vector machines, only a subset of the data is used in the process. Why is this?
- AThe kernel transformation gets rid of most of the data.
- BOnly the support vectors are used in the classification process.
- CThe kernel trick reduces the dimensionality of the data.
- DThe sampling approach is highly reductive.
60Both Naive Bayes and Support Vector Machines are unsupervised machine learning algorithms.
- AVerdadeiro
- BFalso
Informações
- Descrição
- Final Machine Learning Quiz sobre Unstructured Data Analytics Quizes, criado por Kelly Cronin em 04-10-2019.
- Autor
- Kelly Cronin
- Idioma
- English
- Visualizações
- 176
- Etiquetas
- Avaliação
- Ainda sem avaliações Avalie este quiz