
Quiz
Data Architecture test
Crie uma conta grátis para terminar este quiz
Salve seu progresso e veja sua nota final.
Já tem uma conta? Inicie sessão
Perguntas do quiz (25)
1What's the right data timing classification to keep in mind when choosing a data ingestion tool?
- ABatch and real time
- BMacro-batch, micro-batch, near real-time and real-time
- CSlow, fast, and speed of light
- DHistorical, real-time, and predicted data
2Apache Kafka stores data in..
- AConsumers
- BProducers
- CSchemas
- DTopics
3If you plan to reuse a Dataframe can you do to avoid recomputing
- AImprove()
- Bcollect()
- Cperformance()
- Dcache()
4What of the following is not a core data source in Spark?
- ACSV
- BJSON
- CSQL
- DCassandra
5Select the code block which counts distinct number of Quantity for each invoiceNo in the Dataframe df.
- Adf.groupBy(InvoiceNo).agg(expr(count(Quantity)))
- Bdf.groupBy("InvoiceNo").agg(expr("countDistinct(Quantity)"))
- Cdf.groupBy(InvoiceNo).agg(expr("count(Quantity))")
- Ddf.groupBy("InvoiceNo").agg(expr(count(Quantity)))
6Does Hadoop have limitations compared to Spark?
- AYes, because it's older and the code runs slower than Spark that is implemented in assembler
- BYes; Hadoop is rigid, HDFS is hit constantly and it needs frameworks to enable different processing paradigms
- CNo, although it's more limited when is deployed on the cloud
- DNo, although is actually more powerful and easy to use than Spark
7Generally speaking, what's the value chain of data as it's seen in Big Data projects?
- AData reading, data changing, data sharing, and data removing
- BData serving, Data processing, Data storage, and Data ingestion
- CData ingestion, Data storage, Data processing, and Data serving
- DData ingestion and Data serving
8What is a UDF?
- AA Unified Defined Function
- BA User DataFrame Federation
- CA User Dataframe Function
- DA User Defined Function
9What is NOT Apache Spark?
- AIt's shipped with a set of libraries for parallel data processing on computer clusters
- BIt's a database used in almost every single Big Data project
- CIt's part of the Hadoop ecosystem
- DOpen source Unified Computing Engine
10Is the cluster manager part of the Architecture of a Spark Application?
- ANo, only the Executor processors are
- BYes, additionally to the Driver process and Executor processors, the Cluster Manager is part of the architecture
- CNo, only the Driver process and Executor processors are
- DNo, only the Driver process is
11In which use cases a tool like NiFi is a good fit?
- ABusiness Analytics and CyberSecurity
- BDashboarding and reporting
- CData ingestion for clickstream, social media and Change Data Capture
- DBatch ETL workloads such as mainframe offloading
12What does lazily evaluation mean?
- ALazily evaluation is a Hadoop thing and it doesn't apply in Spark as the professor explained in class
- BThe transformation are only computed from 9 am to 5 pm from Monday to Friday
- CThe transformation are only computed when the cell in Jupyter is executed
- DThe transformation are only computed when an action requires a result to be returned
13Which of the following statements about Data Lakes are true?
- ASupport any type of data
- BSupport schema or read
- CSupport only structured data
- DSupport schema on write
14What does this code do?
flightsDF.select("Year", "Month", "DayofMonth", "DayofWeek").summary().collect()- A#1 create DataFrame, #2 summarization of columns & #3 bring all the rows to the driver process
- B# 1 display results & #2 store all in S3
- C#1 column projection, #2 multilevel aggregation of projected columns & #3 bring all the rows to the driver process
- D#1 column projection, #2 summarization of columns & #3 bring all the rows to the driver process
15Which file formats are best suited for Big Data processing?
- APARQUET
- BDELTA
- CJSON
- DCSV
16Consider the following DataFrame:
simpleData = (("James", "Sales", 3000), \
("Michael", "Sales", 4600),\
("Robert", "Sales", 4100),\
("Maria", "Finance",3000),\
(James", "Sales", 3000),\
("Scott", "Finance", 3300),\
(]en", "Finance", 3900), \
(Jeff", "Marketing", 3000),\
("Kumar", "Marketing*, 2000), \
("Saif", "Sales", 4100) )
columns= ["ame", "department", "salary")
df= spark.createDataFrame(data = simpleData, schema = columns)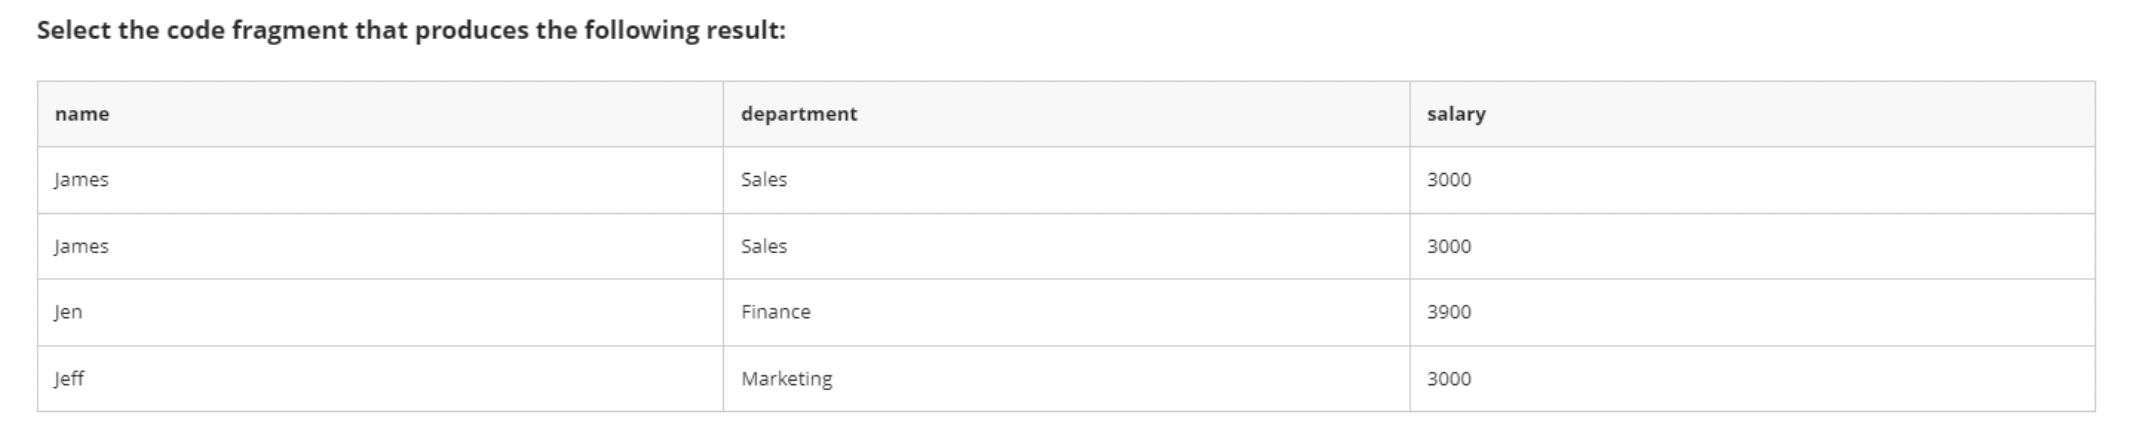
- AsimpleData = (("James", "Sales", 3000), \
("Michael", "Sales", 4600),\
("Robert", "Sales", 4100),\
("Maria", "Finance",3000),\
(James", "Sales", 3000),\
("Scott", "Finance", 3300),\
(]en", "Finance", 3900), \
(Jeff", "Marketing", 3000),\
("Kumar", "Marketing*, 2000), \
("Saif", "Sales", 4100) )
columns= ["ame", "department", "salary")
df= spark.createDataFrame(data = simpleData, schema = columns) - Bdf.where("salary >= 3000")
- Cdf.where("name like 'J%")
- Ddf.where("department in ("Sales", "Finance"))
- AsimpleData = (("James", "Sales", 3000), \
17What's the other name of the High-level API?
- AStructured API
- BRDD API
- CHadoop API
- DSchema API
18What's Hadoop?
- AIt's an algorithm to process data with MapReduce software
- BAn open-source framework for storing and processing huge amounts of data that is fault-tolerant and scalable
- CAn application to process data in laptops
- DFramework to store semi-structured and non-structure data in HDFS
19Select two features that best describe HDFS
- AFiles are split into chunks called blocks and stores distributedly
- BDesigned to store very small files
- CLow latency access
- DDesigned to store relative big files
20What does Data Structures are immutable mean?
- ADataFrames don't change because the transformations are lazy and don't want to change them
- BAny transformation applied on a DataFrame returns a new Data Frame
- CDataFrames never change along the transformations, therefore Spark is useless
- DDataFrames only change when you apply a mutable transformation, therefore you should avoid immutable transformations
21Does this code move data from the source?
df= df.where(co)(ArrDelay-)!-"NA'))
_withColumn(DelaySeverity*„when(col"ArrDelay-)<=0."1.nodelay-»
„when((co)(-ArrDelay-p0)&(co)(ArrDelay)<-15).-2.acceptable-)
.when/(colArrDelay*p15)&(co)(*ArrDelay-)<-30).-3.annoying*)
‚when((co)(ArrDelay*)>30)&(col("ArrDelay*)<-60).*4.impactul)Lotherwise('S.unacceptable*))- ATRUE
- BFALSE
22Based on data dimensions select two different data processing approaches?
- ABatch processing for a large amount of data, high latency and data at rest
- BStream processing for a small amount of data, low latency, and data in motion
- CIngestion processing for small and large amounts of data
- DQuantum processing for streaming data
23Given an external table my_table. If you run the code block down below:
spark.sql("DROP TABLE IF EXISTS my_table")- ANo data will be removed but you won't be able to refer to this data by the table name
- BThis is not a valid code block
- CAlso data will be removed
- DSpark will remove the table and also the associated views
24What happens when you drop a managed table?
- ABoth table definition and data are deleted
- BNothing
- CTable data is deleted from the file system
- DThe table definition is deleted from metastore
25Select V's of data
- AVelocity
- BVisualization
- CVolumen
- DVariability
Informações
- Descrição
- B Data Architecture Quiz sobre Data Architecture test, criado por Angel Intriago em 14-12-2021.
- Autor
- Angel Intriago
- Idioma
- English
- Visualizações
- 1
- Etiquetas
- Avaliação
- Ainda sem avaliações Avalie este quiz