
Quiz
Machine Learning Final Exam Prep
This quiz has question types that open in the usual player.
Questions in this quiz (80)
1Missing values can have meaning.
- ATrue
- BFalse
2A dataset with two class values that is significantly skewed (more than 90%) towards one of those class values is known as ___________ dataset.
- Aan imbalanced
- Ban inverted
- Ca bimodal
- Da skewed
3The method of imputation that fills in missing values using similar instances from the same dataset is known as _________ imputation.
- AHot-deck
- BWarm-deck
- CSame-deck
- DCold-deck
4Which of these data transformation approaches results in a data set with the mean located at zero.
- Adecimal scaling
- Bmin-max normalization
- Cz-score normalization
- Dmean-max normalization
5Error due to ______ are errors made as a result of choosing a learning algorithm that is not well suited for the data or problem.
- ABias
- BVariance
- CNoise
- DSampling
6In class we discussed 6 stages in the "Analytic Process". Which of these is not one of those stages?
- AData Summarization
- BData Exploration
- CValidation and Interpretation
- DModeling
7According to the formal definition of machine learning, "A computer program is said to learn from _______ with respect to some class of _______ and performance measure P, if its performance at ________, as measured by P, improves with __________".
- Aexposure (E), tasks (T), tasks (T), exposure (E)
- Bexperience (E), tasks (T), tasks (T), experience (E)
- Ctasks (T), experience (E), tasks (T), experience (E)
- Dexperience (E), test (T), test (T), experience (E)
8As the complexity of a model increases, bias decreases but variance increases.
- ATrue
- BFalse
9Which of these types of visualizations is best to use to explore the correlation between two continuous features?
- AScatter plot
- BPie chart
- CHistogram
- DSankey diagram
10Which of these terms is used to describe the degree to which data exists for each feature of all observations.
- ADensity
- BResolution
- CCoarseness
- DDimensionality
11Which of these is a regression problem?
- AHow can I group supermarket products using purchase frequency?
- BCan I determine a person's income based on their age and type of job?
- CIdentify similarities in shopping patterns between customers of a department store.
- DWhich states have the highest infant mortality rate?
12The goal of unsupervised learning is to predict future outcomes based on prior experience.
- ATrue
- BFalse
13The primary difference between classification and regression is that classification is used to predict _____ values, while regression is used to predict ______ values.
- Anominal, binomial
- Bdiscrete, continuous
- Cordinal, nominal
- Dcontinuous, discrete
14Error due to ________ are errors made as a result of not providing the learning algorithm with the right amount or type of training data.
- ABias
- BSampling
- CRandomness
- DVariance
15Color, shape, angle, and number of edges are examples of nominal (or discrete) features
- ATrue
- BFalse
16The random sampling method that tries to maintain the same class distribution as the original dataset is known as ___________.
- ASystematic random sampling
- BStratified random sampling
- CPurposeful random sampling
- DRandom sampling with replacement
17Clustering is a type of unsupervised learning.
- ATrue
- BFalse
18As part of the data transformation process, we sometimes have to discretize our data or create dummy variables. Which of these is a reason why we would need to do this?
- AThis is an important step in balancing imbalanced datasets.
- BIt helps when trying to fix duplicate data.
- CThis is an approach to normalize our data set.
- DSome algorithms only work with either continuous or discrete variables.
19The _______ of a dataset represents the number of features in the dataset.
- ACoarseness
- BDensity
- CResolution
- DDimensionality
20One of the strengths of association rules is that they are easy to understand.
- ATrue
- BFalse
21Which of these is a method employed by the k-means algorithm to mitigate the effects of the random initialization trap?
- Ak-Means ++
- Bk-Medoids
- CCentroid placement
- DRandom Initialization escape
22The confidence of an association rule is the __________ of the rule.
- Apredictive power
- Bsupport strength
- Ccomplete coverage
- Dlikelihood level
23Good clustering will produce clusters with _____ inter-class similarity and ______ intra-class similarity.
- Alow, low
- Bhigh, high
- Chigh, low
- Dlow, high
24Clustering results in labels against previously unlabeled data, that is why it is sometimes referred to as unsupervised classification.
- ATrue
- BFalse
25As we discussed in class, the elbow method makes use of the Within Cluster Sum of Squares (WCSS) metric to suggest the appropriate value for "k". If we keep increasing the value for "k", what will happen to the value for WCSS?
- AThe value for WCSS will grow infinitely.
- BThe value for WCSS will eventually become negative.
- CThe value for WCSS will tend towards 1.
- DThe value for WCSS will tend towards 0.
26Association rules imply causality in that they explain why item B is bought whenever item A is bought.
- ATrue
- BFalse
27What is the support of the itemset {beer, coke} in the dataset above?
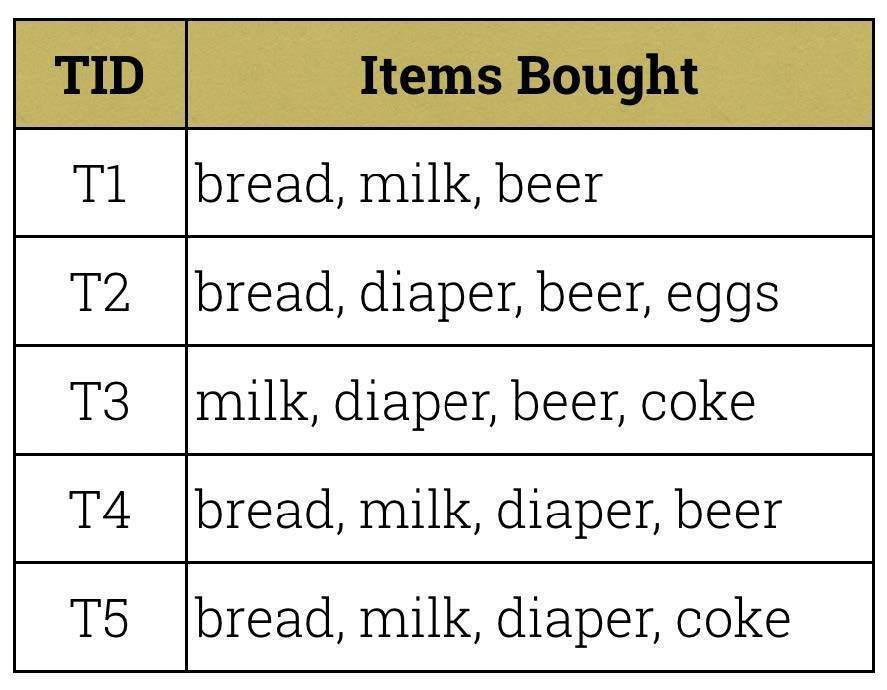
- A0.2
- B1
- C4
- D0.4
28In Association rules, a collection of one or more items is known as ______________.
- Aa set of items
- Ban itemset
- Ca ruleset
- Da set of rules
29k-Means clustering only works with numeric data.
- ATrue
- BFalse
30Clustering results in labels against previously unlabeled data, that is why it is sometimes referred to as _____________________.
- APredictive partitioning
- BSupervised labeling
- CPredictive labeling
- DUnsupervised classification
31Which of these is NOT a method used in choosing the appropriate value for "k"?
- AGap statistic
- BAnkle Method
- CA priori knowledge
- DElbow Method
32A clustering method in which every object belongs to every cluster with a membership weight that goes between 0 (if it absolutely doesn’t belong to the cluster) and 1(if it absolutely belongs to the cluster) is known as _______ clustering.
- APartitional
- BOverlapping
- CFuzzy
- DHierarchical
33Association rules are great with small data sets.
- ATrue
- BFalse
34K-Means clustering is useful in creating non-spherical clusters.
- ATrue
- BFalse
35The Amelia package in R is useful for dealing with ___________ data.
- AAggregate
- BImbalance
- CMissing
- DSkewed
36The increased likelihood that a rule occurs in a dataset relative to its typical rate of occurrence is known as __________.
- ASupport
- BConfidence
- CLift
- DCount
37Which of these is a distance measure employed by k-means clustering? (Select two.)
- AEuclidean distance
- BCluster distance
- CCentroid distance
- DManhattan distance
38One of the ways to reduce the computational complexity of frequent itemset generation is by the use of ____________.
- Athe FP-Growth algorithm
- Bthe a priori algorithm
- Cthe post-pruning algorithm
- Dthe association rules algorithm
39The anti-monotone property of support states that the support of an itemset is _________ than that of its subsets. (Select two.)
- AAlways more
- BSometimes Less
- CAlways Less
- DSometimes More
40The K in k-NN has to do with ______________.
- AThe number of labeled observations to compare with the unlabeled observation.
- BThe size of the training set.
- CThe number of clusters that need to be created to properly label the unlabeled observation.
- DThe number of unlabeled observations with the letter K.
41A common type of distance measure used in k-NN is the _________ distance.
- AEuclidean
- BBayesan
- CNearest
- DEucalyptus
42Which of these is not a common approach to choosing the right value for K?
- ATest different k values against a variety of test datasets and chose the one that performs best.
- BUse weighted voting where the closest neighbors have larger weights.
- CThe square root of the number of training examples.
- DHalf the number of training examples.
43Before we use k-NN, what can we do if we have significant variance in the range of values for our features?
- AWe normalize the data.
- BWe create dummy variables.
- CWe convert them all to 0s and 1s.
- DWe exclude the outlier features.
44Features with a large number of distinct values will have lower intrinsic value than features with a small number of distinct values.
- ATrue
- BFalse
45For decision trees, entropy is a quantification of the level of ___________ within a set of class values. (Select two.)
- Adisorder
- Bnodes
- Cstatic
- Drandomness
46For decision trees, the process of remediating the size of a tree in order for it to generalize better is known as ___________.
- Apruning
- Bplaning
- Cpartitioning
- Dpurging
47Regression establishes causation between the independent variables and the dependent variable.
- ATrue
- BFalse
48In order to choose the next feature to split on, a decision tree learner calculates the Information Gain for features A, B, C and D as 0.022, 0.609, 0.841 and 0.145 respectively. Which feature will it next choose to split on?
- AFeature C
- BFeature B
- CFeature D
- DFeature A
49Lazy learners such as k-Nearest Neighbor are also known as _______ learners. (Select two.)
- Arote learners
- Binstance-based learners
- Cnon-learners
- Djust-in-time learners
50The recursive process used in logistic regression to minimize the cost function during maximum likelihood estimation is known as _________.
- Alogit function
- Bsum of squared errors
- Clog odds
- Dgradient descent
51In binomial logistic regression, the best cut-off point is always at 0.5.
- ATrue
- BFalse
52The link function used for binomial logistic regression is called the _____________.
- Alogos function
- Binverse function
- Clogarithmic funnction
- Dlogit function
53The logistic function is a sigmoid function that assumes values from [blank_start]0[blank_end] to [blank_start]1[blank_end] . Note: Your answer must be numeric.
- A0
- B1
54Entropy is highest when the split is 50-50. However, as one class dominates the other, entropy reduces to zero.
- ATrue
- BFalse
55Decision tree learners typically output the resulting tree structure in human-readable format. This makes them well suited for applications that require transparency for legal reasons or for knowledge transfer.
- ATrue
- BFalse
56A small K makes a model susceptible to noise and/or outliers and can lead to ___________.
- Arandomness
- Boverfitting
- Cunderfitting
- Derror
57Rather than the sum of squares used in linear regression, in logistic regression, the coefficients are estimated using a technique called _______________.
- AMaximum Logistic Error
- BMean Estimation of Means
- CGradient Boosting
- DMaximum Likelihood Estimation
58k-NN is an example of a ________ model.
- Anon-parametric
- Bmetric
- Cparametric
- Dunsupervised
59Given a set of candidate models from the same data, the model with the highest AIC is usually the “preferred” model.
- ATrue
- BFalse
60The AUC for a perfect classifier is [blank_start]1[blank_end].
- A1
61The error generated by a classifier during the training stage is know as the ____________ error.
- Aholdout
- Bresubstitution
- Cvalidation
- Dboostrap
62One of the major disadvantages of the leave-one-out cross-validation approach is that it _______________.
- Auses too much data
- Bis not a good predictor of future performance
- Cviolates the holdout principle
- Dis computationally expensive
63One of the disadvantages of the random cross-validation approach is that some instances may not be used and others may be used more than once.
- ATrue
- BFalse
64The functions that govern how disagreements among the predictions of ensemble models are reconciled are known as _________ functions.
- Astacking
- Bsigmoid
- Callocation
- Dcombination
65Classification algorithms usually have parameters that need to be set before the learning process begins. These parameters are known as _____________.
- Aparametric parameters
- Btuning grids
- Chyperparameters
- Dsupervised parameters
66Occam's Razor states that when presented with competing hypothetical answers to a problem, one should select the answer that makes the most assumptions.
- ATrue
- BFalse
67One of the weaknesses of a Random Forest model is that unlike a decision tree, the model is not easily interpretable.
- ATrue
- BFalse
68The meta-learning approach that utilizes the principle of creating a varied team of experts is known as an ________.
- Ameta-learner
- Bensemble
- Cbagged learner
- Dassemble
69The AUC for a classifier with no predictive value is [blank_start]0.5[blank_end].
- A0.5
70One of the limitations to using the F-score is that it assumes that ________________________.
- Aequal weight should be given to both precision and recall
- Bthe harmonic mean of precision and recall is zero
- Crecall is always more important than precision
- Dprecision is always more important than recall
71The recall of a model is a measure of the completeness of the results of its predictions. This measure has the same value as the ____________ of the model.
- Akappa
- Bprecision
- Csensitivity
- Dspecificity
72The AUC metric and ROC curve can be used interchangeably because if two models have the same or identical AUC values, they will always have the same ROC curve.
- ATrue
- BFalse
73The kappa statistic is an adjustment of accuracy by accounting for the possibility of a correct prediction by chance alone.
- ATrue
- BFalse
74The technique that sequentially builds strong learners as a linear combination of weak learners is known as __________.
- Aboosting
- Bbootstrap aggregation
- Cbagging
- Dbumming
75The process of conducting a search to identify the optimal combination of hyperparameters to use for the learning process using a choice of evaluation methods and metrics is known as _______________ tuning.
- Aautomatic hyper
- Bmodel settings
- Cautomated parameter
- Dsearch space
76The goal of cross-validation is to _____________ across the iterations.
- Achoose the coolest model
- Bimprove the performance of a model
- Celiminate bad models
- Devaluated future performance
77Which of these is not a problem with the partitioning approach of the holdout method?
- AEach partition may have a larger or smaller proportion of some classes.
- BIt's not always possible to create representative partitions of a data set.
- CSubstantial portions of data must be reserved to test and validate the model.
- DSome samples may have too many or too few difficult cases, easy-to-predict cases, or outliers.
78The sampling approach that creates a training set of equal length as the original data, using sampling with replacement, is known as _______________.
- AStratified sampling
- BEqual length sampling
- CCross-validation
- DBootstrapping
79The ROC curve is a measure of the True Positive Rate against the _________________ of a model.
- ASpecificity
- BTrue Negative Rate
- CFalse Positive Rate
- DFalse Negative Rate
80The attribute or feature that you are trying to predict, which is described by the other features within an instance is known as the __________.
- AInstance
- BDependent variable
- CClass
- DFeature
Information
- Description
- by Kelly
- Author
- Kelly Cronin
- Language
- English
- Views
- 56
- Tags
- Rating
- No ratings yet Rate this quiz