
Quiz
Research Methods IV MCQs
Questions in this quiz (69)
1What is the purpose of a one-way ANOVA (between or within groups)? And how is it different to a t-test?
- AA one-way ANOVA examines the difference between three (or more) levels/groups in one variable, whereas a t-test only examines the difference between two levels/groups in one variable.
- BA one-way ANOVA examines the difference between three (you can't examine more than three) levels/groups in one variable, whereas a t-test only examines the difference between two levels/groups in one variable.
- CA one-way ANOVA examines the difference between four (or more) levels/groups in one variable, whereas a t-test only examines the difference between three levels/groups in one variable.
- DA one-way ANOVA examines the difference between two (or more) levels/groups in one variable, whereas a t-test only examines the difference between three levels/groups in one variable.
2In an one-way independent measures ANOVA, how is the variance split in terms of sums of squares? And which sum of squares tells us how much variance is explained by our hypothesis that the three groups are different?
- AFirst you have the total sum of squares (SST), which is made up of the model sum of squares (SSM) and the residual sum of squares (SSR). SSM tells us how much variance is explained by our hypothesis or model.
- BFirst you have the model sum of squares (SSM), which is made up of the total sum of squares (SST) and the residual sum of squares (SSR). SST tells us how much variance is explained by our hypothesis or model.
- CFirst you have the total sum of squares (SST), which is made up of the model sum of squares (SSM) and the residual sum of squares (SSR). The none of the sum of squares values tell us how much of the variance is explained by our hypothesis.
- DFirst you have the residual sum of squares (SSR), which is made up of the model sum of squares (SSM) and the total sum of squares (SST). SSM tells us how much variance is explained by our hypothesis or model.
3In a repeated measure ANOVA how is the variance split in terms of sums of squares? And which sum of squares value tells us how much variance is explained by our hypothesis - that the group will be different in each condition?
- AFirst, total sum of squares (SST) shows the total variation in the data, this is made of the sum of squares for between participant variation (SSB) and the sum of squares for within participant variation (SSW). In the SSW we can further split the variation into the model sum of squares (SSM) and the residual sum of squares (SSR). SSM tells us how much variance is explained by our hypothesis.
- BFirst, total sum of squares (SST) shows the total variation in the data, this is made of the sum of squares for between participant variation (SSB) and the sum of squares for within participant variation (SSW). SSW tells us how much variance is explained by our hypothesis.
- CFirst, total sum of squares (SST) shows the total variation in the data, this is made of the model sum of squares (SSM) and the residual sum of squares (SSR). SST tells us how much variance is explained by our hypothesis.
- DFirst, total sum of squares (SST) shows the total variation in the data, this is made of the sum of squares for within participant variation (SSW) and the sum of squares for between participant variation (SSB). In the SSB we can further split the variation into the model sum of squares (SSM) and the residual sum of squares (SSR). SSR tells us how much variance is explained by our hypothesis.
4Why can't we use the sum of squares to calculate the F ratio in one-way ANOVA?
- ABecause the sum of squares are influenced by the number of scores summed.
- BThis is a trick question - we do use the sum of squares, its the mean squares we don't use.
- CBecause the sum of squares are influenced by the degrees of freedom but mean squares are not.
- DBecause the sum of squares are influenced by the F ratio.
5In a one-way ANOVA, if our F value is more than 1 - what does this mean?
- AThat our MSM is larger than our MSR. This means that there has been an effect of the variable between the groups/within the group - although we don't know if this is significant.
- BThat our MSR is larger than our MSM. This means that there has been an effect of the variable between the groups/within the group - although we don't know if this is significant.
- CThat our MSM is larger than our MSR. This means that there has not been an effect of the variable between the groups/within the group - although we don't know if this is significant.
- DThat our MSM is larger than our MSR. This means that there has been an effect of the variable between the groups/within the group - and we know that this is significant.
6Which of the following is NOT an assumption of an independent samples ANOVA?
- ASphericity.
- BInterval level data.
- CNormal distribution.
- DHomogeneity of variance.
7Which of the following is NOT an assumption of a repeated measures ANOVA?
- AIndependence of groups.
- BSphericity.
- CInterval level data.
- DNormal distribution.
8One-Way ANOVA: If the assumption of homogeneity is broken - which test should you use instead?
- ABonferroni.
- BTukey.
- CBrown-Forsythe.
- DWelch.
9If your assumption of sphericity is broken - which part of the output should you read instead?
- AMauchly.
- BGreenhouse-Geisser.
- CLower-bound.
- DLevene.
10Can SPSS calculate an effect size for a one-way ANOVA?
- AYes, but only for independent measures - you should calculate it yourself for repeated measures.
- BYes, but only for repeated measures - you should calculate it yourself for independent measures.
- CYes, for both.
- DNo.
11I'm doing a three-way ANOVA with a 3x3x2 design. What does this tell you?
- AThat this experiment has 2 IVs. Two of them have 3 levels.
- BThat this experiment has 3 IVs. Three of them have 3 levels.
- CThat this experiment has 3 levels. Two of them have 3 IVs and one has two.
- DThat this experiment has 3 IVs. Two of them have 3 levels and one has two.
12What information do we get from a factorial ANOVA?
- AWe can see the main effects of each IV.
- BWe can see the main effects of each DV.
- CWe can see the main effects of each IV and how they interact.
- DWe can see the main effects of each DV and how they interact.
13Within the variability explained by SSM, how can we further split the variance in an independent measures factorial ANOVA?
- AThe variance explained by SSM is made up of the MS for each variable plus the MS for the interactions.
- BThe variance explained by SSM is made up of the SS for each variable plus the SS for the interactions
- CThe variance explained by SSM is made up of only the SS for each variable.
- DYou cannot further split the variance explained by SSM.
14I have two IVs: stats knowledge (SSA) and psychology knowledge (SSB). How do we calculate SSA?
- AWe collapse across SSB and look only at the scores split by the stats knowledge variable as compared to the grand mean.
- BWe collapse and look only at the scores split by the psych knowledge variable as compared to the grand mean.
- CWe collapse across SSB and look only at the scores split by the stats knowledge variable as compared to the participants' means.
- DSSA is the same as SSM in this context.
15Independent Samples Factorial ANOVA: How do I calculate SSAxB? And what does it tell me?
- AAfter calculating SSA and SSB then the remaining variance accounted for by SST is the variance from SSAxB. This is the interaction between the two variables.
- BAfter calculating SSA and SSB then the remaining variance accounted for by SSM is the variance from SSAxB. This is the main effects between the two variables.
- CYou do not get SSAxB in independent samples factorial ANOVA.
- DAfter calculating SSA and SSB then the remaining variance accounted for by SSM is the variance from SSAxB. This is the interaction between the two variables.
16What is an interaction?
- AWhen the effect of one DV on the IV is dependent on another DV.
- BWhen both IVs have a main effect.
- CWhen the effect of one IV on the DV is dependent on another IV.
- DWhen both DVs have a main effect.
17I've graphed the interaction between stats knowledge (two levels) and psychology knowledge (two levels) and their effect on a test score. What does this interaction show?
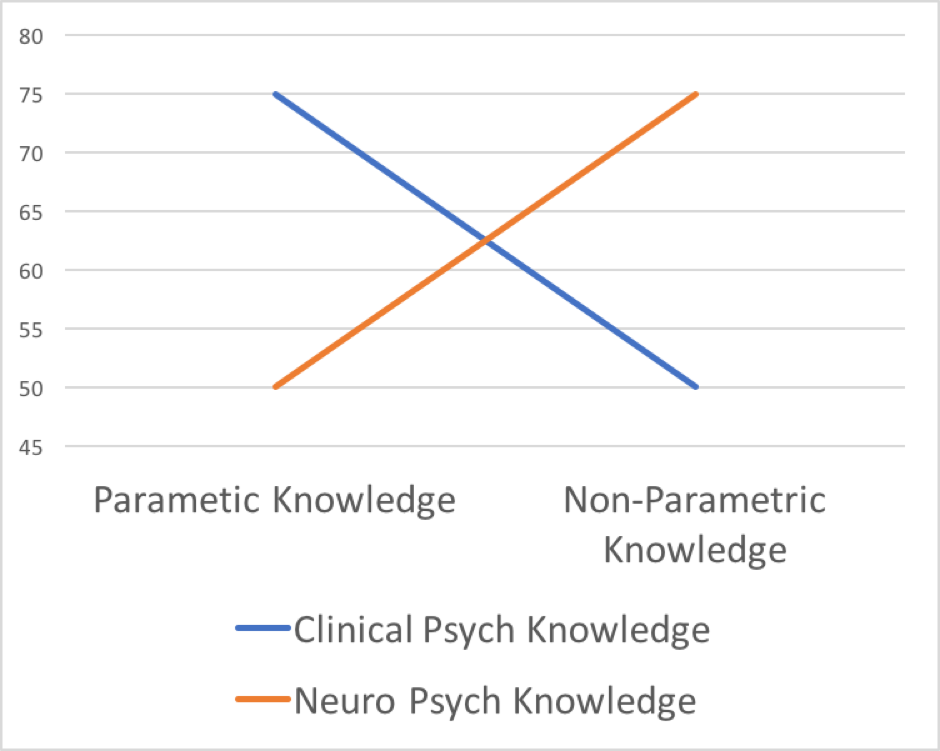
- AThat participants that had good clinical psychology knowledge and good parametric scored highly on the test, however this did not occur for those with good clinical psychology knowledge and good non-parametric knowledge. The converse was true for those in the good neuropsychology group.
- BThat participants that had good clinical psychology knowledge and good non-parametric knowledge scored highly on the test, however this did not occur for those with good clinical psychology knowledge and good parametric knowledge. The converse was true for those in the good neuropsychology knowledge group.
- CThat participants that had good clinical psychology knowledge and good parametric knowledge scored highly on the test, however this did not occur for those with good clinical psychology knowledge and good non-parametric knowledge. The same was true for those in the good neuropsychology knowledge group.
- DThat participants that had good clinical psychology knowledge scored highly on the test, however, the converse was true for those in the good neuropsychology knowledge group.
18If my study is a between-subjects-design - am I concerned about whether my data breaks the assumption of homogeneity or the assumption of sphericity? And what would I expect to see if this assumption had been met?
- AHomogeneity of variance - the Levene's test should be significant.
- BSphericity - the Mauchly's test should not be significant.
- CHomogeneity of variance - the Levene's test should not be significant.
- DSphericity - the Mauchly's test should be significant.
19After completing our factorial ANOVA - why do we employ syntax to look at the interaction?
- ABecause this is the best way to explore the differences between the different levels of an interaction.
- BTrick question - this is only used the examine main effects.
- CWe don't - multiple comparisons tells us enough.
- DBecause we want to examine the differences between the IVs.
20Factorial ANOVA: Why can't we only interpret the F from the SSM line of the output?
- ATrick question - we only interpret the SSM line of output in factorial ANOVA.
- BBecause we need to know how much variance is explained by the SSR output, which is part of the variance explained by SSM.
- CBecause we don't just need to know how much variance is explained by the model but whether each individual variable is explaining a significant amount of variance.
- DBecause we don't just need to know how much variance is explained by the model but whether each individual variance and their interactions are explaining a significant amount of variance.
21How do we partition the variance for SSM in factorial repeated measures ANOVA?
- AWe split it into SSA and SSB.
- BWe split it into SSA, SSB and SSAxB.
- CWe don't split the variance beyond SSM.
- DWe split it into SSA and SSAxB.
22How do we partition the variance for SSR in a repeated measures factorial ANOVA?
- AWe don't partition the variance of SSR.
- BInto SSRA and SSRB.
- CInto SSRA, SSRB and SSRAxB
- DInto SSRA and SSRAxB.
23Factorial Repeated Measures ANOVA: Which formula do I use to calculate F for one of my main effects?
- AMSA/MSRA
- BMSA/MSR
- CMSA/dfA
- DMSA/MSB
24In a repeated measures ANOVA are we concerned with Homogeneity of Variance or Sphericity? And what do we expect to see if the assumption has been met?
- ASphericity - Mauchly's test should be significant.
- BHomogeneity of Variance - Levene's test should not be significant.
- CSphericity - Mauchly's test should not be significant.
- DHomogeneity of Variance - Levene's test should be significant.
25Below is my syntax for a 2-way-3x2 repeated measures ANOVA. IV1 Time of Meal (Breakfast, Lunch and Dinner), IV2 Day (Day1, Day2). I'm missing a section of the syntax - complete it.
GLM BreakfastDay1 BreakfastDay2 LunchDay1 LunchDay2 DinnerDay1 DinnerDay2
/WSFACTOR [COMPLETE THIS LINE]
/EMMEANS = TABLES(TimeMeal*Day) COMPARE(Day)- ATimeMeal 2 Day 3
- BDay 3 TimeMeal 2
- CTimeMeal 3 Day 2
- DTimeDay6
26How is an interaction different from a main effect?
- AFor a main effect: IV1 will have the same effect on the DV in all levels of IV2. In an interaction: IV1 will only effect the DV in specific levels of IV2.
- BFor main effect: IV1: IV1 will have the same effect on the DV in specific levels of IV2. In an interaction: IV1 will ave the same effect on the DV in all levels of IV2.
- CMain effects and interactions are the same.
- DFor a main effect: DV1 will have the same effect on the IV in all levels of DV2. In an interaction: DV1 will only effect the IV in specific levels of DV2.
27I've conducted an experiment examining real vs sham brain stimulation on a verbal fluency experiment. I've recorded number of words produced to the letter S in one minute at Pre, During and Post stimulation. The graph of my results is below. What is the interaction showing?
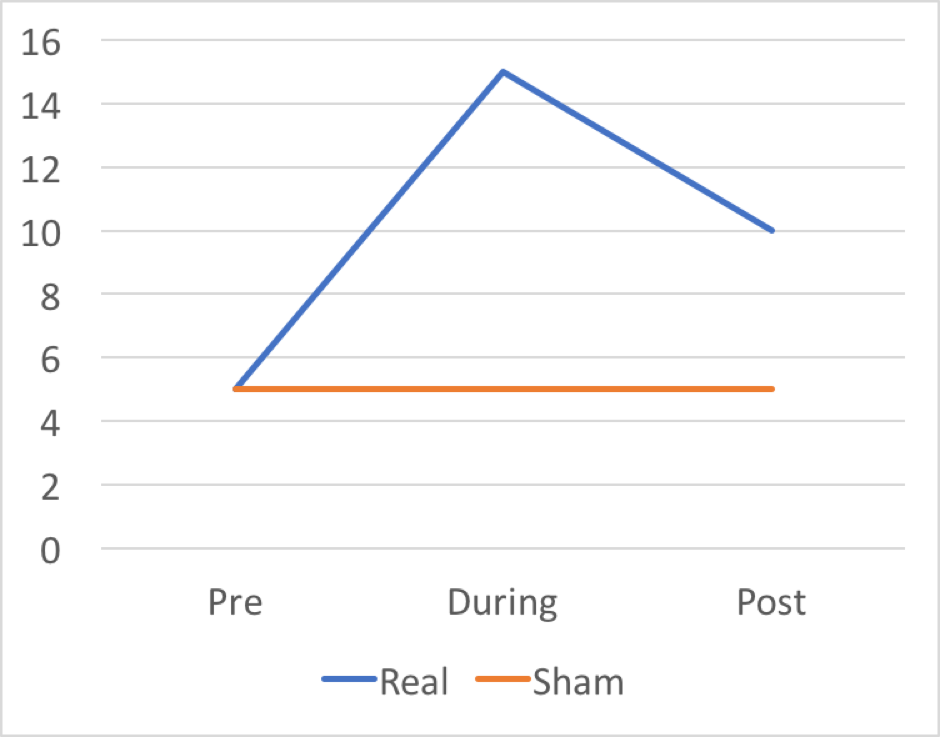
- ASham stimulation increased performance as compared to Real, but only During stimulation and Post stimulation - there was no difference Pre stimulation.
- BReal stimulation increased performance as compared to Sham, but only During stimulation and Post stimulation - there was no difference Pre stimulation.
- CReal stimulation increased performance as compared to Sham, but only Pre stimulation and Post stimulation - there was no difference During stimulation.
- DThere is no interaction between these variables.
28Which is a mixed factorial design?
- AA design which has 3+ IVs. At least one of which is between subjects and one within subjects.
- BA design which has 2+ IVs. At least one of which is between subjects and one within subjects.
- CA design which has 2+ IVs. Both of which is between subjects.
- DA design which has 2+ IVs. Both of which is within subjects.
29In a mixed factorial ANOVA are we concerned with Homogeneity of Variance or Sphericity?
- AOnly Homogeneity of Variance.
- BOnly Sphericity which applies when the within subjects IV has 3+ levels as with repeated measures designs that are not mixed.
- CBoth, but Sphericity only applies when the within subjects IV has 3+ levels as with repeated measures designs that are not mixed.
- DOnly Sphericity which applies when the within subjects IV has 2+ levels as with repeated measures designs that are not mixed.
30In SPSS, what process do we use to complete a mixed factorial ANOVA?
- AThe same as for independent measures ANOVA but we add in the between subjects variable at the 'define' stage.
- BMixed ANOVA uses its own process which is entirely different from repeated and independent measures ANOVA.
- CThe same as for repeated measures ANOVA but we add in the between subjects variable at ehe 'Post Hoc' stage.
- DThe same as for repeated measures ANOVA but we add in the between subjects variable at the 'define' stage.
31Assuming the data meet the assumption of parametric tests, non-parametric tests compared to their parametric counterparts _______________.
- Aare less conservative
- Bare less likely to accept the alternative hypothesis
- Chave less statistical power
- DAll of the above.
32A researcher measured leadership skills in police officers, doctors, and accountants. There were unequal group sizes and the data were skewed. What test should be used to analyse the data?
- AWilcoxon test.
- BKruskal-Wallis test.
- COne-Way ANOVA.
- DFriedman test.
33The results of the test used to analyse the data in the Question: "A researcher measured leadership skills in police officers, doctors, and accountants. There were unequal group sizes and the data were skewed. What test should be used to analyse the data?" showed a significant result. How should the researcher carry out post-hoc tests?
- ACompare groups using the Mann Whitney test.
- BCompare groups using the Wilcoxon test.
- CCompare groups using a t-test.
- DNone of the above. Post-hoc analyses cannot be carried out with non-parametric data.
34An advantage of non-parametric statistics is that __________.
- Ayou need a computer to calculate them
- Bthey have many assumptions to meet
- Cthey are easy to calculate
- Dthey are very powerful
35Which of the following tests is analogous to a standard within-subjects ANOVA?
- AMann-Whitney.
- BFriedman.
- CWilcoxon.
- DKruskal-Wallis.
36Tied scores (when two or more scores have the same value) may present a problem in non-parametric tests. The way to deal with them in a Kruskal-Wallis test is to _________.
- AThrow out the tied data.
- BAssign any tied values the average of the ranks they would been received had they not been tied.
- CUse a random number table to assign ranks to the tied values.
- DAssign any tied numbers the lower of the ranks they would have received had they not been tied.
37A dataset contains the following values: 23, 28, 37, 23, 45, 49, 37, 62. Rank the values. Which rank is associated with value 37?
- A3.5
- B4
- C4.5
- D6
38Researchers wanted to examine whether the 'see-food' diet was effective. A group of volunteers were placed on the diet and their weight (in kilograms) was measured at the beginning of the diet, after 1 month, after 2 months, then at the end of the diet after 3 months. The data were not normally distributed. Which test would be appropriate to analyse this data?
- AMann-Whitney.
- BFriedman.
- CWilcoxon.
- DKruskal-Wallis.
39The SPSS output from the study described in the question: "Researchers wanted to examine whether the 'see-food' diet was effective. A group of volunteers were placed on the diet and their weight (in kilograms) was measured at the beginning of the diet, after 1 month, after 2 months, then at the end of the diet after 3 months. The data were not normally distributed. Which test would be appropriate to analyse this data?"
What is the correct way to report these results? (x^2 = Chi-squared)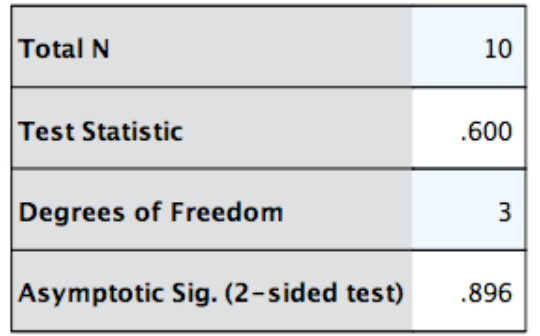
- AThe weight of participants did not significantly change during the diet, x^2 (3) = 0.60, p = .90
- BThe weight of participants did not significantly change during the diet, x^2 (x) = 0.60, p = .89
- CThe weight of participants significantly changed during the diet, x^2 (3) = 0.60, p < .50
- DThe weight of participants significantly changed during the diet, x^2 (3) = .60, p > .05
40In a Kruskal-Wallis test, the ___________ the value of H, the more likely you are to reject the null hypothesis.
- Alarger
- Bsmaller
- Cmore negative
- DH is not relevant for the Kruskal-Wallis test.
41What assumption does ANCOVA have that ANOVA does not?
- AHomogeneity of Variance.
- BHomoscedasticity.
- CHomogeneity of Sample Size.
- DHomogeneity of Regression Slopes.
42ANCOVA is _____________.
- Aused to correct for unmeasured variables that could affect the outcome variable
- Ba method of portioning the results of ANOVAs to investigate where differences between independent variables lie
- Ca robust version of ANOVA
- Dan extension of ANOVA that partials out the effect of other measured variables
43A researcher conducted a study to examine whether people's attachment styles are associated with differences in relationship satisfaction. Participants were divided into three groups according to their attachment styles (secure, dismissing, and fearful) and their relationship satisfaction was measured. Depression levels were also measured, as it is known that relationship satisfaction covaries with depression. Which variable should the researcher use a covariate in the data analysis?
- AAttachment style.
- BSecure attachment.
- CDepression.
- DRelationship satisfaction.
44Regarding the study described in the question:
"A researcher conducted a study to examine whether people's attachment styles are associated with differences in relationship satisfaction. Participants were divided into three groups according to their attachment styles (secure, dismissing, and fearful) and their relationship satisfaction was measured. Depression levels were also measured, as it is known that relationship satisfaction covaries with depression. Which variable should the researcher use a covariate in the data analysis?"
which of the below questions would be relevant to the data analysis?- ADoes relationship satisfaction have a significant effect on the relationship between attachment and depression?
- BWhat would the means of the groups be on relationship satisfaction if their levels of depression were constant?
- CWhat would the mean relationship satisfaction be if levels of depression were constant?
- DWhat would the mean depression score be for the three groups of attachment styles if their levels of relationship satisfaction were constant?
45What problem do you foresee with the study described in the question:
"A researcher conducted a study to examine whether people's attachment styles are associated with differences in relationship satisfaction. Participants were divided into three groups according to their attachment styles (secure, dismissing, and fearful) and their relationship satisfaction was measured. Depression levels were also measured, as it is known that relationship satisfaction covaries with depression. Which variable should the researcher use a covariate in the data analysis?"?- AThere could be more than three groups.
- BIt is likely that there will be a linear association between depression and relationship satisfaction.
- CIt is likely that the regression lines will be parallel.
- DDepression might also be related to attachment style.
46The larger the F statistic, the larger the ________ compared to the ________.
- Avariation between groups; variation within groups
- Bvariation within groups; variation between groups
- Cvariation between groups; total variation
- Dtotal variation; variation between groups
47A covariate is best described as ___________.
- Aa variable that is related to the dependent variable
- Ba variable that is directly influenced by the dependent variable
- Ca variable that is related to the independent variable
- Da variable that is unrelated to all other variables in the study
48A researcher wanted to see whether giving students caffeine would improve their memory. He gave all students a memory test, then he randomly assigned participants to two groups. One group received a caffeinated drink and the other group received a decaffeinated drink. Both group then took another memory test (with different questions). The researcher used ANCOVA to analyse the data. Which variable was the covariate?
- ACaffeine.
- BScore on the first memory test.
- CScore on the second memory test.
- DThere was no covariate.
49The SPSS output from the ANCOVA is shown below. What is the correct way to report these results?
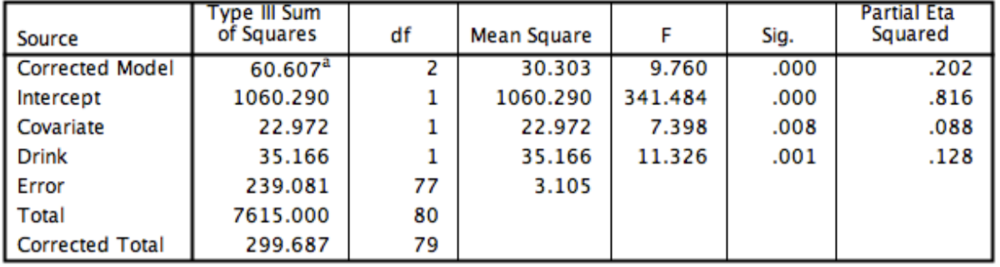
- AThere was a significant effect of caffeine on memory after controlling for the effect of the covariate, F (1, 77) = 11.33, p = .001
- BThere was no significant effect of caffeine on memory after controlling for the effect of the covariate, F (1, 77) = 11.33, p > .05
- CThere was a significant effect of caffeine on memory after controlling for the effect of the covariate, F (1, 77) = 7.40, p = .008
- DThere was no significant effect of caffeine on memory after controlling for the effect of covariate, F (1, 77) = 341.48, p < .001
50According to this output, which of the following statements is true?
- AThere was no significant relationship between the covariate and the dependent variable.
- BThere was a significant relationship between the covariate and the dependent variable.
- CThe data violate the assumption of equal variances.
- DThe data do not violate the assumption of equal variances.
51What would you use Box's test for?
- ATo test for multivariate normality.
- BTo test for a plausible linear combination of the dependent variables.
- CTo test for homogeneity of variance.
- DTo test for homogeneity of covariance matrices.
52If you MANOVA is statistically significant:
- AYou could conduct separate Bonferroni-corrected ANOVAs on each dependent variable.
- BThere is no added value in performing discriminant function analysis.
- CYou could conclude that all groups differ significantly.
- DNone of the above are correct.
53How does MANOVA handle the dependent variables (DVs) in the analysis?
- AThe DVs are compiled into a linear combination.
- BThe DVs are entered sequentially into a model.
- CThe DVs are entered stepwise into an analysis.
- DThe DVs are standardised and summed.
54Which one of these might you consider a violation in MANOVA, suggesting it may be better to use an alternative analysis?
- AYou have 30 participants per group in you between participants design.
- BYou have equal numbers of participants and it is a large sample size.
- CYou have normally distributed dependent variables and all linear combinations of the dependent variables.
- DBox's M has an associated p-value of <0.05 and you have unequal sample sizes.
55The difference between MANOVA and ANOVA is that MANOVA has the ability to handle __________.
- Aseveral dependent variables
- Bseveral independent variables
- Cnon-metric independent variables
- Ddata with large error terms
56A researcher wanted to examine the effects of a new antidepressant drug. She recruited 60 clinically depressed participants and randomly allocated them to three conditions: No dose (placebo), low dose and medium dose of the drug. She administered the drugs to participants for one month, then measured their mood levels by asking them to complete a self-report measure. However, she decided that mood should not just be measured by self-report, so she also asked the participants' psychiatrists to give their ratings of each person's mood. All mood ratings were measured on a 1-50 scale, with 1 indicating the lowest possible mood and 50 indicating the highest possible mood. The SPSS output from the data analysis is shown below.
Are the assumptions of MANOVA met?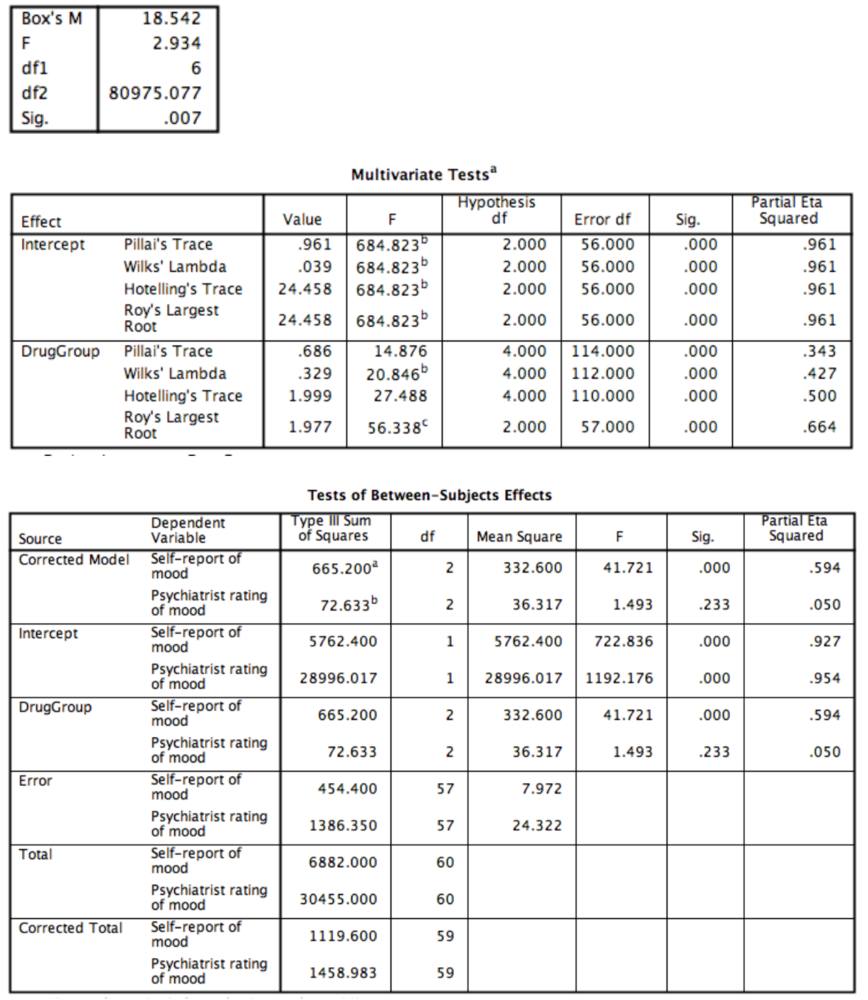
- AYes.
- BNo, the assumption of equality of covariance matrices is violated.
- CNo, the assumption of multivariate normality is violated.
- DIt is not possible to tell from this output.
57A researcher wanted to examine the effects of a new antidepressant drug. She recruited 60 clinically depressed participants and randomly allocated them to three conditions: No dose (placebo), low dose and medium dose of the drug. She administered the drugs to participants for one month, then measured their mood levels by asking them to complete a self-report measure. However, she decided that mood should not just be measured by self-report, so she also asked the participants' psychiatrists to give their ratings of each person's mood. All mood ratings were measured on a 1-50 scale, with 1 indicating the lowest possible mood and 50 indicating the highest possible mood. The SPSS output from the data analysis is shown below.
Which of the following statements about the output is true?- AThere is a significant multivariate difference between the drug groups.
- BSignificant univariate differences are only present for psychiatrist ratings of mood.
- CSelf-report ratings of mood are significantly higher than psychiatrist ratings of mood.
- DAll of the above are true.
58A researcher wanted to examine the effects of a new antidepressant drug. She recruited 60 clinically depressed participants and randomly allocated them to three conditions: No dose (placebo), low dose and medium dose of the drug. She administered the drugs to participants for one month, then measured their mood levels by asking them to complete a self-report measure. However, she decided that mood should not just be measured by self-report, so she also asked the participants' psychiatrists to give their ratings of each person's mood. All mood ratings were measured on a 1-50 scale, with 1 indicating the lowest possible mood and 50 indicating the highest possible mood. The SPSS output from the data analysis is shown below.
Which of the following might be a problem with the study described here?- AThere may have been individual differences in mood at the beginning of the study.
- BThere was only one independent variable.
- CThe dependent variables were measured on different scales.
- DAll of the above.
59A researcher wanted to examine the effects of a new antidepressant drug. She recruited 60 clinically depressed participants and randomly allocated them to three conditions: No dose (placebo), low dose and medium dose of the drug. She administered the drugs to participants for one month, then measured their mood levels by asking them to complete a self-report measure. However, she decided that mood should not just be measured by self-report, so she also asked the participants' psychiatrists to give their ratings of each person's mood. All mood ratings were measured on a 1-50 scale, with 1 indicating the lowest possible mood and 50 indicating the highest possible mood. The SPSS output from the data analysis is shown below.
Which statistic test gives the largest effect size for the effect of the drug?- APillai's Trace.
- BWilks' Lambda.
- CRoy's Largest Root.
- DThey are all equal.
60Poor research practices such as trying out several statistical analyses to get a significant results may increase the likelihood of ___________.
- Aa Type 1 error occurring
- Ba Type 2 error occurring
- Cincorrectly accepting the null hypothesis
- Dhaving insufficient statistical power
61A Type 1 error means ___________.
- Awe have rejected the null hypothesis when it is, in fact, true
- Bwe have rejected the alternative hypothesis when it is, in fact, true
- Cwe have accepted the null hypothesis when it is, in fact, false
- DNone of the above.
62The tendency for statistically significant findings to be published over nonsignificant findings is known as _________.
- Asampling error
- Btype 2 error
- Cpublication bias
- Dmeta-analysis
63Statistical power can be increased by _________.
- Aincluding more independent variables
- Bdecreasing the sample size
- Cincreasing the sample size
- Dincluding more dependent variables
64When power = 0.56, what are you chances of finding an effect (if one exists)?
- A44%
- B5%
- C56%
- D95%
65The power of a statistical test can be defined as __________.
- Athe probability of not making a type 2 error
- Bthe probability of not making type 1 error
- Cthe probability of rejecting the null hypothesis when it is actually true
- DAll of the above.
66An effect size shows ___________.
- Awhether to reject the Null Hypothesis
- Bthe magnitude of a result in a study
- Cthe likelihood of committing a type I error
- Dwhether a result is statistically significant
67Prospective power analysis involves calculating ________.
- Athe level of power which would be necessary to give a particular effect size
- Bthe effect size which would be given by a particular sample size
- Cthe sample size which would be necessary for a given effect size to give certain level of power
- Dthe level of alpha which would be given by a particular level of power for a given sample size
68The combination of effect sizes from more than one study is known as _________.
- Apower analysis
- Bdiscriminatory analysis
- Cmeta-analysis
- Dmultivariate analysis
69Unlike p-values, effect sizes are _________.
- Acalculated from tables of critical values
- Blimited to a range from 0 to 1
- Cnot influenced by sample size
- Dvery sensitive to outliers
Information
- Description
- Quiz on Research Methods IV MCQs, created by Benjamin Maier on 21/05/2017.
- Author
- Benjamin Maier
- Language
- Deutsch
- Views
- 598
- Rating
- No ratings yet Rate this quiz