
Mind map
Lecture 7: Classification for Targeting 1
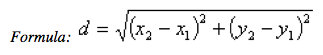
Map content
Lecture 7: Classification for Targeting 1
Techniques: 1) K-NN 2) Linear Regression 3) Logistic Regression
- K-NN Techniques:
- 1) K is a parameter that tends to be an odd no. (1,3,5,7) for 1/0 variables
- 2) Using historical data
- 3) Trying to pick newcomer customers that are closest to your existing (historical) customers and basing them on that existing groupàNN = for every new customer, extracts all NN and examines what those NNs have done and makes predictions/probabilities accordingly
- Concept of distances helps: based on attributes cutting down the number of historical customers you can use to predict the behaviour of a newcomer
- Regression Trees (No distance measures needed)
- How is it used? 1. Based on historical information of customer purchase we construct the decision tree. 2. Once we build the tree, we use it make predictions about new customers.
- What is the basis of the tree’s construction? = Homogeneity; the more homogeneous the division, the purer the sub-nodes
- Least-squares regression: = another predicting/forecasting tool X-axis: attributes; independent variables Y-axis: what you want to predict/forecast (response); dependent variable  a and b = slope
- How it works? Criteria: Looks at historical data and tries to fit a function: Linear regression (line of best fit) -> in attempt to minimise the square distance of the error (-) Linear regression: Predictions have to be between 1-100, regressions can shoot in the –‘s
- Logistic Regression: The dependent (predicted) variable is categorical. (e.g. 0/1;male/female;good/bad), not as numerical as linear regression
- Instead of using linear line, we use a prediction curve. The dependent variable is categorical, not numeric as in linear regression. The independent variable are still numeric. Eg: Predicting the probability of a response to a marketing campaign, we might find that people with high income are more likely to respond.
- K-NN Techniques:
Classification = Predicting each customer as a respondent or as a non-respondent (1/0) or probability of response or no response
Distances and Space (Representation) - Similarity and differences between objects (x and y) are expressed according to a distance measure (d)àEuclidean distance is our normal measure (physical distance between the points)
- Once positioned, gives us an idea of whether customers are near/far from one another. Allows for predictions; based upon which customers are close to one another, and thus based on their neighbours, we can make a prediction
- (-) Ranges of attributes are unclear; ranges of the first attribute can be completely different from that of the second attribute
- Solution: normalization = bringing all the attributes to one comparable scale; so one attribute does not dominate the other
- Cannot use Euclidean distance measure -> use matching coefficient = (a+d) / (a+b+c+d)
- Once positioned, gives us an idea of whether customers are near/far from one another. Allows for predictions; based upon which customers are close to one another, and thus based on their neighbours, we can make a prediction
Exploratory Analysis: Understanding the customers, in which segments the customers lie, number of segments, and their characteristics/behaviours
- Segment: dividing customers into similar in relevant attributes, and quite different from people in other segments
- Objective: Not only to identify the segments but to also give a verbal description of these segments (ex; Coca-Cola Life -> Targeting organic and health-conscious segment)
- Tool: Cluster Analysis
- (Vs. classification, we are not trying to make predictions or forecasts) Clustering is the technique used for identifying segments and the characteristics of the segments -> by taking a large chunk of data and then dividing that data into relevant groups
- Concept: (similar to classification) positioning customers in space and using the concept of distance to measure how close customers are to one another
- For higher dimensions/ more attributes (output generated from CA differs based on algorithms used: 1) Non-overlapping - easiest to interpret/ every customer belongs to only 1 seg. 2) Overlapping - each customer may belong to mult. seg. 3) Probabilistic membership - customer belongs to mult. seg. but with certain probability. 4) Hierarchical - Provided levels; customers are measured by the closeness of customers - >which group of customers are closest together.
- Clustering Methods
- 1) Ward's hierarchical cluster method - Selecting two customers to place into one cluster based on the least distance between them
- 2) K- Means Method: Divide all the items into completely seperate group
- (Vs. classification, we are not trying to make predictions or forecasts) Clustering is the technique used for identifying segments and the characteristics of the segments -> by taking a large chunk of data and then dividing that data into relevant groups
Images and files in the map
Information
- Description
- Mind Map on Lecture 7: Classification for Targeting 1, created by chotika.a on 01/10/2015.
- Created by
- chotika.a
- Views
- 0
- Rating