
Notas
Week 6
Conteúdo das notas (10)
Página 1
when errors exist in ML algorithm ?
- add more training data
- add more features
- remove features
- try polynomial fit
- try increasing lambda
-Try decreasing lambda
Use diagnostic: that tells how accurately the ML algorithm fit/don't fit the data;
Página 2
hypothesis testing:
divide data into training & test data
- Use algorithm to learn parameter Theta from the training set;
-compute test set error
- 1/2m sigma (htheta -y)^2 (for linear regression)
- for logistic regression:
-use misclassification error :
proportion of test data that was misclassified
Página 3
Model Selection :
Choose models with different degrees from linear regression (d=1) to polynomial (d=10);
Compute the learning parameter theta from Training set
Compute the error from the Test set;
error from Test set is important because : at higher degrees , polynomial might overfit the current data on the training sets
model selection:
divide data into training, cross validation and test sets
run models on training;
verify error on cross validation; pick a specific model
test the specific model on test data
Página 4
bias and variance:
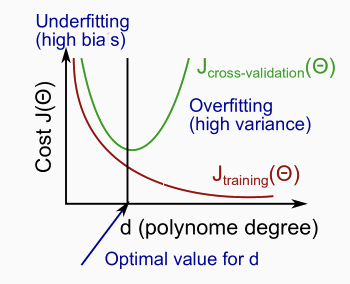
compute the training error and cross validation for models with different degrees of polynomials;
Jtrain
Jcross ;
if jtrain and jcost are both high , High bias issue - Underfitting
jtrain is low and jcost is high, high variance issue - Overfitting
Página 5
choosing learning parameter Lambda:
choosing the learning parameter Lambda:
determine different lambdas (0 , 0.01...10)
run thru the different models with different degrees
for different lambdas , go thru different models to learn thetas
Compute the cross validation error using the learned Θ (computed with λ) on the JCV(Θ) without regularization or λ = 0
Select the best combo that produces the lowest error on the cross validation set.
Using the best combo Θ and λ, apply it on Jtest(Θ) to see if it has a good generalization of the problem
Página 6
Learning Curve:
plot error as function of m;
ex: fitting quadratic function to m=1 ,2 ,3 data sets will result in low training error
for m > 3 . training error starts to increase
for cross validation set , error is high with m -1,2,3 ; and error starts to decrease for m >3
another example : fitting linear regression : high bias case
fit the best possible straight line;
low training set : low training error; high cross validation error
cross validation error plateaus soon with high error value;
with more data : training error increases to high value and value closer to cross validation error
Experiencing high bias:
low training set : low training error; high cross validation error
high training set : high training error ; high cross validation error
If a learning algorithm is suffering from high bias, getting more training data will not (by itself) help much.
Experiencing high variance:
high order polynomial fit (>10)
Low training set size: Jtrain(Θ) will be low and JCV(Θ) will be high.
Large training set size: Jtrain(Θ) increases with training set size and JCV(Θ) continues to decrease without leveling off. Also, Jtrain(Θ) < JCV(Θ) but the difference between them remains significant.
If a learning algorithm is suffering from high variance, getting more training data is likely to help.
Página 7
neural networks and fitting:
small nn : prone to underfitting
large nn : prone to overfitting ; use lambda to address it
Página 8
machine learning system design:
building spam classifier:
supervised learning : y=1 => spam ; y=0 => not spam;
create a vector list of words : spam : non-spam words : X features: buy, discount, Andrew, etc
assign : Xj =1 => if word appears ; Xj =0 : if not appears;
options to build better classifier:
Collect lots of data (for example "honeypot" project but doesn't always work)
Develop sophisticated features (for example: using email header data in spam emails)
Develop algorithms to process your input in different ways (recognizing misspellings in spam).
Página 9
machine learning system design:
error analysis:
when starting on new mc learning problem:
1) build quick and dirty solution
2) test it on cross validation set :
3) plot learning curves to test if more data , more features are likely to help;
3) manually analyze errors of cross-validation set to spot where errors were made
we should try new things, get a numerical value for our error rate, and based on our result decide whether we want to keep the new feature or not.
Página 10
precion and recall:
precision = true +/(true + plus false +)
recall = true +/ (true + plus false negative)
metric for threshold :
F score = 2PR/(P+R)
for different threshold : find one that has high f score;
Informações
- Descrição
- Machine Learning Notas sobre Week 6, criado por Mukundhan Srinivasan em 30-04-2018.
- Criado por
- Mukundhan Srinivasan
- Visualizações
- 0
- Avaliação