
Quiz
Experimental Design Test 3
Dieses Quiz enthält Fragetypen, die sich im gewohnten Player öffnen.
Fragen in diesem Quiz (97)
1What is the difference between a 2-factor CRD and a 1-way CRD?
- A2-factor CRD allows for simultaneous testing of 2 treatment effects in the same experiment
- B1-factor CRD allows for simultaneous testing of 2 treatment effects in the same experiment
- C2-factor CRD tests the average of 2 Mu's for each Eu
- D1-factor CRD tests the average of 2 Mu's for each EU
2Can you add nesting or blocking to a 2-factor CRD?
- AYes
- BNo
3What are some of the advantages to using a 2-way CRD?
- ACan use fewer resources
- BCan gain efficiency in testing single factors
- CAllows you to test for interaction
- DDecreases the number of levels in each factor analysis
4What are some of the drawbacks of using a 2-factor CRD?
- ABecomes more difficult to do based on practical limitation
- BUses more resources
- CLoses efficiency in testing single factors
- DCan't test for interaction
5What are the assumptions of a 2-factor CRD?
- AIndependence within cells
- BRandomly Drawn Individuals within cells
- CVariances of the cells are similar
- DNormality within the cells
- EAdditivity within the cells
- FMultiplicity of the cells
- GNormality of measurement units
- HIndependence of measurement units
- IHOV of measurement units
6What are the assumptions of a 3-factor CRD?
- AIndependence within cells
- BRandomly Drawn Individuals in cells
- CVariances of cells are similar
- DNormality within the cells
- EAdditivity within the cells
- FMultiplicity within the cells
- GNormality of measurement units
- HIndependence of measurement units
- IHOV of measurement units
7Each combination of the two factors applied at the same time is a [blank_start]cell[blank_end] containing [blank_start]experimental units[blank_end].
- Acell
- Bpillar
- Cblock
- Dexperimental units
- Emeasurement units
8If each cell in a two-factor CRD only contains one experimental unit, the calculations are the same as a [blank_start]Randomized Block ANOVA[blank_end], even though the designs are different.
- ARandomized Block ANOVA
- BRepeated Time Measure ANOVA
- COne-Way ANOVA
9This is an example of a/an [blank_start]Proportional[blank_end] [blank_start]Balanced[blank_end] design. In this design, [blank_start]n-cells are the same in all cells[blank_end] and tests of cells on diagonal [blank_start]are ok[blank_end].
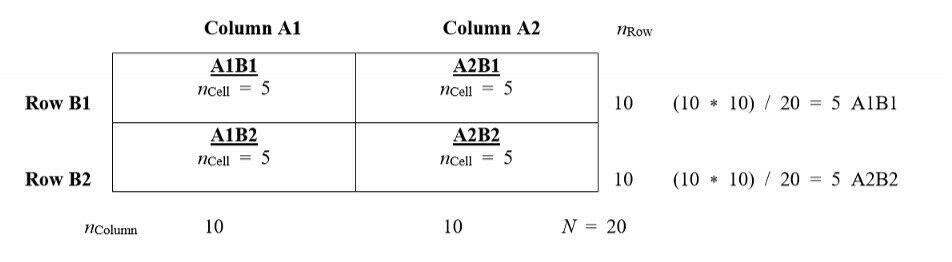
- AProportional
- BDisproportional
- CBalanced
- DUnbalanced
- En-cells are the same in all cells
- Fratios of n-cells are the same
- Gratios of n-cells are not the same
- Hare ok
- Ifail
10This is an example of a/an [blank_start]Proportional[blank_end] [blank_start]Unbalanced[blank_end] design. In this design, [blank_start]n-cells are the same in all cells[blank_end] and tests of cells on diagonal [blank_start]are ok[blank_end].
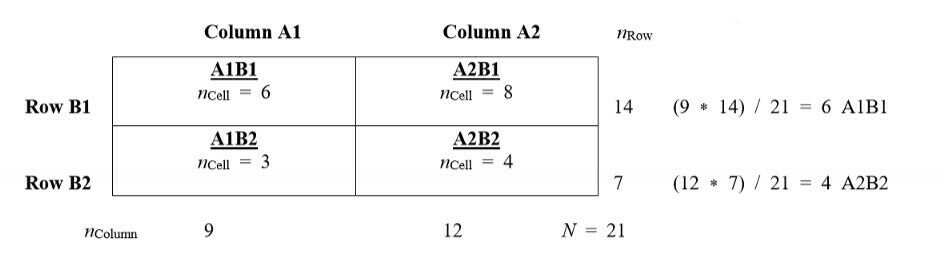
- AProportional
- BDisproportional
- CUnbalanced
- DBalanced
- En-cells are the same in all cells
- Fratios of n-cells are the same
- Gratios of n-cells are not the same
- Hare ok
- Ifails
11This is an example of a/an [blank_start]Proportional[blank_end] [blank_start]Balanced[blank_end] design. In this design, [blank_start]n-cells are the same in all cells[blank_end] and tests of cells on diagonal [blank_start]are ok[blank_end].
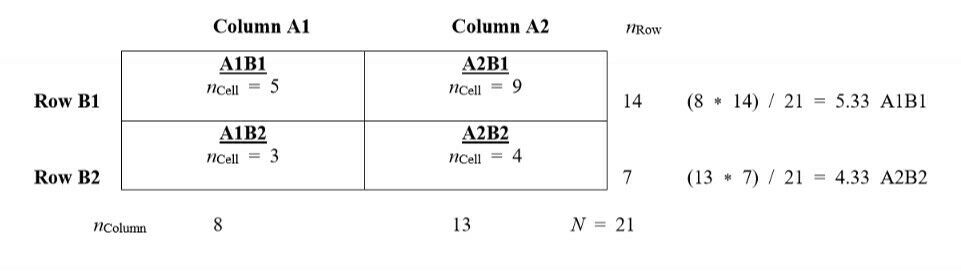
- AProportional
- BDisproportional
- CBalanced
- DUnbalanced
- En-cells are the same in all cells
- Fratios of n-cells are not the same
- Gratios of n-cells are the same
- Hare ok
- Ifail
12This is the results of an example Two-Factor CRD ANOVA with Multiple Replicates.
What kind of interaction is this? [blank_start]No Interaction[blank_end]
Can we interpret Main Effects? [blank_start]Yes[blank_end]
Would Simple Effects be of interest? [blank_start]Possibly[blank_end]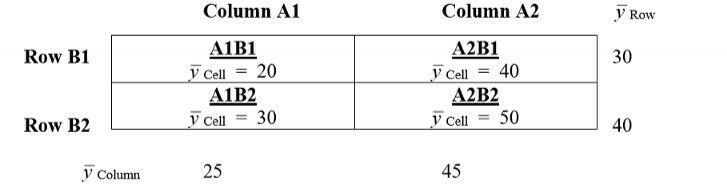
- ANo Interaction
- BInteraction due to Multiplicative Data
- CInteraction due to biological process
- DYes
- ENo
- FPossibly
- GDefinitely
- HLikely not
- IYes, after a ln transformation
- JOne might
13This is the results of an example Two-Factor CRD ANOVA with Multiple Replicates.
What kind of interaction is this? [blank_start]No Interaction[blank_end]
Can we interpret Main Effects? [blank_start]Yes[blank_end]
Would Simple Effects be of interest? [blank_start]Possibly[blank_end]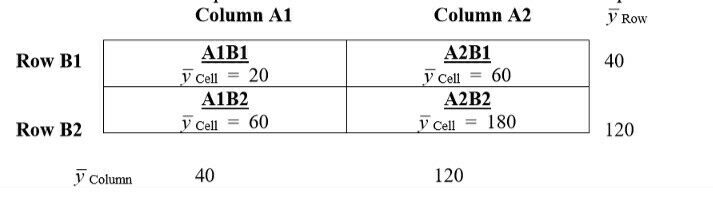
- ANo Interaction
- BInteraction due to Multiplicative Data
- CInteraction due to biological process
- DYes
- ENo
- FPossibly
- GDefinitely
- HLikely not
- IYes, after a ln transformation
- JOne might
14This is the results of an example Two-Factor CRD ANOVA with Multiple Replicates.
What kind of interaction is this? [blank_start]No Interaction[blank_end]
Can we interpret Main Effects? [blank_start]Yes[blank_end]
Would Simple Effects be of interest? [blank_start]Possibly[blank_end]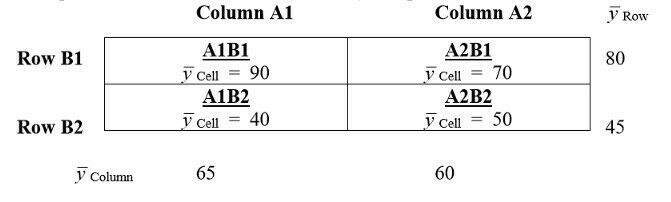
- ANo Interaction
- BInteraction due to Multiplicative Data
- CInteraction due to biological process
- DYes
- ENo
- FPossibly
- GDefinitely
- HLikely not
- IYes, after a ln transformation
- JOne might
15This is the results of an example Two-Factor CRD ANOVA with Multiple Replicates.
What kind of interaction is this? [blank_start]No Interaction[blank_end]
Can we interpret Main Effects? [blank_start]Yes[blank_end]
Would Simple Effects be of interest? [blank_start]Possibly[blank_end]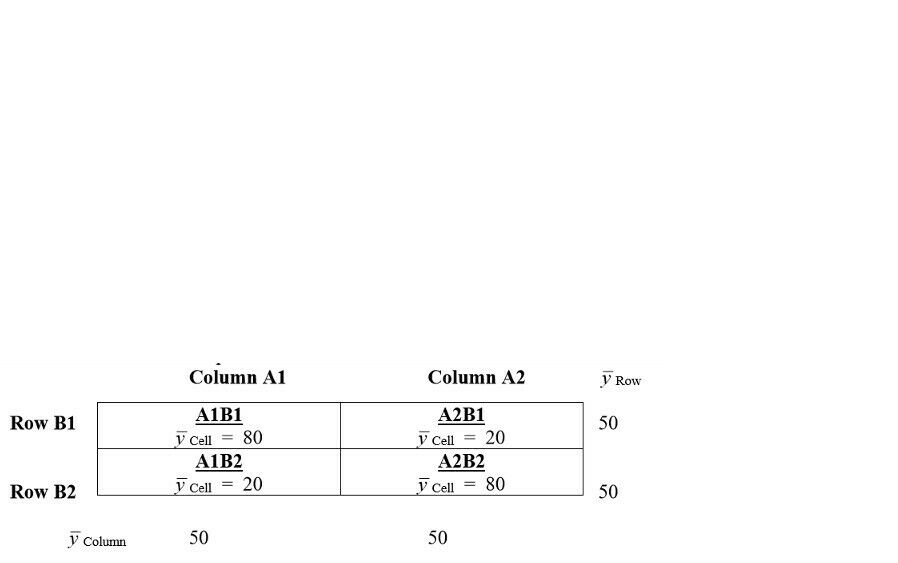
- ANo Interaction
- BInteraction due to Multiplicative Data
- CInteraction due to biological process
- DYes
- ENo
- FPossibly
- GDefinitely
- HLikely not
- IYes, after a ln transformation
- JOne might
16Label the interaction graphs
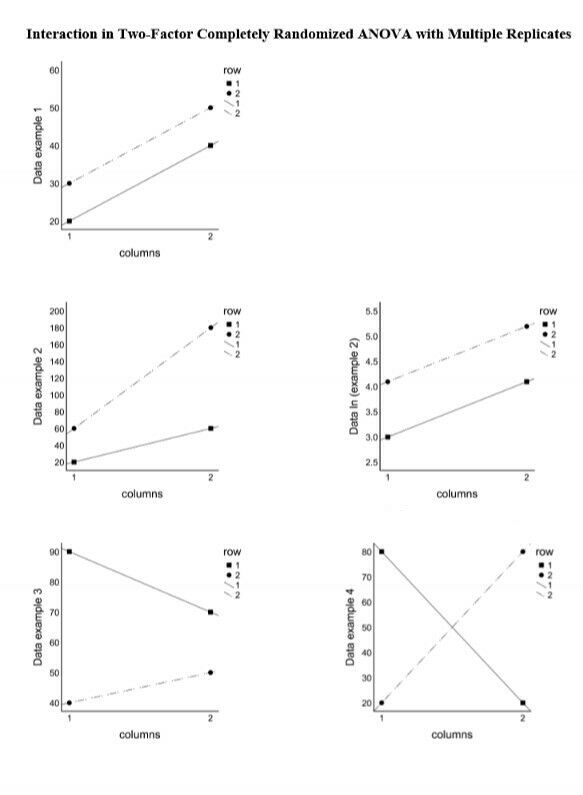
- ANo Interaction
- BOriginal Multiplicative Data
- CMultiplicative data with transformation
- DSome interaction
- EInteraction
17Simple effects or cell means testing is usually done with the interaction effect in the Two-Factor ANOVA is _______, and interpreting main effects of column and row means does not make sense.
- Alarge
- Bsmall
18Sevearal different approaches can be used to examine simple effects. The primary differences in the approaches deal with control of ____________ and ____________ considerations
- Amultiplicity
- Bpower
- Cp-value
- Dadditivity
19What "logical" sets of simple effects exist?
- Awithin columns
- Bwithin rows
- Cwithin columns and rows
- Ddiagonal
20In a Two-Factor ANOVA, if interaction is large and it has been decided that the main effects cannoth be interpreted, can we ignore the two-factor design and analyze each column/row with separate One-Factor Completely Randomized ANOVAs?
- AYes
- BNo
21Is ignoring the two-factor design and running separate One-Factor ANOVAs or t-tests more or less powerfal than constructing the simple effects tests ithin the context of the Towo-Factor ANOVA? Why?
- ALess powerful, because MS-Error and df-Error from all groups are used in the calculation for each pair.
- BLess powerful, because df increases with each One-Factor test
- CMore powerful, because MS-Error and df-Error from all groups are used in the calculation for each pair.
- DMore powerful, because df increases with each One-Factor test
22Model I: [blank_start]fixed - 2 fixed factors[blank_end]
Model II: random - [blank_start]2 random factors[blank_end]
Model III: mixed - [blank_start]1 fixed factor, 1 random factor[blank_end]- Afixed - 2 fixed factors
- B2 random factors
- C1 fixed factor, 1 random factor
23Testing for interaction is...
- Asimilar change in magnitude and direction acoss treatment factor combinations
- Bsimilar p-values in separate One-Factor ANOVA analyses
24What are the null hypotheses of a Two-Factor Completely Randomized ANOVA with Multiple Replicates? (hint: main effects)
- AColumn means are the same
- BRow means are the same
- CInteraction is not present
- DCell means are the same
- EInteraction is present
25What are the assumptions of a Two-Way Completely Randomized ANOVA (Model I) with Multiple Replicates?
- Adata points within each cell are from randomly drawn individuals, normally distributed, and independent of one another
- Bthe variances of the cells are similar
- Cdata is additive
- Ddata points within the experiment are from randomly drawn individuals, normally distributed, and independent of one another
- EHOV within the experiment
- Fdata is multiplicative
26What steps should be taken after the main Two-Way ANOVA?
- AMultiple Comparisons of main effects: testing for pair-wise differences between column/row means
- BSimple effects: testing for pair-wise differences in cell means within each column/row
- CMultiple Comparisons of main effects: testing for pair-wise differences within each column/row means
- DSimple effects: testing for pair-wise differences in cell means between columns/rows
27Select all that apply to Type I SS
- Aalso known as "sequential SS"
- Bvalid only for balanced replication
- CDesigned by Fisher
- DFirst SS developed
- ECan be used for balanced and disproportionate replication
- Ftakes interaction into account
- Goften defaulted to because it works with almost every replication type
- HYate's "unadjusted method of fitting constants"
- IYate's "adjusted method of fitting constants"
- JYate's "weighted squares of means"
28Select all that apply to Type II SS
- Aalso known as "sequential SS"
- Bvalid only for balanced replication
- CDesigned by Fisher
- DCan be used for balanced and disproportionate replication
- Emore powerful than Type III with no interaction
- Ftakes interaction into account
- Goften defaulted to because it works with almost every replication type
- HYate's "unadjusted method of fitting constants"
- IYate's "adjusted method of fitting constants"
- JYate's "weighted squares of means"
29Select all that apply to Type III SS
- Aalso known as "sequential SS"
- Bvalid only for balanced replication
- CDesigned by Fisher
- DFirst SS developed
- ECan be used for balanced and disproportionate replication
- Ftakes interaction into account
- Goften defaulted to because it works with almost every replication type
- HYate's "weighted squares of means"
- IYate's "unadjusted method of fitting constants"
- JYate's "adjusted method of fitting constants"
30With balanced data, all SS methods (Type I, II, III) will yield the same results.
- ARichtig
- BFalsch
31SS will be the same for two entries in all computation methods (Type I, II, III). Which two?
- Aerror (residual)
- Binteraction
- CFactor A
- DFactor B
- Etotal
32In the presence of significant interaction, the chosen method of SS is _________.
- Airrelevant
- Bcrucial
- Csomewhat important
33Which of these are ways to DIRECTLY interpret interaction in a Two-Factor ANOVA?
- Ainteraction contrasts
- Bsimple effects
- Ccorrelation
- Dregression
- Esum of squares
34Main effects for Factor A by this method can be interpreted as the main effect of Factor a controling or adjusting for Factor B and the interaction of Factor A x Factor B.
- AType I SS
- BType II SS
- CType III SS
35A major criticisim of this method is that the model does not respect marginality, and that it is generally wrong to interpretmain effects in the presence of an interaction.
- AType I SS
- BType II SS
- CType III SS
36In this method, SS for main effects are computed adjusting fo other main effects in the model, but omitting interaction terms.
- AType I SS
- BType II SS
- CType III SS
37In this method of SS computation, effects are adjusted only for the terms that appear "above" them in the ANOVA table.
- AType I SS
- BType II SS
- CType III SS
38A criticism of this SS computation method is that it produces different values for SS if we swap the ordering of the factors.
- AType I SS
- BType II SS
- CType III SS
39The null hypothesses associated with this method can be interpreted as the equcivalenc eof unweighted means without making further assumptions regarding the presence of interaction.
- AType I SS
- BType II SS
- CType III SS
40This method simplifies the testing of equality of equally weighted means if the interaction term is assumed to be zero.
- AType I SS
- BType II SS
- CType III SS
41If we can assume there's no interaction, the hypotheses for the Type I method become equivalent to Type III
- ARichtig
- BFalsch
42This method tests for equivalence of fully weighted means for the first variable entered into the model, and the null hypothesis for the second factor is the same as the Type II method.
- AType I
- BType III
43A criticisim for these methods of SS computation is that the null hypotheses are a function of sample size.
- AType I
- BType II
- CType III
44If ther is no interaction, this SS computation mehtod is the most powerful for an unbalanced design.
- AType I
- BType II
- CType III
45For most situations, power of the method of SS computation depends primarily on what?
- Astructure of the imbalance
- Bsample size
- Cmodel type
46Procedure for Aligned Rank Transform for a Two-Factor ANOVA
1. [blank_start]Align[blank_end] data [blank_start]seperately[blank_end] producing [blank_start]three[blank_end] different data sets
2. [blank_start]Rank aligned[blank_end] data [blank_start]all together[blank_end] [blank_start]within[blank_end] each of the [blank_start]three[blank_end] data sets
3. Replace original data with [blank_start]ranks[blank_end] [blank_start]within[blank_end] each of the [blank_start]three[blank_end] data sets
4. Run [blank_start]three[blank_end] [blank_start]separate[blank_end] [blank_start]Two-Factor[blank_end] ANOVAs on [blank_start]ranks[blank_end]- AAlign
- BRank
- CAverage
- Dseperately
- Eal together
- Fthree
- Gfive
- Hseven
- Ione
- JRank aligned
- KAlign ranked
- LAverage ranked
- MAverage aligned
- NAlign averaged
- ORank averaged
- Pall together
- Qseperately
- Rwithin
- Sbetween
- Tthree
- Uone
- Vfive
- Wseven
- Xranks
- Yaverage
- Zalignments
- AAwithin
- ABbetween
- ACthree
- ADone
- AEfive
- AFseven
- AGthree
- AHone
- AIfive
- AJseven
- AKseparate
- ALcombined
- AMTwo-Factor
- ANOne-Factor
- AOThree-Factor
- APranks
- AQaverages
- ARalignments
47A _______ is another version of a two-factor experiment, with one factor nesed within the second factor.
- ASplit-Plot design
- BNested design
- CRepeated Measures design
- DBlocked design
48Match the design types with the correct image.
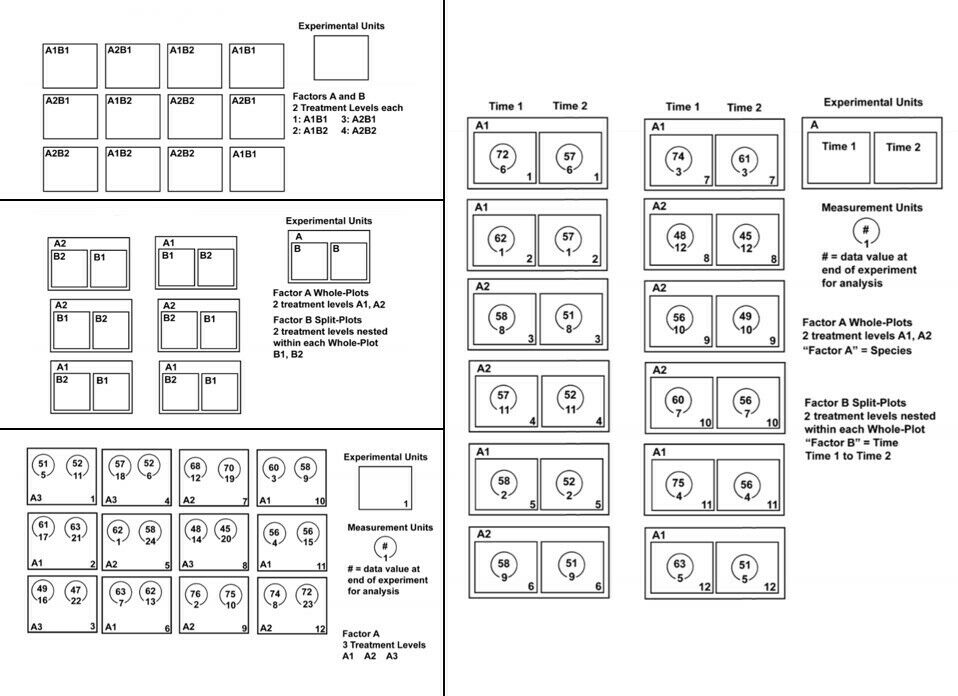
- ATwo-Way CRD
- BSplit-Plot design
- COne-Factor Nested design
- DRepeated Measures
49Procedure for Aligned Rank Transform for a Three-Factor ANOVA
1. [blank_start]Align[blank_end] data [blank_start]seperately[blank_end] producing [blank_start]three[blank_end] different data sets
2. [blank_start]Rank aligned[blank_end] data [blank_start]all together[blank_end] [blank_start]within[blank_end] each of the [blank_start]three[blank_end] data sets
3. Replace original data with [blank_start]ranks[blank_end] [blank_start]within[blank_end] each of the [blank_start]three[blank_end] data sets
4. Run [blank_start]three[blank_end] [blank_start]separate[blank_end] [blank_start]Two-Factor[blank_end] ANOVAs on [blank_start]ranks[blank_end]- AAlign
- BRank
- CAverage
- Dseperately
- Eall together
- Fthree
- Gone
- Hfive
- Iseven
- JRank aligned
- KAlign ranked
- LRank averaged
- MAlign averaged
- NAverage ranked
- OAverage aligned
- Pall together
- Qseparately
- Rwithin
- Sbetween
- Tthree
- Uone
- Vfive
- Wseven
- Xranks
- Yaverages
- Zalignments
- AAwithin
- ABbetween
- ACthree
- ADseven
- AEthree
- AFone
- AGfive
- AHseven
- AIseparate
- AJcombined
- AKTwo-Factor
- ALOne-Factor
- AMThree-Factor
- ANranks
- AOaverages
- APalignments
- AQfive
- ARone
50_____________ is a common technique for estimating coefficients of linear regression equations.
- AOrdinary Least Squares (OLS)
- BGeometric Mean Axis (GMA)
- CPearson Correlation Analysis
- DANVOA
- EANCOVA
51Linear regrassion equations describe the relationship beetween one or more [blank_start]independent[blank_end] [blank_start]quantitative[blank_end] variables and a [blank_start]dependent[blank_end] variable.
- Aindependent
- Bdependent
- Cquantitative
- Dqualitative
- Edependent
- Findependent
52What are the purposes of OLS?
(One-Factor ANOVA with x as independent variable and y as dependent variable)- AQuatify rate of change in y as x changes
- BQuantify value of y at x=0 (y-intercept)
- CPredict a y-value given x
- DQuantify rate of change in x as y changes
- EPredict an x-value given y
- FQuantify a value of x at y=0 (x-intercept)
53In which situations can OLS be used?
- Astraight lines
- Bcurved lines that can be transformed into straight lines
- Cquadratic lines
- Dcubic lines
- Es-shaped lines
54OLS assumes error in...
- Aonly the y-direction
- Bonly the x-direction
- Cin both the x and y direction
55Which line is the middle line of the data (Error in both the x and y direction)?
- ACentral Axis Line
- BGeometric Mean Axis (GMA)
- CReduced Major Axis
- DOrdinary Least Squares (OLS) Line
56The OLS method aims to minimize the [blank_start]sum of squre differences[blank_end] between the observed and predicted values.
- Asum of sqaure differences
- Bsum of differences
- Caverage difference
- Daverage error
- Esum of error terms
57The main question that OLS aims to answer is whether or not there is a treatment effect (presence or absence of change).
- ARichtig
- BFalsch
58[blank_start]Prediction Intervals[blank_end]: related to individual points in a dataset that was predicted mathematically.
[blank_start]Prediction Bands[blank_end]: related to the entire OLS line from the new dataset that was predicted mathematically
[blank_start]Confidence Intervals[blank_end]: related to individual points in the actual dataset
[blank_start]Confidence Bands[blank_end]: related to the entire OLS line from the new dataset that was predicted mathematically- APrediction Intervals
- BPrediction Bands
- CConfidence Intervals
- DConfidence Bands
59Steps of inverse prediction:
1. Measure the [blank_start]dependent[blank_end] variable ([blank_start]y[blank_end]) at known values of the [blank_start]independent[blank_end] variable ([blank_start]x[blank_end]).
2. Use these values to create a [blank_start]standard curve[blank_end] and find the regression equation
3. Rearrange the regression, isolating [blank_start]x[blank_end] on one side
4. Measure the unknown, finding the [blank_start]y-value[blank_end]
5. Plug the measurement into the rearranged equation to find the unknown value- Adependent
- Bindependent
- Cy
- Dx
- Eindependent
- Fdependent
- Gx
- Hy
- Istandard curve
- Jline of correlation
- Kcentral axis
- Lx
- My
- Ny-value
- Ox-value
60[blank_start]Interpolation[blank_end]: using the section of the OLS line bounded by the dataset for data prediction ([blank_start]good use of equation[blank_end])
[blank_start]Extrapolation[blank_end]: using sections of the OLS line not bounded by the dataset in order to complete data prediction ([blank_start]not recommended[blank_end])- AInterpolation
- BExtrapolation
- Cgood use of equation
- Dnot recommended
- EExtrapolation
- FInterpolation
- Gnot recommended
- Hgood use of equation
61Common Diagnostic Tests for OLS
[blank_start]Scatter Plot of Y vs X[blank_end]
-initial visual diagnostic
-may indicate [blank_start]non-linear patterns[blank_end]
r^2
-some information on the [blank_start]linear relationship between X and Y[blank_end]
-as a general rule, r^2 > [blank_start]0.95[blank_end] indicates a strong linear relationship
[blank_start]Durbin-Watson Test[blank_end]
-indication of [blank_start]autocorrelation[blank_end] or non-random error terms
-ranges from 0-4
- 2=[blank_start]low autocorrelation[blank_end], near 1 or 4 = [blank_start]high autocorrelation[blank_end]
[blank_start]Diagonal Elements of the hat matrix[blank_end]
-indication of X outlier
[blank_start]Studentized Residual[blank_end]
-examines patterns on scatter plot of Studentized Residual vs. X
-any pattern other than random indicates potential issues with [blank_start]linearity or HOV[blank_end]
[blank_start]Studentized Deletion REsidual[blank_end]
-large [blank_start]absolue alues[blank_end] indicate possible Y-outliers
-absolute SDR value in 2-3 range or greater indicate possible outlier
[blank_start]Cook's Distance[blank_end]
-large values indicate [blank_start]influential Y data point[blank_end] on linear equation
-percentiles greater than [blank_start]50[blank_end]% indicate overly influential data point. [blank_start]95[blank_end]% would be extreme.- AScatter Plot of Y vs X
- Bnon-linear patterns
- Clinear relationship between X and Y
- D0.95
- E0.50
- FDurbin-Watson Test
- Gautocorrelation
- Hlow autocorrelation
- Ihigh autocorrelation
- JDiagonal Elements of the hat matrix
- KStudentized Residual
- LStudentized Deletion Residual
- MCook's Distance
- Nlinearity or HOV
- Oabsolue values
- Ppercentiles
- Qaverages
- Rinfluential Y data point
- S50
- T95
62r^2 = [blank_start]1[blank_end] indicates a perfect line
r=[blank_start]1[blank_end] indicates perfect positive correlation
r=[blank_start]-1[blank_end] indicates perfect negative correlation
r=[blank_start]0[blank_end] indicates no correlation- A1
- B1
- C-1
- D0
63Transformation of X
--corrects non-linearity without changing [blank_start]variance[blank_end] and [blank_start]distribution of Y-values[blank_end]
Transformation of Y
--corrects non-linearity of [blank_start]relation between X and Y[blank_end]
--correct [blank_start]HOV[blank_end] and [blank_start]non-normal distribution of Y values[blank_end]
Transformation of both X and Y
--correct non-linearity [blank_start]imposed by transformations[blank_end] to fix other issues- Adistribution of Y-values
- Brelation between X and Y
- CHOV
- Dnon-normal distribution of Y values
- Evariance
- Fimposed by transformations
64[blank_start]Autoregressing Models[blank_end]
--regression taking [blank_start]autocorelation[blank_end] into account
--usually based on measuring things over time
[blank_start]Logistic Regression[blank_end]
--Regression of discrete categorical data ([blank_start]age, presence/absence[blank_end])
[blank_start]Curvilinear Regression[blank_end]
--fitting polynomial curves ([blank_start]cubic, quadratic, etc.[blank_end]
[blank_start]Nonlinear Regression[blank_end]
--fitting [blank_start]S-shaped curves[blank_end]
--commonly used for growth curves
[blank_start]Spline Regression[blank_end]
--using [blank_start]splines and knots[blank_end] to fit separate sections of complex patterns
--good for fit, not great for prediction
[blank_start]Multiple Regression[blank_end]
--similar to linear regression in many aspects, but more than one X variable
--uses [blank_start]dummy X matrix[blank_end]- AAutoregressing Models
- BLogistic Regression
- Cautocorelation
- DCurvilinear Regression
- Ecubic, quadratic, etc.
- FS-shaped curves
- GNonlinear Regression
- Hage, presence/absence
- ISpline Regression
- Jsplines and knots
- KMultiple Regression
- Ldummy X matrix
65ANCOVA is a full design.
- ARichtig
- BFalsch
66In ANCOVA, for each individual [blank_start]EU/MU[blank_end] [blank_start]a covariate[blank_end] is measured to account for variation other than the treatment effect.
- AEU/MU
- Bblock
- Cfactor
- Da covariate
- Ean additional factor
- Fan additional level
- Ga block
67ANCOVA can be applied to any design, including designs that also have blocking
- ARichtig
- BFalsch
68ANCOVA is primarily utilized for what purpose?
- Aremove background variation
- Badd an additional level of analysis
- Corder factors by importance
69What is the null hypothesis of ANCOVA?
- AThe adjusted means of columns are equal
- BThe means of columns are equal
- CThe observed frequency is equal to the expected frequency
- DThe means of columns and rows are equal
- EThere is no correlation between X and Y
70What is the null hypothesis of Goodness of Fit?
- AThe adjusted means of columns are equal
- BThe means of columns are equal
- CThe observed frequency is equal to the expected frequency
- DThe means of columns and rows are equal
- EThere is no correlation between X and Y
71What is the null hypothesis of linear correlation?
- AThe adjusted means of columns are equal
- BThe means of columns are equal
- CThe observed frequency is equal to the expected frequency
- DThe means of columns and rows are equal
- EThere is no correlation between X and Y
72What are the assumptions for Y (data) for using a covariate in a One-Factor CRD?
- AData points within each column are from randomly drawn individuals and are normaly distributed
- BData points are independent of one another within and between columns
- CVariances of columns are similar
- Dindependent of treatment effect
- Eno error in measuring
- FX and Y form a linear relationship for all treatment groups
- Gslopes of regression lines are similar for all treatment groups
73What are the assumptions for X (covariate) for using a covariate in a One-Factor CRD?
- AData points within each column are from randomly drawn individuals and are normaly distributed
- BData points are independent of one another within and between columns
- CVariances of columns are similar
- Dindependent of treatment effect
- Eno error in measuring
- FX and Y form a linear relationship for all treatment groups
- Gslopes of regression lines are similar for all treatment groups
74What are the assumptions for X and Y for using a covariate in a One-Factor CRD?
- AData points within each column are from randomly drawn individuals and are normaly distributed
- BData points are independent of one another within and between columns
- CVariances of columns are similar
- Dindependent of treatment effect
- Eno error in measuring
- FX and Y form a linear relationship for all treatment groups
- Gslopes of regression lines are similar for all treatment groups
75What is the main purpose for linear correlation?
- ADetermine correlation of two measures.
- BDetermine linear relationship between two measures
- CRemove background variation
76What are the assumptions of Pearson's Correlation?
- AThe X and Y pairs of data points are from randomly drawn individuals that are independent of one another
- BX and Y are normally distributed
- CX and Y form a linear relationship
- DHOV between data pairs
77What are the assumptions of Spearman Non-Parametric Correlation?
- AThe X and Y pairs of data points are from randomly drawn individuals that are independent of one another
- BX and Y are normally distributed
- CX and Y form a linear relationship
- DHOV between data pairs
78[blank_start]r[blank_end] = Pearson correlation coefficient
[blank_start]r^2[blank_end] = coefficient of determination- Ar^2
- Br
79[blank_start]OLS[blank_end] lines are used for prediction
[blank_start]Central Axis[blank_end] lines are used for function- AOLS
- BCentral Axis
80In a t-test of the correlation coefficient, the null hypothesis is [blank_start]r = rho = 0[blank_end]. For a two-tailed test, t follows the [blank_start]t[blank_end]-distribution with v degrees of freedom.
- Ar = rho = 0
- Br^2 = rho = 0
- Cr = rho <> 0
- Dr^2 = rho <> 0
- Er1 = r2
- Ft
- GDurbin-Watson
- Hr
- Ix^2
- JG
81z and z* transforms and the z-test of the correlation coefficient is used for testing which null hypotheses?
- Ar = rho <> 0
- Br^2 = rho <> 0
- Cr = rho = 0
- Dr^2 = rho = 0
- Er1 = r2
- Fbasically, when the null hypothesis is that r is not equal to 0
- Gbasically, when the null hypothesis is that r is equal to 0
82Which is one of the best non-parametric procedures for testing correlation?
- ASpearman
- BPearson's
- CDurbin-Watson
- DCook's Distance
83The Spearman Non-Parametric procedures of determining correlation is often used by default because it doesn't rely on normality or linearity, but still gives reliable conclusions.
- ARichtig
- BFalsch
84Analysis of Frequency/Count data relies on the testing of ___________ and ____________.
- Aobserved frequencies
- Bexpected frequencies
- Ccorrelation coefficients
- Dt-values
- Eassigned values
85What count-data design(s) can be analyzed with Goodness of Fit?
- AOne-way
- BTwo-way
- CThree-way
- DFour-way
86What count-data design(s) can be analyzed with Contingency Tables?
- AOne-way
- BTwo-way
- CThree-way
- DFour-way
87What is the null hypothesis for Goodness of Fit?
- Aobserved frequency = expected frequency
- Btwo-way classification factors are independent of each other
- Cr = rho = 0
- Dhomogeneity across all tests
88What is the null hypothesis for Contingency Tables?
- Aobserved frequency = expected frequency
- Btwo-way classification factors are independent of each other
- Cr = rho = 0
- Dhomogeneity across all tests
89What is the null hypothesis for Homogeneity Log-likelihood tests??
- Aobserved frequency = expected frequency
- Btwo-way classification factors are independent of each other
- Cr = rho = 0
- Dhomogeneity across all tests
90What are the assumptions for Goodness of Fit?
- ACounts are independent of each other
- BExpected frequencies are postulated before counts are made
- CDesireable to have a total count > 25
- DDesireable to have expected frequencies > 5
- EDesireable to have a total count > 6x the number of cells
- FData is additive
- GData is multiplicative
- HCounts are normally distributed
- IHOV
91What are the assumptions for Contingency Tables?
- ACounts are independent of each other
- BExpected frequencies are postulated before counts are made
- CDesireable to have a total count > 25
- DDesireable to have expected frequencies > 5
- EDesireable to have a total count > 6x the number of cells
- FData is additive
- GData is multiplicative
- HCounts are normally distributed
- IHOV
92Chi-squared test uses [blank_start]x^2[blank_end] statistic, which follows the [blank_start]x^2[blank_end] distribution table with v degrees of freedom.
Log-likelihood test uses the [blank_start]G[blank_end] statistic, which follows the [blank_start]x^2[blank_end] distribution table with v degrees of freedom.- Ax^2
- Bt
- CG
- DD
- Ex^2
- Ft
- GG
- HD
- Iz
- Jz
- KG
- Lx^2
- Mt
- ND
- Oz
- Px^2
- QG
- RD
- St
- Tz
93Heterogeneitiy Log-Likelihood Tests analyze [blank_start]correlation[blank_end] by combining [blank_start]Goodness of Fit[blank_end] tests.
- Acorrelation
- Blinear regression
- CGoodness of Fit
- DContingency Table
- EANOVA
- FANCOVA
94If the heterogeneity G test does not reject the null hypothesis of homogeneity across all tests, the [blank_start]Pooled G[blank_end] test is a legitimate test of adding the counts of all tests together for a combined test with a larger number of counts.
- APooled G
- BChi-squared
- CLog-likelihood
- DDurbin-Watson
95The purpose of this test is to add counts of multiple Godness-of-fit tests for a combined test with a larger number of counts.
- APooled G
- BHeterogeneity G
- CGoodness of Fit
- DContingency Table
96The purpose of this test is to test for homogeneity of goodness-of-fit tests (log-likelihood), particularly before a Pooled G test.
- APooled G
- BHeterogeneity G
- CGoodness of Fit
- DContingency Table
97Contingency tables can have marginal totals that are either fixed or not fixed.
[blank_start]Both fixed[blank_end] ([blank_start]very rare[blank_end])
Control totals of both factors, but not counts of each cell
In other words: control ratio between rows/columns, but not ratios of counts within each row/column
[blank_start]Both margins not fixed[blank_end] (common)
Don't control totals of each row/column, only the total N
In other words: don't control any ratios
[blank_start]One margin fixed, one margin not[blank_end] ([blank_start]common[blank_end])
Control totals of one facor (rows OR columns), but not the other.
In other words: control the ratio of either rows OR columns, but not the other.- AOne margin fixed, one margin not
- BBoth margins not fixed
- CBoth fixed
- Dvery rare
- Ecommon
Informationen
- Beschreibung
- Master's Statistics Quiz am Experimental Design Test 3, erstellt von Jo O'Bar am 31/10/2022.
- Autor
- Jo O'Bar
- Sprache
- English
- Aufrufe
- 34
- Schlagwörter
- Bewertung
- Noch keine Bewertungen Bewerte dieses Quiz