
Flashcards
QUERY PROCESSING AND OPTIMISATION
Cards in this deck (37)
- 1Why query processing problem is much more difficult in distributed environments than in centralized ones?Because relations involved in a distributed query may be fragmented and/or replicated, and has many
sites to access - 2High level user query converted into lowlevel data manipulation command for DDBMS by?Query processor maps a high-level query (assumed to be expressed in
relational calculus) on a distributed database (i.e., a set of global relations) into a sequence of database
operators (of relational algebra) on relation fragments - 3some main operations involved in the query?SELECT; JOIN; PROJECT; UNION, INTERSECTION, SET DIFFERENCE,
CARTESIAN PRODUCT - 4operations can be implemented using one or more different Access Routines such as ?SELECT some attributes : - full table scan, linear scan,
hash key, and binary search
Possible JOIN methods: - nested loop, hash join, and sort-merge - 5SELECT operation is denoted by?σ ()
three selection conditions: single, conjunctive (AND), and disjunctive (OR) - 6JOIN operation on two relations R(A1,A2,…An) and S(B1,B2,…Bm) is denoted by?R ⋈ A=B S
where A and B are domain-compatible attributes of R and S, respectively - 7Draw back of Join operation?The JOIN operation is one of the most time-consuming operations in query processing, which have
different types, such like EQUIJOIN, NATURAL JOIN, and SEMIJOIN - 8Difference between EquiJoin and Natural Join?1. syntax and result slightly diff :
eg.
select * from a,b where a.x=b.y;
--Equijoin wil have x column repeated 2 times from both tables.
select * from a natural join b;
same as equijoin but same columns willl not be repeated. - 9Difference between Equi-Join and Semi-Join?Semijoins use the EXISTS or IN constructs. In semi join, we first take equijoin of two relations and then
find matched rows of first relation only, thus the resulting relation has attributes of first relation only.
eg. syntax
select * from titleauthors where exists (select * from authors where authors.au_id=titleauthors.au_id and au_name="abc"); - 10PROJECT operation is donated by?π(R)
where the is a subset of the attributes of a relation by specifying the names. For example,
Select stud_id, stud_fname, stud_lname from students - 11difference between project and select operation?Project selects subset of columns while select operation selects rows depending on a predicate condition.
- 12Consider two relations, R and S, which can be combined in a number of different ways to produce another set, there are four basic Set operations. What are they?UNION,
INTERSECTION, DIFFERENCE, and Cartesian product - 13What is Union set operation?R ∪ S
UNION of relations t1 and t2 returns all the tuples (rows) of the
two relations. Note that tuples are not repeated in a set .
Union compatible if R and S have the same number of attributes, and the
domain of each attribute in column order is the same - 14What is INTERSECTION op?R ∩ S It results in the set of tuples that are in both R
and S. - 15What is DIFFERENCE op?donated by R - S, results in the set of tuples that are in R but not
in S - 16What is CARTESIAN op?R X S combines the tuples of R with all the tuples of S.
of relations t1 and t2 joins every row from t1 with every row from t2, therefore, the
total number of rows of the resulting set is the product of the number of rows in t1 and the number of
rows in t2, which is a quite expensive result. - 17Issues dealt by query processor are?1. select the execution strategy that
minimizes resource consumption
2.Besides the choice of ordering
relational algebra operators,
3.the distributed query processor must also select the best sites to process
data, and possibly the way data should be transformed. - 18How would we choose between 2 strategies for executing a distributed query?assume cost of accessing and transfering tuples , calculate total cost for each strategy and choose. Also consider distribution of work among sites. Also for the actual high level query's multiple correct transformation we should consider the one which is least expensive in resource consumption (eg. cartesian products should be avoided). resources are CPU , I/o , comm cost.
- 19What are different type of optimizers?Exhaustive search:
search the solution space, exhaustively predict the cost
of each strategy, and select the strategy with minimum cost
Heuristics:
use of heuristics, whose effect is to
restrict the solution space so that only a few strategies are considered, which does not guarantee the
strategy is optimal - 20What are different examples of heuristics?regrouping common sub-expressions;
performing selection, projection first;
replacing join by a series of semijoins to minimise data communication;
reordering operations to reduce intermediate relation size;
and optimising individual operations - 21when and why to use semi join to optimize?It reduces the data to be transfered when using joins.
Use it when
size (πA
(S)) + size (R ⋉A
S') < size (R)
To use it we first transfer project of common attribute then perform semi join and take the result to join. - 22When can query be optimized?statically before executing the query at compilation time or dynamically as the query is executed at runtime.
- 23Pros and cons of static optimization and dynamic opt?Static opt - Pro - cost of optimisation may be amortized over multiple query executions.
appropriate for use with the exhaustive search method.
Con -difficult to estimate the sizes of the
intermediate results until run time
Dynamic opt- pro - exact information on the intermediate relation sizes known - minimizing probability of bad choice
Con- must be repeated for multiple executions
Best for ad-hoc queries - 24What is hybrid Query opt?The approach is basically static, which compiles using a
static algorithm, but dynamic query optimisation may take place at run time if the error in estimate sizes
> threshold. - 25What problem related to site does static opt involves?making decision of strategy to optimize.
It can be centralized or distributed or hybrid.
centralized - single site determines the "best"
schedule - requires knowledge about the entire distributed
database
distributed -cooperation among sites to determine the schedule thus incurs cost of cooperation
- requires only local information
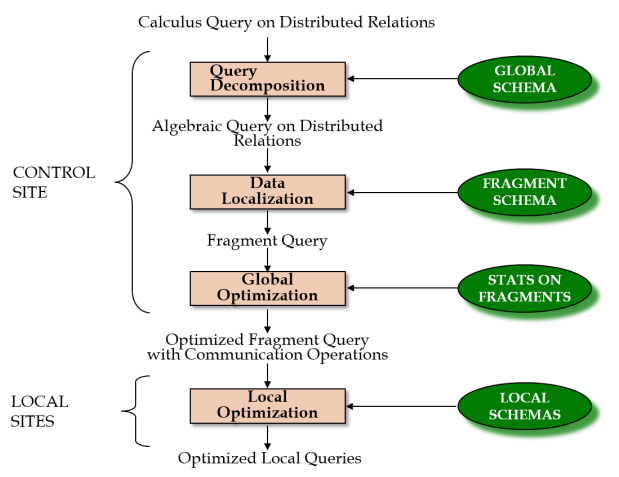
Hybrid -one site determines the global schedule and each site optimizes the local subqueries. - 26How does query processing methodology work?The input is a query on global data expressed in relational calculus. Four main layers are involved in
distributed query processing. The first three layers map the input query into an optimized distributed
query execution plan, which are performed by a central control site and use schema information stored in
the global directory. They perform the functions of query decomposition, data localization, and global
query optimization. The fourth layer performs distributed query execution by executing the plan and
returns the answer to the query. It is done by the local sites and the control site. - 27How is query normalized in query decomposition process?Normalization of a query generally involves the manipulation of the query quantifiers and of the query
qualification by applying logical operator priority. Two possible normal forms for the predicate, one giving precedence to the AND (^) (conjunctive normal form
(p11∨ p12 ∨ … ∨ p1n
) ^ … ^ (pm1
∨ pm2
∨ … ∨ pmn))and the
other to the OR (∨) (disjunctive normal form (p11 ^ p12 ^ … ^ p1n
) ∨ … ∨ (pm1
^ pm2
^ … ^ pmn)
) - 28What happens in analysis phase of query decomposition process?analysed semantically so that "incorrect" queries are detected and rejected as
early as possible (only a subset of
relational calculus queries can be tested for correctness).some sort of graph that captures the semantics of the query is used. To detect the correctness, the
representation of the query as a graph, called a connection graph (query graph) is required. Also type incorrect are rejected( if any of its attribute or relation names are not defined in the global schema, or
if operations are being applied to attributes of the wrong type. ) .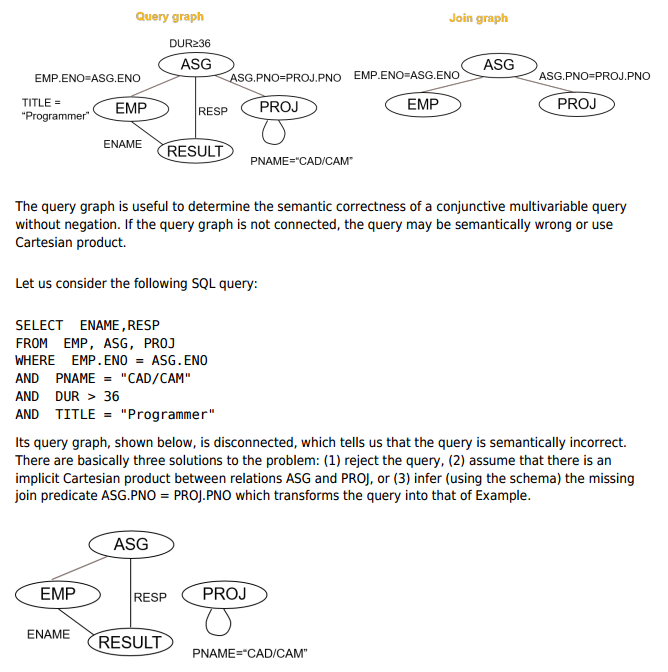
- 29What happens in simplification phase of query decomposition process?The correct query (still expressed in relational calculus) is simplified by eliminating redundant predicates.Note that redundant queries are likely to arise when a query is the result
of system transformations applied to the user query.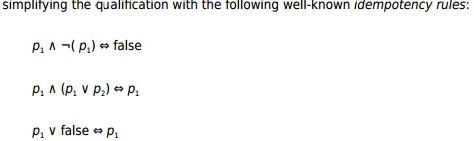
- 30What happens in Restructuring phase of query decomposition process?The calculus query is restructured as an algebraic query through transformation rules. Recall from the
optimisation example that several algebraic queries can be derived from the same calculus query, and
more than one translation is possible.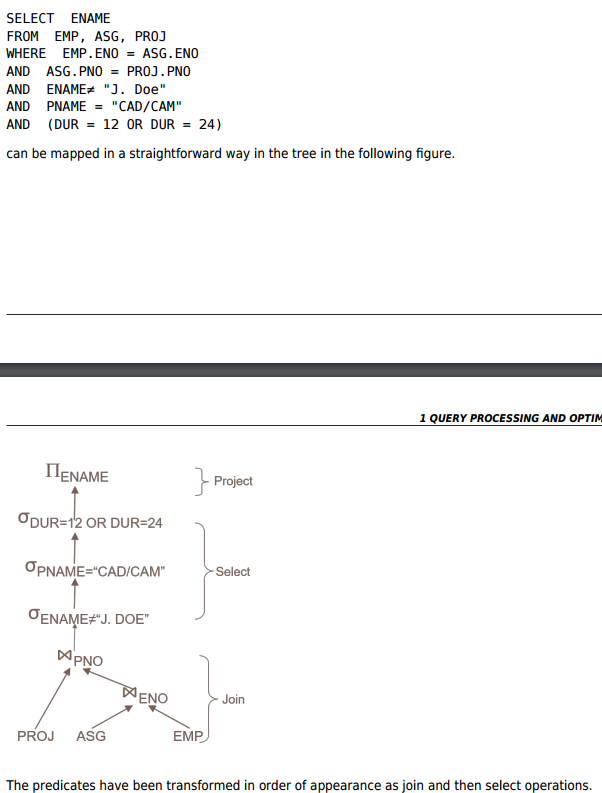
- 31What are the Restructuring -Transformation Rules?1. Commutativity of binary operators. The Cartesian product of two relations R and S is commutative:
R × S ⇔ S × R
2. Associativity of binary operators. The Cartesian product and the join are associative operators:
( R × S) × T ⇔ R × (S × T)
3. Idempotence of unary operators. Several subsequent projections on the same relation may be
grouped eg.
σp1(A1)(σp2(A2)(R)) ⇔ σp1(A1)∧p2(A2)(R)
4. Commuting selection with projection. Selection and projection on the same relation can be
commuted as follows:
∏A1,…,An(σp(Ap)(R)) ⇔ ∏A1,…,An (σp(Ap) (∏A1,…,An,Ap (R))) - 32What happens in the data localization phase of query optimization methodology?The input to the second layer is an algebraic query on global (distributed) relations. The main role of the
second layer is to localize the query's data using data distribution information in the fragment schema. It transforms the distributed query
into a query on fragments which defined by fragmentation predicates that can be expressed
through relational operators.
First, the query is mapped into a fragment query by substituting each global query by its materialization
program (also called materialization program), discussed in Chapter 3 (we have covered this chapter in
week 1 module: DISTRIBUTED DATABASE DESIGN).
Second, the fragment query is optimised (simplified and restructured) to produce another "good" query.
Simplification and restructuring may be done according to the same rules used in the decomposition
layer.
For horizontal fragmentation, the localization program is the UNION of fragments, while for vertical
fragmentation the localization program is the JOIN of the fragments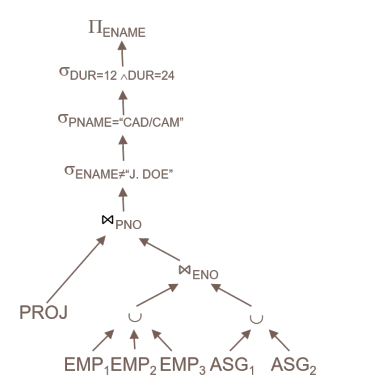
- 33What is data localization reduction for PHF?Reduction on selections : -
Selections on fragments can generate empty relation
Reduction with Join - Useless joins of fragments can be determined when the qualifications of the
joined fragments are contradicting, thus yielding an empty result. Joins on horizontally fragmented relations can be simplified by distributing joins over unions and eliminating
useless joins.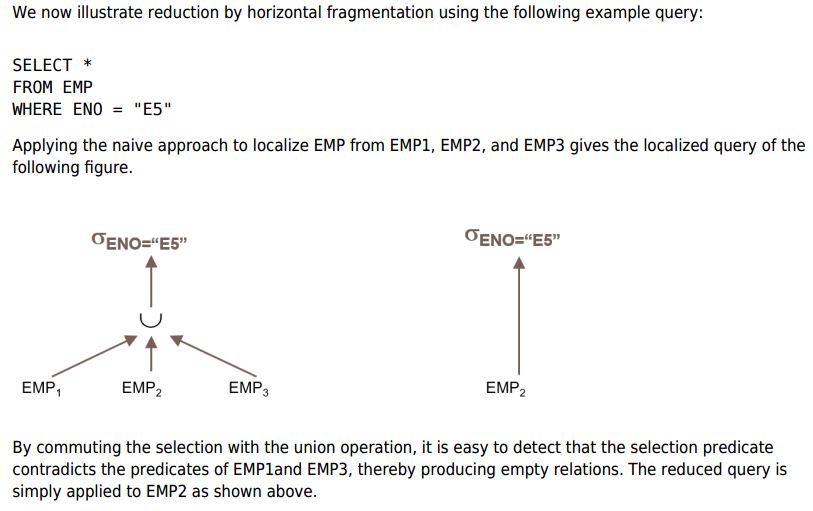
- 34How is reduction in data localization with joins with PHF done?
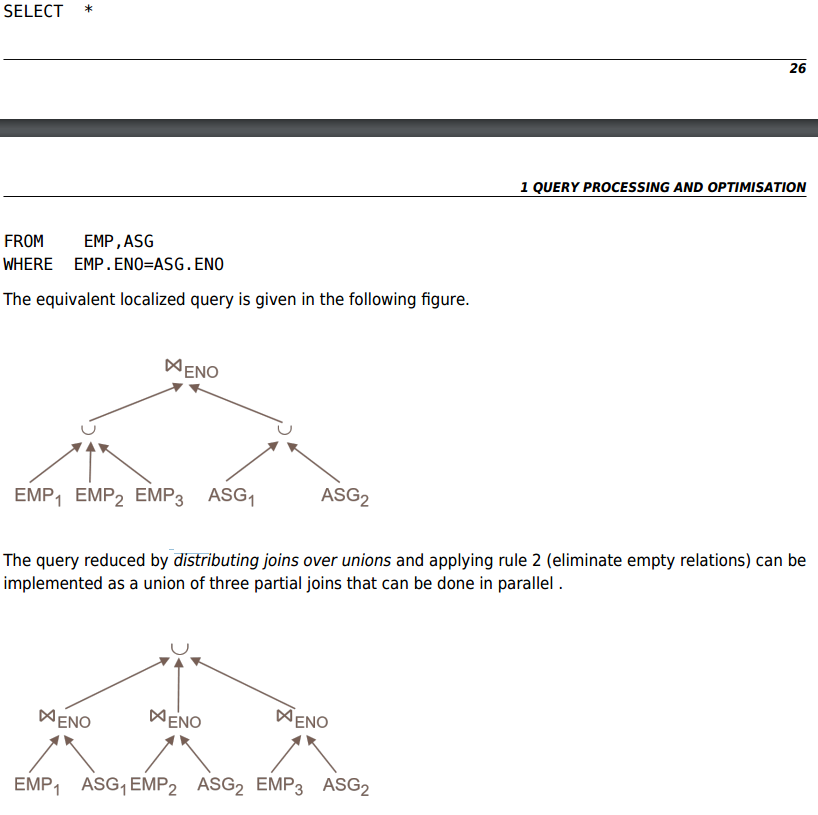
- 35How is reduction in data localization with joins with DHF done?There are two rules that can be applied to implement reduction for derived horizontal fragmentation:
distribute joins over union, and apply the join reduction for horizontal fragmentation.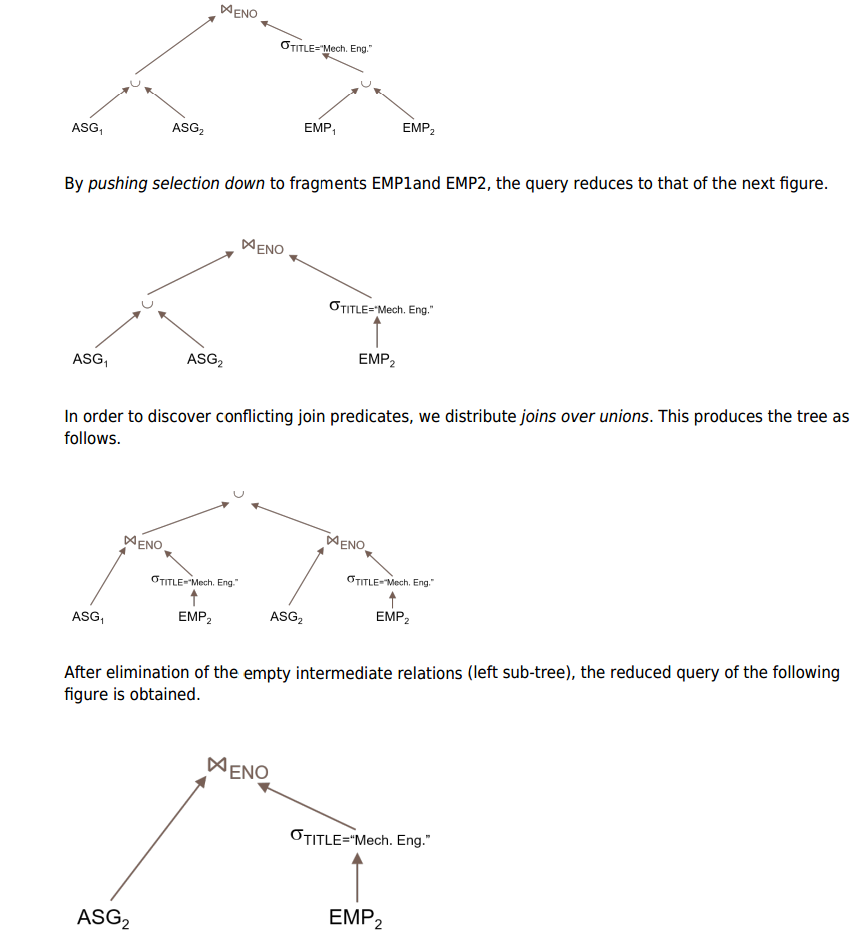
- 36How is reduction in data localization with joins with VF done?Similar to horizontal fragmentation, queries on vertical fragments can be reduced by determining the
useless (not empty) intermediate relations and removing the subtrees that produce them.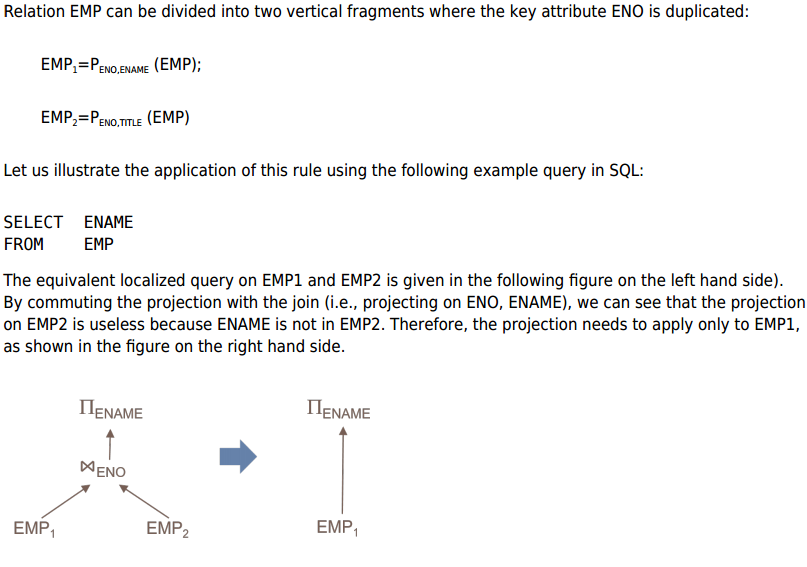
- 37How is reduction in data localization with joins with HF done?Hybrid fragmentation is obtained by combining the fragmentation functions discussed
above:
1. Remove empty relations generated by contradicting selections on horizontal fragments;
2. Remove useless relations generated by projections on vertical fragments;
3. Distribute joins over unions in order to isolate and remove useless joins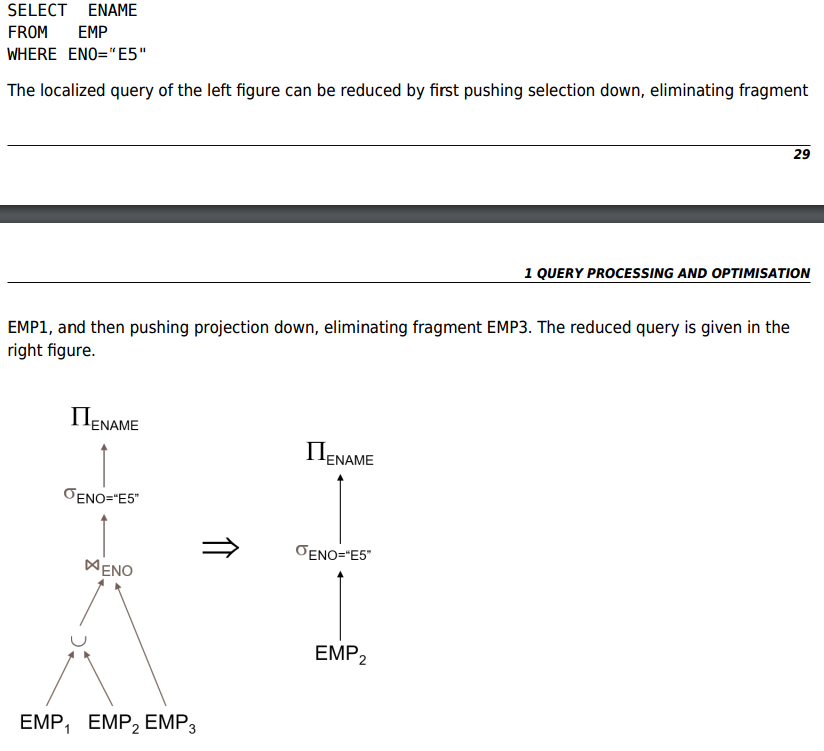
Information
- Description
- Distributed Database Flashcards on QUERY PROCESSING AND OPTIMISATION, created by Varun m on 29/05/2017.
- Created by
- Varun m
- Views
- 0
- Rating