
Mindmap
Hadoop Basic
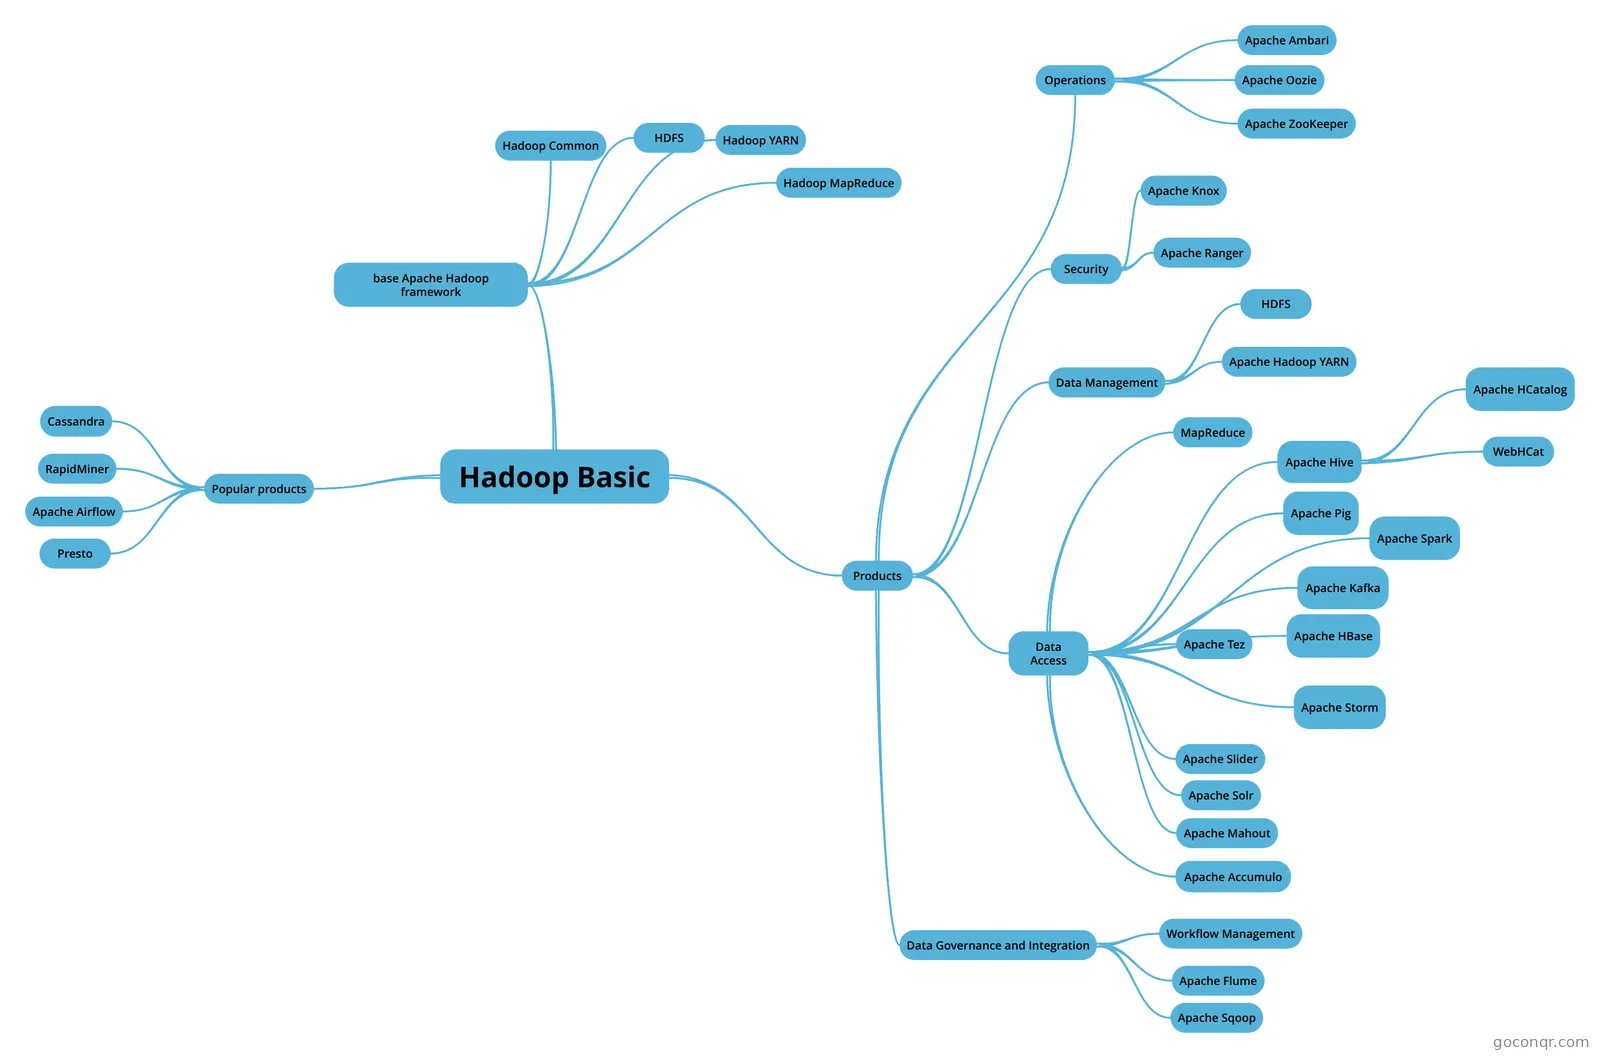
Mind map: Hadoop basic
Inhalt der Mindmap
Hadoop Basic
base Apache Hadoop framework
- Hadoop Common
- HDFS
- Hadoop YARN
- Hadoop MapReduce
Products
- Data Management
- HDFS
- Hadoop Distributed File System (HDFS) is a Java-based file system that provides scalable and reliable data storage that is designed to span large clusters of commodity servers.
- Apache Hadoop YARN
- Part of the core Hadoop project, YARN is a next-generation framework for Hadoop data processing extending MapReduce capabilities by supporting non-MapReduce workloads associated with other programming models.
- HDFS
- Data Access
- Apache Hive
- Built on the MapReduce framework, Hive is a data warehouse that enables easy data summarization and ad-hoc queries via an SQL-like interface for large datasets stored in HDFS.
- Apache HCatalog
- is a component of Hive. It is a table and storage management layer for Hadoop that enables users with different data processing tools — including Pig and MapReduce — to more easily read and write data on the grid. A table and metadata management service that provides a centralized way for data processing systems to understand the structure and location of the data stored within Apache Hadoop.
- WebHCat
- provides a service that you can use to run Hadoop MapReduce (or YARN), Pig, Hive jobs. You can also perform Hive metadata operations using an HTTP (REST style) interface.
- Apache Pig
- A platform for processing and analyzing large data sets. Pig consists of a high-level language (Pig Latin) for expressing data analysis programs paired with the MapReduce framework for processing these programs.
- MapReduce
- MapReduce is a framework for writing applications that process large amounts of structured and unstructured data in parallel across a cluster of thousands of machines, in a reliable and fault-tolerant manner.
- Apache Spark
- Spark is ideal for in-memory data processing. It allows data scientists to implement fast, iterative algorithms for advanced analytics such as clustering and classification of datasets.
- Apache Storm
- torm is a distributed real-time computation system for processing fast, large streams of data adding reliable real-time data processing capabilities to Apache Hadoop 2.x
- Apache HBase
- A column-oriented NoSQL data storage system that provides random real-time read/write access to big data for user applications.
- Apache Tez
- Tez generalizes the MapReduce paradigm to a more powerful framework for executing a complex DAG (directed acyclic graph) of tasks for near real-time big data processing.
- Apache Kafka
- Kafka is a fast and scalable publish-subscribe messaging system that is often used in place of traditional message brokers because of its higher throughput, replication, and fault tolerance.
- Apache Slider
- A framework for deployment of long-running data access applications in Hadoop. Slider leverages YARN’s resource management capabilities to deploy those applications, to manage their lifecycles and scale them up or down.
- Apache Solr
- Solr is the open source platform for searches of data stored in Hadoop. Solr enables powerful full-text search and near real-time indexing on many of the world’s largest Internet sites.
- Apache Mahout
- Mahout provides scalable machine learning algorithms for Hadoop which aids with data science for clustering, classification and batch based collaborative filtering.
- Apache Accumulo
- Accumulo is a high performance data storage and retrieval system with cell-level access control. It is a scalable implementation of Google’s Big Table design that works on top of Apache Hadoop and Apache ZooKeeper.
- Apache Hive
- Data Governance and Integration
- Workflow Management
- Workflow Manager allows you to easily create and schedule workflows and monitor workflow jobs. It is based on the Apache Oozie workflow engine that allows users to connect and automate the execution of big data processing tasks into a defined workflow.
- Apache Flume
- Flume allows you to efficiently aggregate and move large amounts of log data from many different sources to Hadoop.
- Apache Sqoop
- Sqoop is a tool that speeds and eases movement of data in and out of Hadoop. It provides a reliable parallel load for various, popular enterprise data sources.
- Workflow Management
- Security
- Apache Knox
- The Knox Gateway (“Knox”) provides a single point of authentication and access for Apache Hadoop services in a cluster. The goal of the project is to simplify Hadoop security for users who access the cluster data and execute jobs, and for operators who control access to the cluster.
- Apache Ranger
- Apache Ranger delivers a comprehensive approach to security for a Hadoop cluster. It provides central security policy administration across the core enterprise security requirements of authorization, accounting and data protection.
- Apache Knox
- Operations
- Apache Ambari
- An open source installation lifecycle management, administration and monitoring system for Apache Hadoop clusters.
- Apache Oozie
- Oozie Java Web application used to schedule Apache Hadoop jobs. Oozie combines multiple jobs sequentially into one logical unit of work.
- Apache ZooKeeper
- A highly available system for coordinating distributed processes. Distributed applications use ZooKeeper to store and mediate updates to important configuration information.
- Apache Ambari
- Data Management
Popular products
- Cassandra
- Apache Cassandra is a distributed type database to manage a large set of data across the servers. This is one of the best big data tools that mainly processes structured data sets. It provides highly available service with no single point of failure. Additionally, it has certain capabilities which no other relational database and any NoSQL database can provide. These capabilities are:
- RapidMiner
- RapidMiner is a software platform for data science activities and provides an integrated environment
- Apache Airflow
- Presto
- Cassandra
Informationen
- Beschreibung
- Big Data Mindmap am Hadoop Basic, erstellt von ray ma am 18/03/2019.
- Erstellt von
- ray ma
- Aufrufe
- 2
- Bewertung
Mehr zu Hadoop Architecture and Ecosystem