
Mind map
reinforcement learning workshop
Map content
reinforcement learning workshop
resources
- video
- kjfalkdjf asdfasdf
- book
- slide
- code snip
- github summary
- Lectures [UCL] COMPM050/COMPGI13 Reinforcement Learning by David Silver [UC Berkeley] CS188 Artificial Intelligence by Pieter Abbeel Lecture 8: Markov Decision Processes 1 Lecture 9: Markov Decision Processes 2 Lecture 10: Reinforcement Learning 1 Lecture 11: Reinforcement Learning 2 [Udacity (Georgia Tech.)] CS7642 Reinforcement Learning [Stanford] CS229 Machine Learning - Lecture 16: Reinforcement Learning by Andrew Ng [UC Berkeley] Deep RL Bootcamp [UC Berkeley] CS294 Deep Reinforcement Learning by John Schulman and Pieter Abbeel [CMU] 10703: Deep Reinforcement Learning and Control, Spring 2017 [MIT] 6.S094: Deep Learning for Self-Driving Cars Lecture 2: Deep Reinforcement Learning for Motion Planning [Siraj Raval]: Introduction to AI for Video Games (Reinforcement Learning Video Series) [Introduction to AI for video games] (https://youtu.be/i_McNBDP9Qs) [Monte Carlo Prediction] (https://youtu.be/-YpalutQCKw) [Q learning explained] (https://youtu.be/aCEvtRtNO-M) [Solving the basic g
- video
traditional content
- tabular solution method
- basic root of RL (model based)
- MDP
- 1.policy PI and value f(x),v(s), Q(s,a)
- 2.bellman equation
- Dynamic Process
- 1.iterative policy evaluation
- 2.policy improvement
- 3.policy iteration
- 4. value iteration
- 3.policy iteration
- 2.policy improvement
- 1.iterative policy evaluation
- MDP
- model free sampler
- Monte carlo
- 1. MC prediction and control methods
- 2. greedy and epsilon-greedy policies
- 3. Exploration-Exploitation Dilemma
- temporal Difference
- 1. sarsa small kid
- 2. Q-learning big kid
- Expected Sarsa algorithms
- N-step Bootsrappin
- TD(0),,,,TD(Lmda)
- planing and learning with tabular methods
- Monte carlo
- basic root of RL (model based)
- approximate solution method
- on-policy
- on-policy prediction with Approximation
- on-policy control
- off-policy
- eligible trace
- Policy Gradient Method
- PG theorem
- MC policy Gradient
- Actor-Critic, A2C, A3c
- on-policy
- tabular solution method
Core concept compare
- online vs offline
- on-policy vs off-policy
- model-based vs model free vs
Programing Environment
- Gym
value-based method
Policy-based method
basic key words
- states and observations,
- action spaces
- continue vs discrete
- policies PI
- trajectories
- different formulations of return
- the RL optimization problem
- value functions.
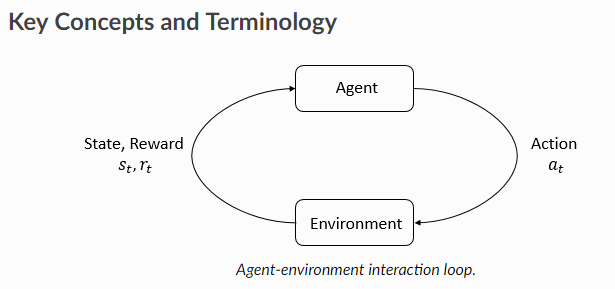
- environment
- agent
Images and files in the map
Information
- Description
- Mind Map on reinforcement learning workshop, created by W Jh on 02/11/2018.
- Created by
- W Jh
- Views
- 0
- Rating