
Mind map
Machine Learning
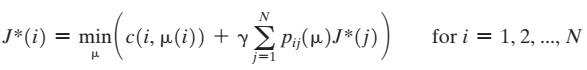
Map content
Machine Learning
With a Teacher (supervised)
- A "cognitive" learning problem. It relies on the availability of an adequate set of input–output examples that are representative of the operating environment.
Without a Teacher (unsupervised)
- Self Organized
- Reinforcement Learning
- A "behavioral" learning problem. Interaction between an agent and its environment.
- Classical Approach
- Punishment and reward. The goal of achieving highly skilled behavior.
- Dynamic Programming (Modern Approach)
- It builds on a mathematical technique known as dynamic programming to decide on a course of action by considering possible future stages without actually experiencing them; the emphasis here is on planning.
- Dynamic programming is a technique that deals with situations where decisions are made in stages, with the outcome of each decision being predictable to some extent before the next decision is made.
- Efficient trade-off between immediate and future costs.
- Decision making by an agent that operates in a stochastic environment.
- Markov Decision Processes (X, U, P, R)
- Given the initial state of a dynamic system, a Markov decision process provides the mathematical basis for choosing a sequence of decisions that will maximize the returns from an N-stage decision-making process.
- X is a set of states
- U is a set of actions or controls
- P=Pr{x'|x, u}
- R is the cost function
- Markov Decision Processes (X, U, P, R)
- The Basic-Problem
- Finite-horizon
- The cost accumulates over a finite number of stages.
- Infinite-horizon
- The cost accumulates over an infinite number of stages. Infinite-horizon problems provide a reasonable approximation to problems involving a finite, but very large, number of stages. They are also of particular interest because discounting ensures that the costs for all states are finite for any policy.
- Finite-horizon
- Bellman's Optmality Criterion
- An optimal policy has the property that whatever the initial state and initial decision are, the remaining decisions must constitute an optimal policy starting from the state resulting from the first decision.
- Decision: A choice of control at a particular time
- Policy: The entire control sequence or control function
- Bellman's Optimality Equation
- It represents a system of N equations with one equation per state. The solution of this system of equations defines the value of the optimal cost-to-go function for the N states of the environment. There are two basic methods for computing an optimal policy. They are called policy iteration and value iteration.
- Policy Iteration
- The algorithm (also known as actor–critic architecture) operates by alternating between two steps: 1. a policy evaluation step, in which the cost-to-go function for some current policy and the corresponding Q-factor are computed for all states and actions; 2. a policy improvement step, in which the current policy is updated in order to be greedy with respect to the cost-to-go function computed in step 1.
- Value Iteration
- Based on successive approximations. Value iteration requires an infinite number of iterations.
Images and files in the map
Information
- Description
- Engenharia Mind Map on Machine Learning, created by ANTONIO BARROS FEITOSA JÚNIOR on 10/08/2020.
- Created by
- ANTONIO BARROS FEITOSA JÚNIOR · Aug 2020
- Updated
- Aug 14, 2020
- Views
- 5
- Rating