
Flashcards
ai
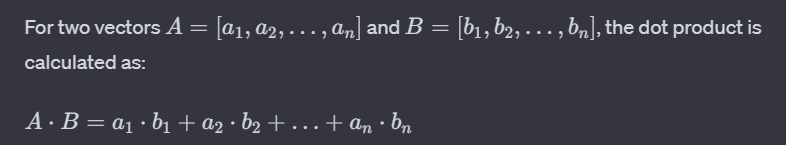
Flashcards do conjunto (37)
- 1Zfunction for linear combination of inputs/weights/bias
- 2sigmoidfunction that converts Z into -1,0,1
- 3tanh/relu/leaky relulike sigmoid function, it converts Z into -1,0,1.
- 4RNNrecurrent neural network that is based on the order of sequence of data - used on data like speech, or music
- 5weightparameter that represents strength of one neuron to another
- 6cost function/loss function/objective functionmeasures difference between predicted output and true output
- 7back propagationalgorithm used to minimize cost function CALCULATES gradients (partial derivatives). It is a step in optimization.
- 8n^[l]subscript_(h)n = neuron
l = layer
h = specific neuron in lth layer - 9Xinput data matrix
- 10gradient descentalgorithm used to minimize cost function, USES gradients (partial derivates)
- 11initializationsetting initial weights and bias before training
- 12Lloss function (cost function)
- 13PProbability function (given value y)
- 14y-hatpredicted estimate value (output value)
- 15aactivation_function(weighted_sum+bias)
- 16Xdata input matrix
- 17Normalizationprocess of scaling and centering input data before feeding it into a neural network. The goal is to ensure that input features have similar scales and are centered around zero.
- 18dot operationdot product operation:
For two vectors: - 19outer product operationMultiply first element in array1 to EACH element in array 2. Then 2nd element to EACH element in array2 and so forth. Row width of array2 would determine row width of array2 from this operation. Column length of matrix would be determined by array1.
- 20elementwise operationcalculate (+,-,*,/) the first element of array1 with first element of array2. Then 2nd with 2nd, ect. Result should have a single array.
- 21interpret P(y=1!x)the probability that
y=1 given x - 22what mode of operation is c = a*bElementwise operation
- 23a=np.array([[2,1],[1,3]]) What is the result of a∗a?4,1
1,9
It is elementwise operation so 2 arrays[2,1],[1,3] get multiplied by each other - 24what are the digits in weights and bias? how about Z?for W 1st digit = current layer neurons
2nd digit = neurons in the previous layer
for bias 1st digit = current layer
2nd digit = 1.
for Z 1st digit = current layer neurons
2nd digit = ALWAYS the number of examples, regardless of which layer - 25When dealing with arrays, what is the shape of: [1,2,3,4] [1,2,3,4](2,3) 2 rows, 3 columns.
keep note, if there is only one dimension it is always (number of data,) where regardless of row or column it will always be (first number, then blank) - 26Cross-entropy costquantifies the difference between two probability distributions, the probability distribution and true distribution.
used as the cost function in the final layer when the activation function is a sigmoid function (for binary classification) or a softmax function (for multi-class classification). - 27dev setdevelopment set - portion of data used to help fine tune hyperparameters (learning rate, ect.) You train different algorithms on it to find which one works best.
When train set has low error and dev set has high error, that is high variance - 28RegularzationProcess to reduce variance from the dev set. (It is over fitting so this is what you should do)
- 29Forbenius normit's the square root of the sum of the squares of all the elements of the matrix
-used to quantify the complexity of a model or to regularize parameters during optimization. - 30Problem with overfittingmodel learns to perform very well on the training data but fails to generalize well to unseen data
- 31high biasThe model is getting a lot of errors compared to human error. To fix the problem your model network needs to be bigger/train longer (optimize more)/better nueral network architecture
- 32high varianceOverfitting is happening where it is capturing spcifically the training data set and not unknown data sets.
Solutrion is more data/Regularzation/better nueral network architecture - 33L2 regularzationW.T*W
(norm of W squared) - 34L1 Regularzationlamda/2m norm W
- 35keep.probWhen implementing dropout regularzation
- 36What to do when you need more dataTry inverting the picture/warping it/random zooms
- 37Steps to normalize training sets1) subtract X to the mean
2) set sigmoid activation function to 1/m summation X**2 (element wise multiplication)
3) x divided by the result of step 2