
Mapa mental
Classification
Conteúdo do mapa
Classification
Decision Tree
- Components
- Node
- Branch
- Leaves
- Functions
- Info Gain
- ensure how pure is an attribute
- Building Decision Tree with Information Gain Choose attribute with the highest information gain
- Highly-branching attributes
- Information gain is biased towards choosing attributes with a large number of values == This may result in over-fitting It means the tree is too much -> remove all primary key when analysing
- Info gain ratio
- reduce bias on highly branching attributes.
- makes number and size of branch into account
- Large: data evenly spread across the branches small: all data belongs to 1 branch
- Overcompensate
- Sometiems may not fix info gain problem with higly-branched attributes worse, may overcompenate, choosing attributes juz because their intrisic info is very low.
- To fix overcompensate: When building a tree: 1. Only consider attributes with greater than average info gain. 2. Remove ID codes like attributes 3. compare on gain ratio
- Remove ID codes like attributes
- info gain > average
- Compare gain ratio
- Gain Index
- Info Gain
- Industrial-strength algorithms
- For a learning algorithm to be useful in a wide-range of real-world applications it must Permit numeric attributes Allow missing values Be robust in the presence of noise Be able to approximate arbitrary concept descriptions
- Numeric Attributes
- Unlike nominal attributes where the value of each branch is clear, numeric attributes have many possible split points
- Sort by value
- Choose “best” split point
- Evaluate the goodness measures for every possible split point of attribute Choose “best” split point
- The goodness measure for that split point then becomes the goodness measure for the attribute
- Problems of binary splits
- not exhausted all info in the attribute
- may have to be tested several times along each path in the tree
- Makes tree harder o read
- Remedy
- Pre-discretize numeric attributes
- convert numeric to nominal
- Use multi-way splits instead of binary ones
- Pre-discretize numeric attributes
- Components
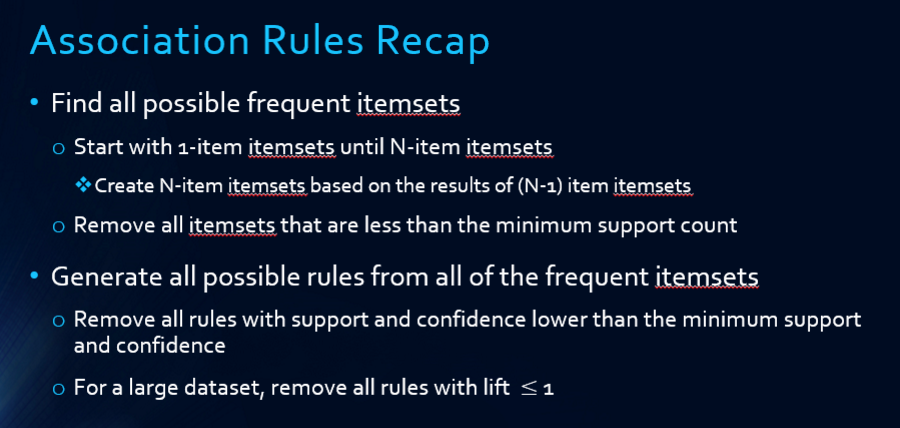
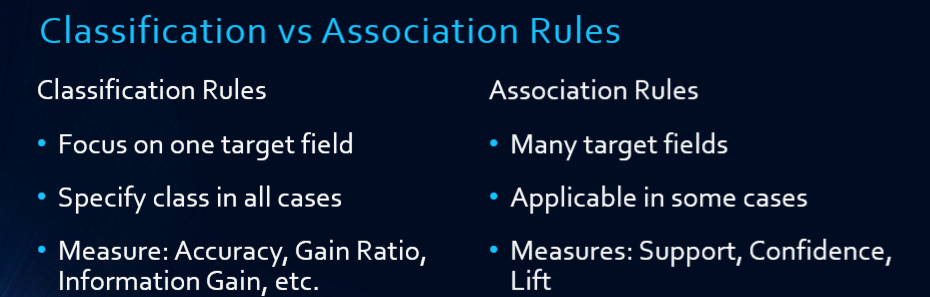
Association Rules
- Sometimes, you do not have a label that you would like to predict You would like to know the underlying patterns in your data Exploration
- You need unsupervised learning Clustering Association rules For example, to know the list of items that most people bought together in the supermarket
- Definition
- Find the most frequent patterns in the dataset
Naïve Bayes Classifier
- Assumption: All attributes are conditionally independent given the class label Y
- Cannot handle correlated attributes
- Calculate the conditional probability of each possible attribute value given a class label
- Missing & Numeric Data
- With Naïve Bayes No need to explicitly model the missing values Probabilities are calculated based on observed attributes
- With numeric data We need to estimate a mean, μik , and standard deviation σik based on the values of feature Xi in class yk in the training data
- Assumption: All attributes are conditionally independent given the class label Y
Laplace Smoothing
- avoid overfitting
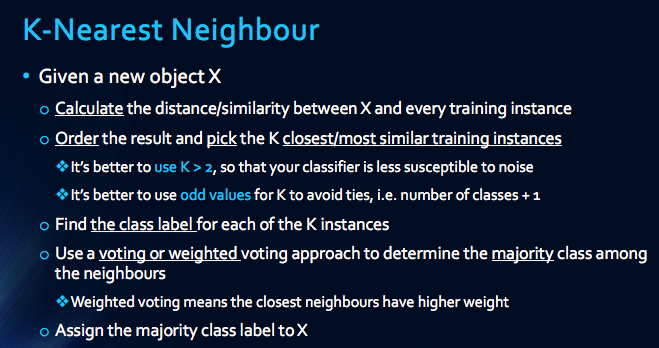
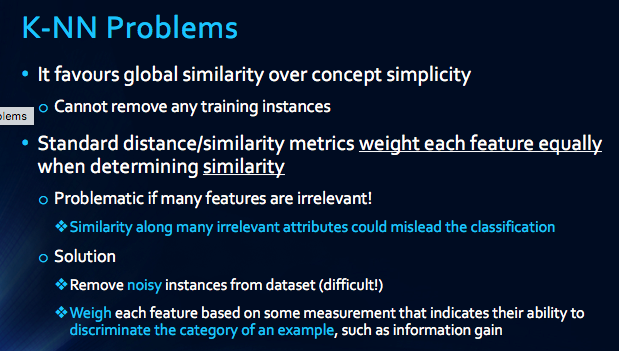
Instance-Based Learning
- known as: Case-based, Exemplar-based, Memory-based, Rote learning, Lazy learning, Nearest Neighbour
- Simple idea: label a new point the same as the label of the closest/most similar known point in the training set
- Simplest method but testing can be very expensive because we need to do detailed comparisons to all past training instances
- Similarity/Distance Metrics
- Euclidian distance
- Normalize value between 0 & 1
- Norminal attributes
- Euclidian distance
- Other Distance Metrics
- Dense data (few attributes with zero values)
- Euclidean Distance
- Correlation
- Used for Bioinformatics Data and Recommendation System
- Sparse data
- Cosinw Similarity
- Used for Information retrieval, Sentiment analysis
- Cosinw Similarity
- Dense data (few attributes with zero values)
- KNN
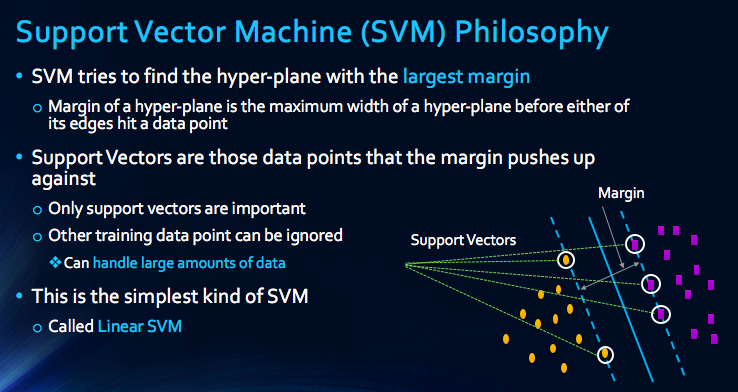
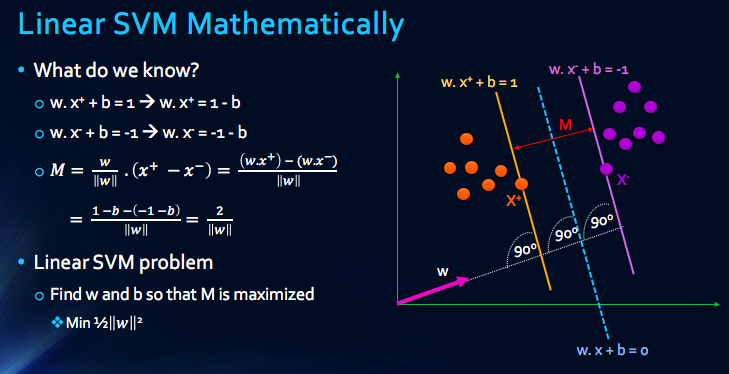
- SVM
- •Given a new point Y, find out its score oScore= w. Y + b If Score > Threshold, class = 1 If Score < (-1 * Threshold), class = -1 Otherwise, we don’t know
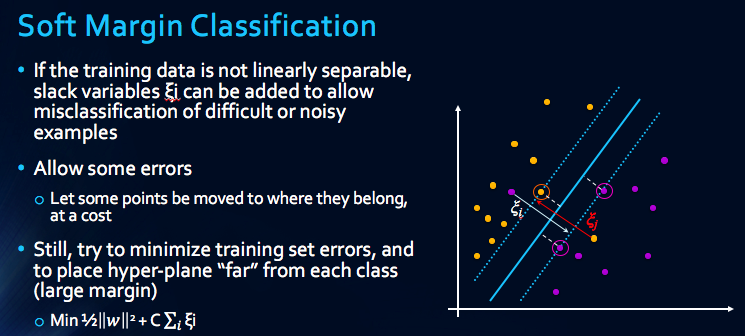
- Hard vs Soft Margin
- •Soft-margin oAlways have a solution oMore robust to outliers oSmoother surface •Hard-margin Requires guessing what the best cost parameter is
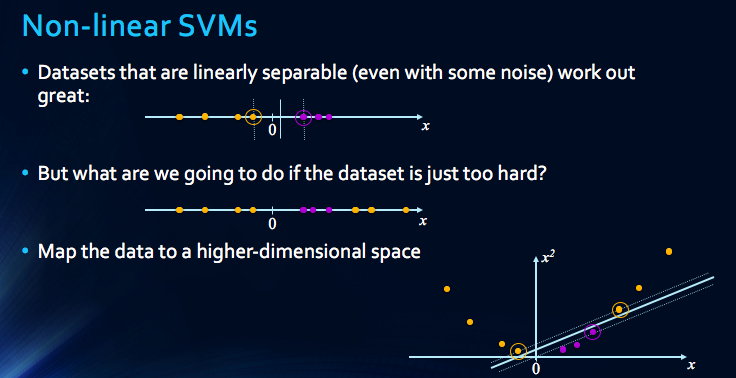
- Non-linear SVM
Imagens e arquivos do mapa
Informações
- Descrição
- Graduate diploma Graduate Diploma in Computing (Data Mining) Mapa Mental sobre Classification, criado por Freda Fung em 16-09-2016.
- Criado por
- Freda Fung
- Visualizações
- 0
- Avaliação